The content of this presentation is slightly adapted from the teaching material provided by Ségal Le Guern Herry who kindly shared his slide deck.
The creation of the slides was assisted with Claude Sonnet 5 and Chat-GPT 5.
What Will You Learn Here?
By the end of the course, you will be able to:
Prepare and transform data for visual analysis.
Create clear and effective visualizations using R.
Explore distributions and compare groups.
Produce maps and interactive visualizations.
Communicate results through reproducible reports and interactive dashboards.
Grading
3 assignments, by group of 2, given 2 weeks in advance
First assignment: due October 28, 2026
Second assignment: due November 25, 2026
Third assignment: due by January 27, 2027.
Who are you?
Background
Expectations from this class
Any experience in coding (R, python, Stata…)
Roadmap
Today: 3 hours, we will do our best to cover everything. If we run out of time, we will finish at the start of the next session.
Introduction: why data visualization matters
When Visualization Goes Wrong: a gallery of real, misleading, or manipulated charts, including inverted axes, truncated axes, dual axes, arbitrary scales, and poor binning choices
Some Rules for Good Practices: three concrete principles: proportional ink, showing the data, and reducing clutter
Perception: the cognitive foundations, pre-attentive processing and Gestalt principles, to understand why these rules work.
Introduction
A Bit of Reading
Most of the content of this introduction is from the following three resources.
Chapter 7 of Bergstrom, C. T., & West, J. D. (2020). Calling Bullshit: The Art of Skepticism in a Data-Driven World. Random House.
Chapter 1 of Healy, K. (2026). Data Visualization: A Practical Introduction (2nd ed.). Princeton University Press. https://socviz.co/01-look-at-data.html
Schwabish, J. A. (2014). An economist’s guide to visualizing data. Journal of Economic Perspectives, 28(1), 209–234.
The Founder of Graphical Methods of Statistics
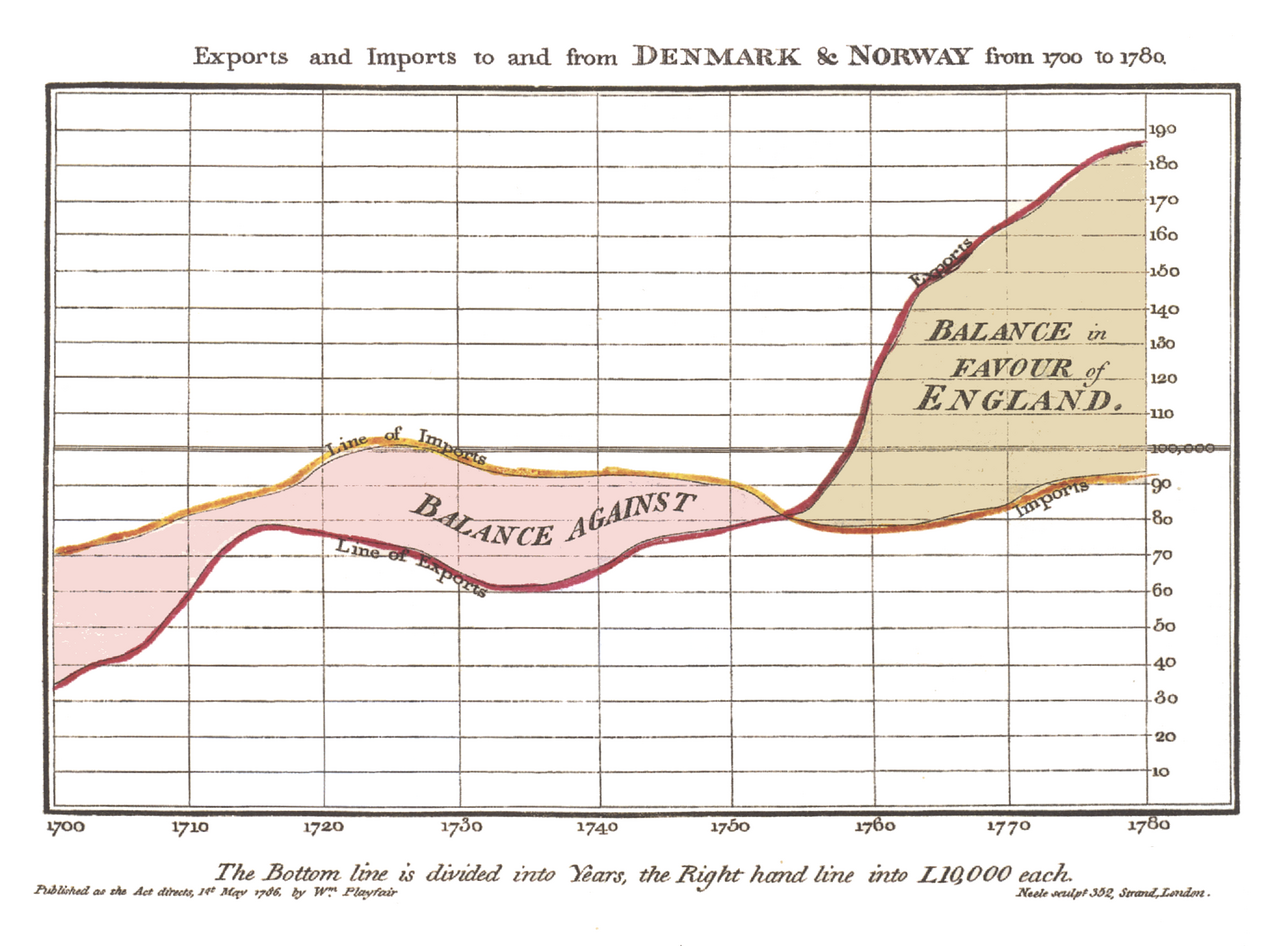
Data visualization used by researchers since 18th century
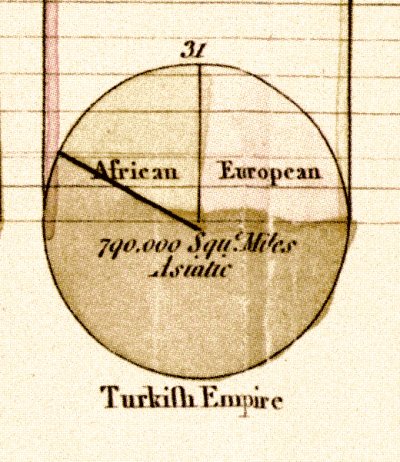
William Playfair (1759-1823) as a pioneer (area, bar, pie charts)
By William Playfair (1759–1823) - Scanned from the book “The Commercial and Political Atlas and Statistical Breviary”, Cambridge University Press 2005. ISBN 0-521-85554-3., Public Domain, https://commons.wikimedia.org/w/index.php?curid=1627651
Previously, producing and distributing a chart required access to specialized institutions (newspapers, publishers, academic journals, government agencies).
The Internet dramatically lowered these barriers.
Anyone with data and basic visualization tools can now create and publish a chart.
Social media allows visualizations to reach large audiences without traditional intermediaries.
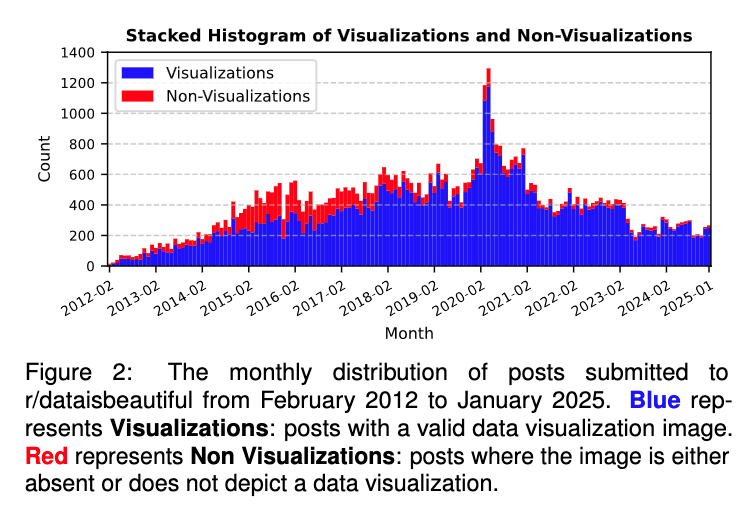
Graphs represent a mainstream appeal. There are Over 20+ million members on this subreddit (as of 2026), with about 1 million weekly viewers, sharing and debating charts.
The activity there is massive, with thousands of community submissions per month (economics, sports, science)
Data visualization is no longer exclusively a specialist practice. It has become a form of mass communication.
Growth of monthly posts on r/dataisbeautiful (Source: Lin et al. (2026))
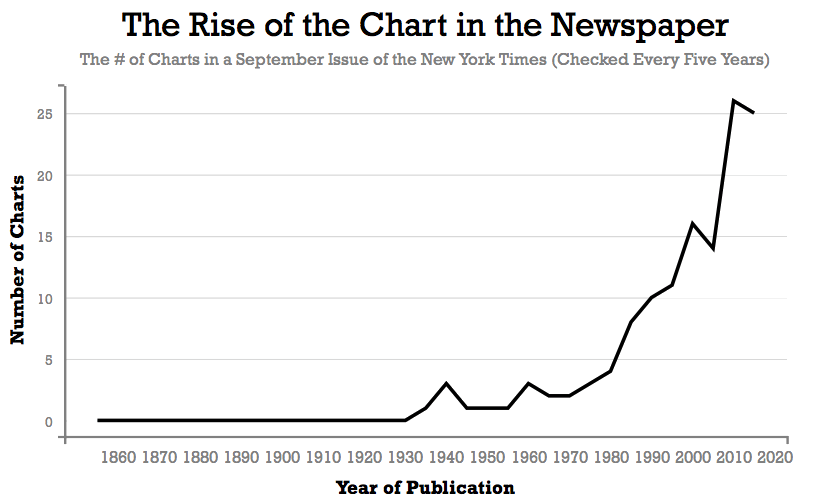
The Rise of Data Journalism
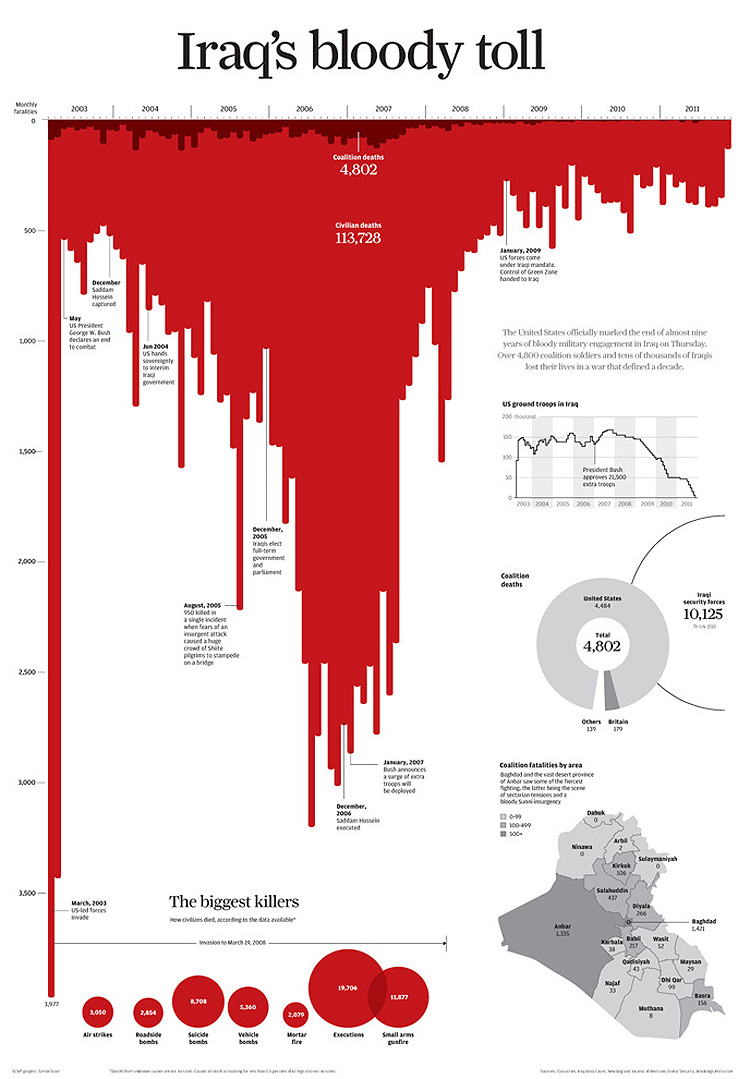
Charts became more and more sophisticated. Modern graphics have evolved far beyond basic bar and pie charts into interactive multi-layered visuals.
Major newsrooms (such as The New York Times, Le Monde, The Guardian) now employ (large) dedicated teams of data visualization experts.
Downsides:
Readers often struggle to accurately decode complex or unconventional graphs.
High sophistication creates ample room for manipulation: misleading scales, cherry-picked data, or subtle visual deception.
If everyone can make a chart, how do we know whether a chart is telling us something meaningful?
This class is not just about creating effective visuals, it is also about developing a critical eye to spot misleading graphics.
When Visualization Goes Wrong
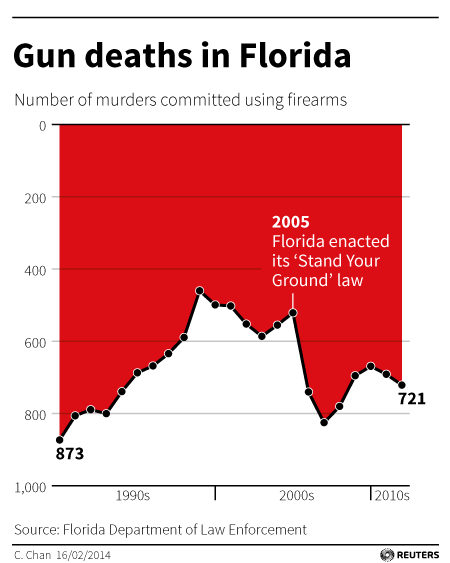
The “Stand Your Ground” Law
Florida’s “Stand Your Ground” law was introduced as a Senate bill in 2005 and enacted that same year.
The law expanded the circumstances under which a person could use deadly force in self-defense without a duty to retreat.
Its effects became the subject of substantial public and political debate:
some claiming it would reduce crimes,
other replying it would lead to an increase in lethal force.
The “Stand Your Ground” Law
At a glance…
Look at this chart for a few seconds.
What is your first impression? Did gun murders in Florida go up or down after 2005?
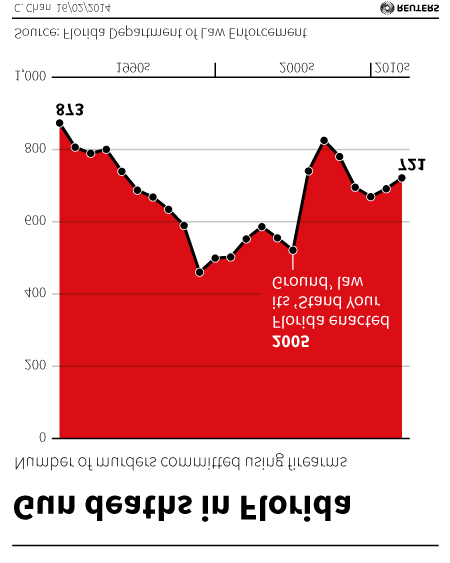
This Reuters graphic published in 2014 has become infamous for its inverted y-axis, which makes an increase in gun murders appear visually as a decline.
Same graph, with the y-axis restored to the conventional orientation.
A Truncated Y-axis
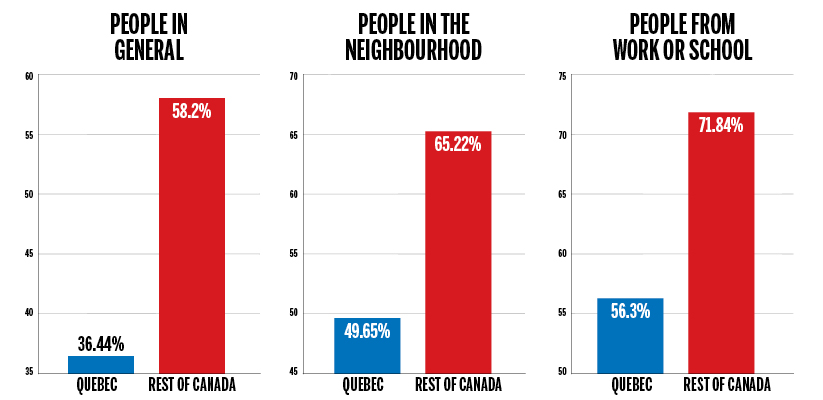
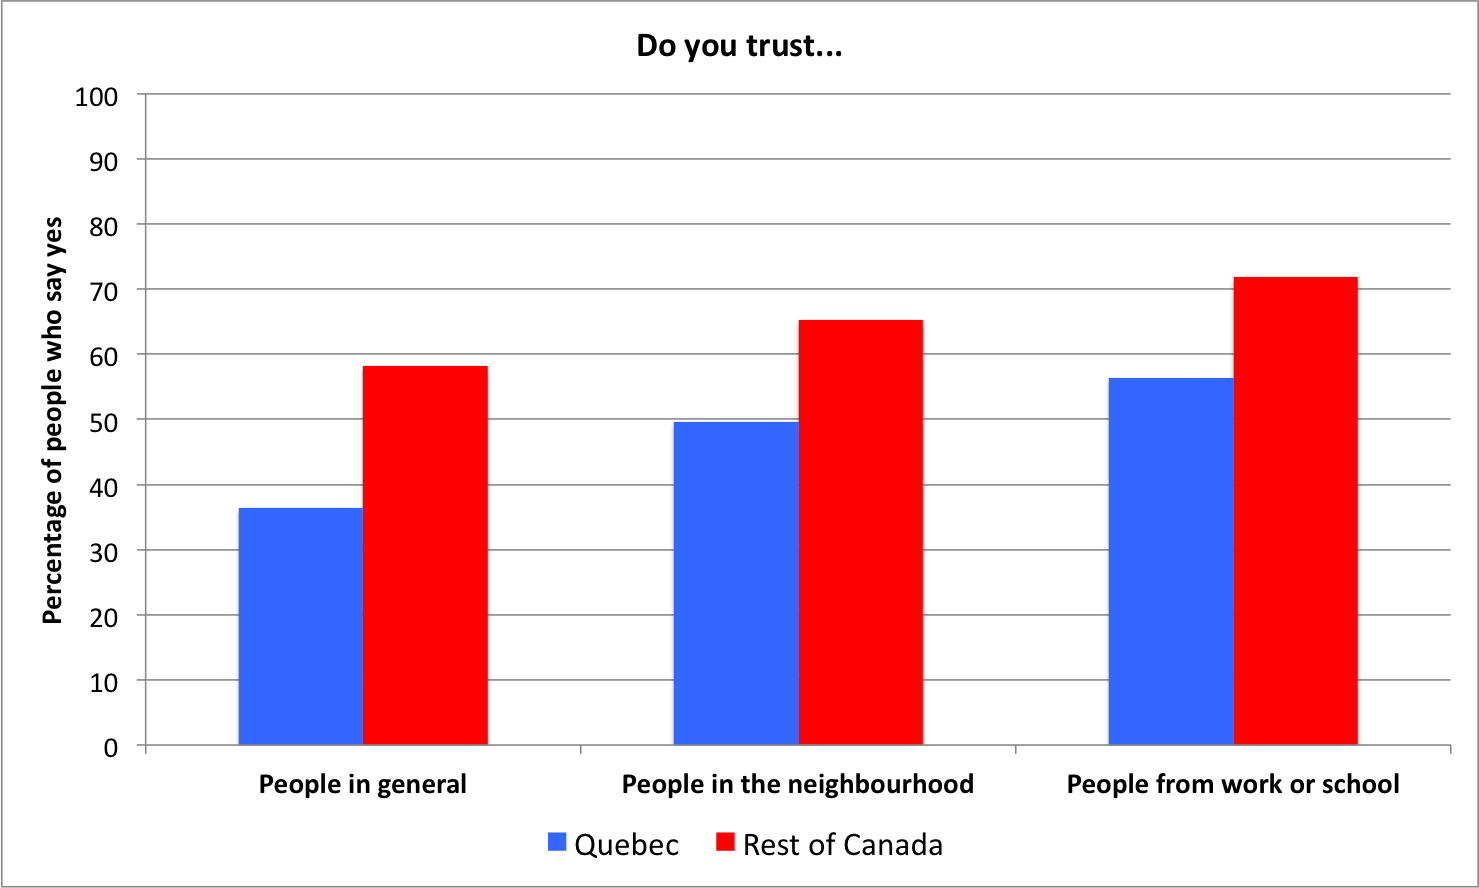
A second infamous example involves a bar chart published by Maclean’s in 2017, alongside a column by Andrew Potter about social capital in Quebec compared to the rest of Canada.
The column argued that Quebec was distinctively low in measures of social trust and civic engagement.
“Compared to the rest of the country, Quebec is an almost pathologically alienated and low-trust society, deficient in many of the most basic forms of social capital that other Canadians take for granted.” (Source: Potter (2017))
At a glance…
Look at this original chart for a few seconds. Does anything about it strike you as unconventional?
The chart’s y-axis does not begin at zero, making relatively modest differences between Quebec and the rest of Canada appear much larger than they actually are.
Yang et al. (2021) showed, through an experimentation, that y-axis truncation for bar charts leads viewers to perceive illustrated differences as larger than they actually are:
83.5% of participants across studies show a truncation effect,
the effect persists even when the truncation technique is explained before showing the graphs.
Should we Always Include Zero?
Line Graph
Code
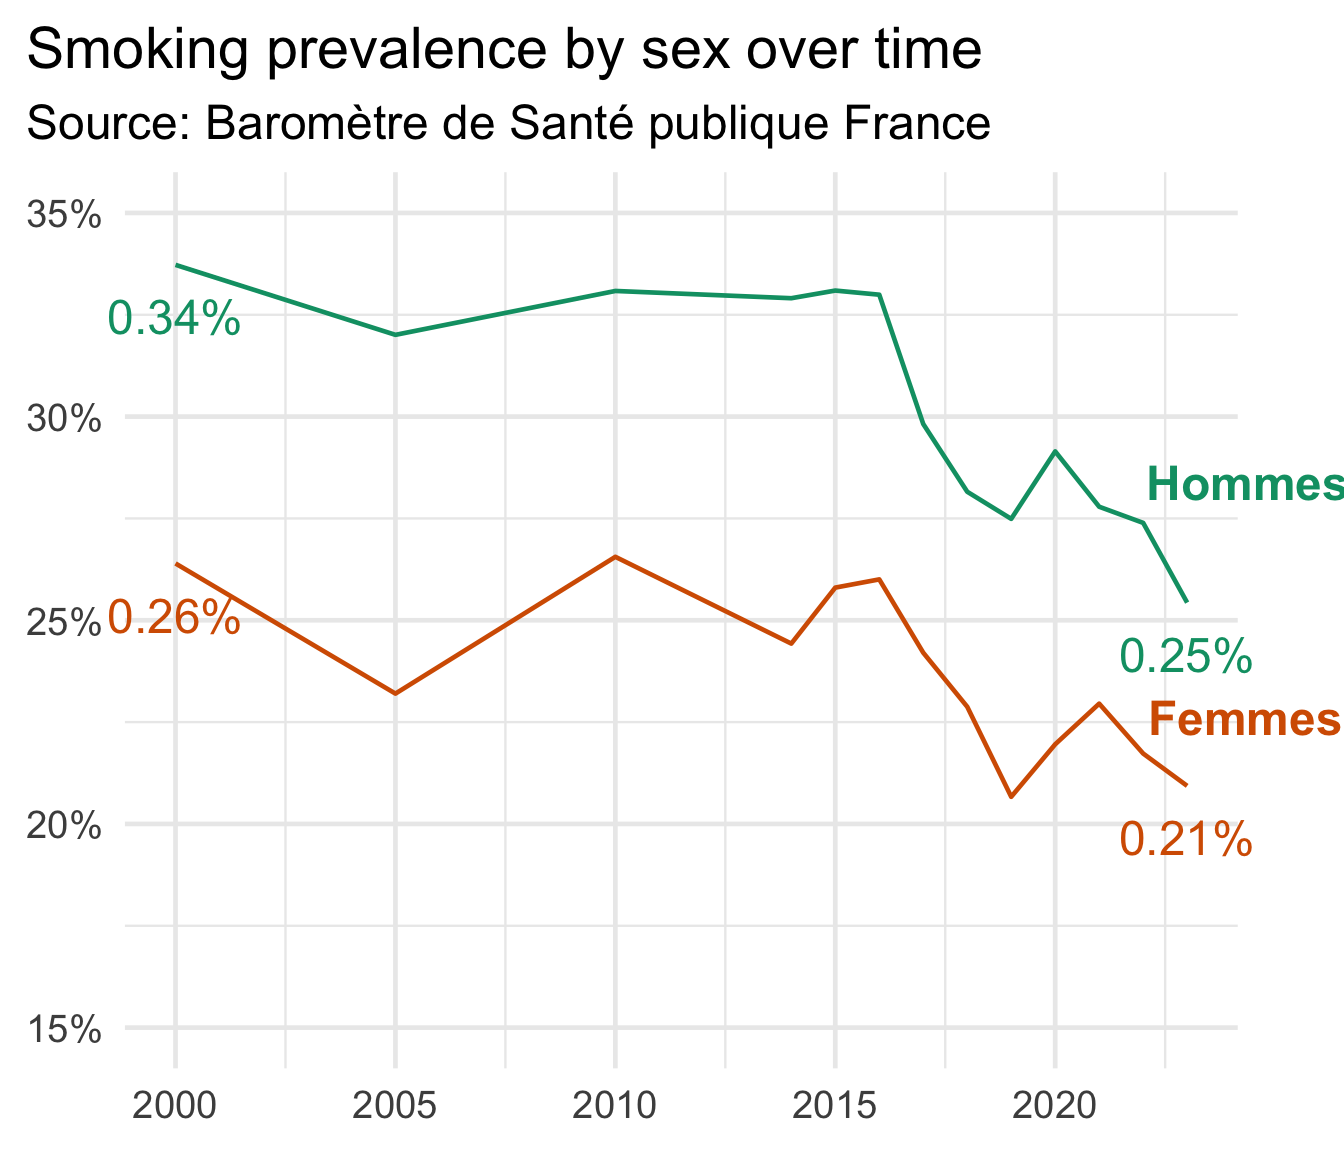
library(tidyverse)# Tabac : Prévalence selon le sexe# Source: Santé publique France# Odissé, ref tabagisme-prevalence-selon-le-sexetabagisme <-read_csv("data/tabac/tabagisme-prevalence-selon-le-sexe.csv")tabagisme_endpoints <- tabagisme |>filter(Sexe !="Hommes et Femmes") |>group_by(Sexe) |>filter(Année ==min(Année) | Année ==max(Année)) |>ungroup() |>mutate(`Taux de prévalence`=`Taux de prévalence`/100)tabagisme_labels <- tabagisme |>filter(Sexe !="Hommes et Femmes") |>mutate(`Taux de prévalence`=`Taux de prévalence`/100) |>group_by(Sexe) |>filter(Année ==max(Année)) |>ungroup()ggplot(data = tabagisme |>filter(Sexe !="Hommes et Femmes") |>mutate(`Taux de prévalence`=`Taux de prévalence`/100),mapping =aes(x = Année, y =`Taux de prévalence`, colour = Sexe)) +geom_line() +geom_text(data = tabagisme_endpoints,mapping =aes(label =paste0(round(`Taux de prévalence`, 2), "%")),vjust =2,show.legend =FALSE ) +geom_text(data = tabagisme_labels |>mutate(vjust_val =c(-3, -1.5)),mapping =aes(label = Sexe, colour = Sexe, vjust = vjust_val),hjust =0.2,fontface ="bold",show.legend =FALSE ) +scale_colour_manual(values =c("Femmes"="#D55E00", "Hommes"="#009E73"), ) +theme_minimal(base_size =18) +theme(legend.position ="none") +scale_y_continuous(labels = scales::percent, limits =c(15, 35)/100) +coord_cartesian(clip ="off") +theme(plot.margin =margin(t =10, r =40, b =10, l =10), plot.title.position ="plot") +labs(x =NULL, title ="Smoking prevalence by sex over time", y =NULL,subtitle ="Source: Baromètre de Santé publique France" )
Does this graph look OK to you?
Line Graph: starting at 0?
Code
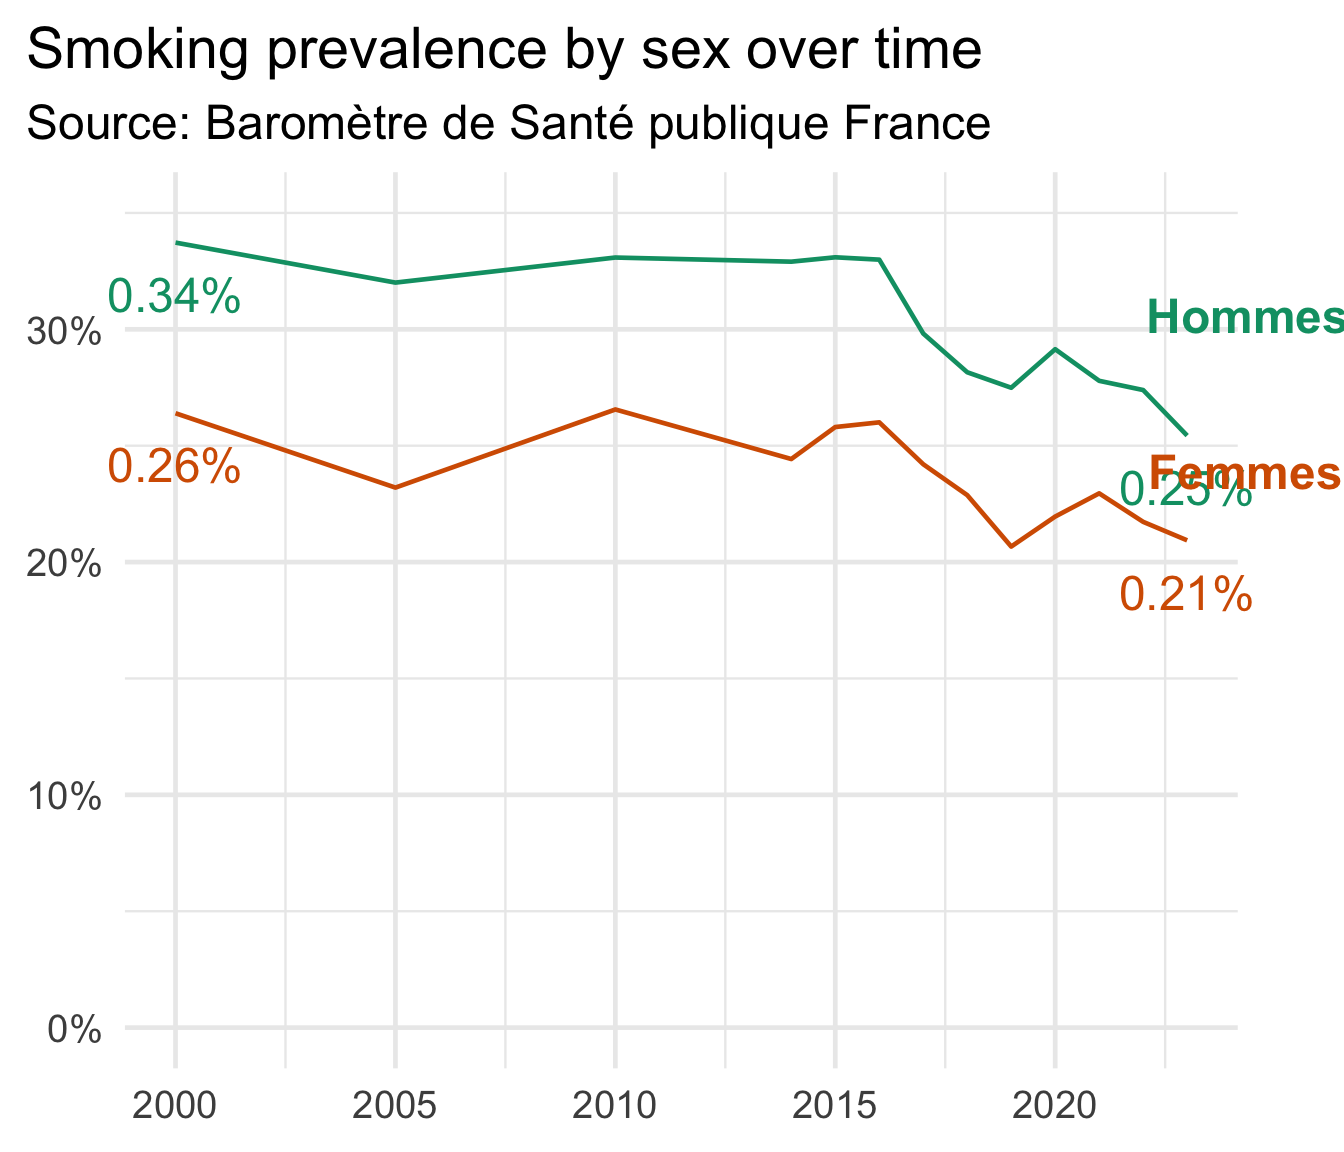
ggplot(data = tabagisme |>filter(Sexe !="Hommes et Femmes") |>mutate(`Taux de prévalence`=`Taux de prévalence`/100),mapping =aes(x = Année, y =`Taux de prévalence`, colour = Sexe)) +geom_line() +geom_text(data = tabagisme_endpoints,mapping =aes(label =paste0(round(`Taux de prévalence`, 2), "%")),vjust =2,show.legend =FALSE ) +geom_text(data = tabagisme_labels |>mutate(vjust_val =c(-3, -1.5)),mapping =aes(label = Sexe, colour = Sexe, vjust = vjust_val),hjust =0.2,fontface ="bold",show.legend =FALSE ) +scale_colour_manual(values =c("Femmes"="#D55E00", "Hommes"="#009E73"), ) +theme_minimal(base_size =18) +theme(legend.position ="none") +scale_y_continuous(labels = scales::percent, limits =c(0, 35)/100) +coord_cartesian(clip ="off") +theme(plot.margin =margin(t =10, r =40, b =10, l =10), plot.title.position ="plot") +labs(x =NULL, title ="Smoking prevalence by sex over time", y =NULL,subtitle ="Source: Baromètre de Santé publique France" )
Including 0 on the y-axis is not useful here.
The objective of the graph is toemphasize changes over time for each gender.
Why not using errorbars here?
Code
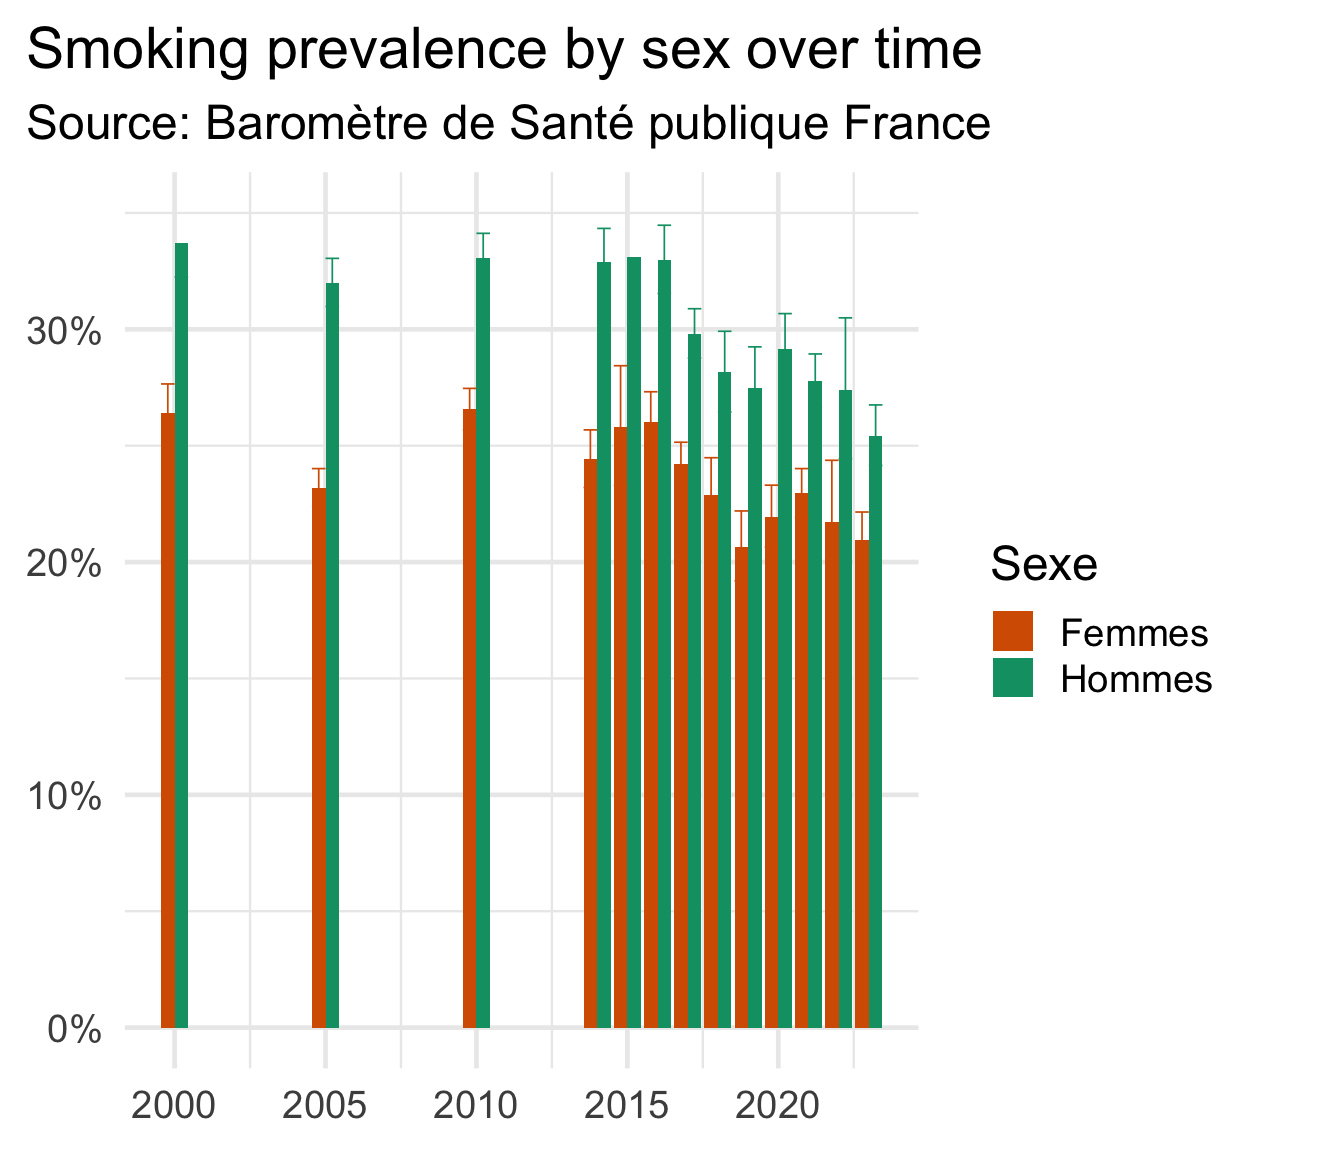
ggplot(data = tabagisme |>filter(Sexe !="Hommes et Femmes") |>mutate(`Taux de prévalence`=`Taux de prévalence`/100,lwr =`Intervalle de confiance : Borne inférieure`/100,upr =`Intervalle de confiance : Borne supérieure`/100 ),mapping =aes(x = Année, y =`Taux de prévalence`, fill = Sexe)) +geom_bar(stat ="identity", position ="dodge") +geom_errorbar(mapping =aes(ymin = lwr, ymax = upr, colour = Sexe),position ="dodge",linewidth =0.3 ) +scale_fill_manual(values =c("Femmes"="#D55E00", "Hommes"="#009E73")) +scale_colour_manual(values =c("Femmes"="#D55E00", "Hommes"="#009E73")) +theme_minimal(base_size =18) +scale_y_continuous(labels = scales::percent, limits =c(0, 35)/100) +coord_cartesian(clip ="off") +theme(plot.margin =margin(t =10, r =40, b =10, l =10), plot.title.position ="plot") +labs(x =NULL, title ="Smoking prevalence by sex over time", y =NULL,subtitle ="Source: Baromètre de Santé publique France" )
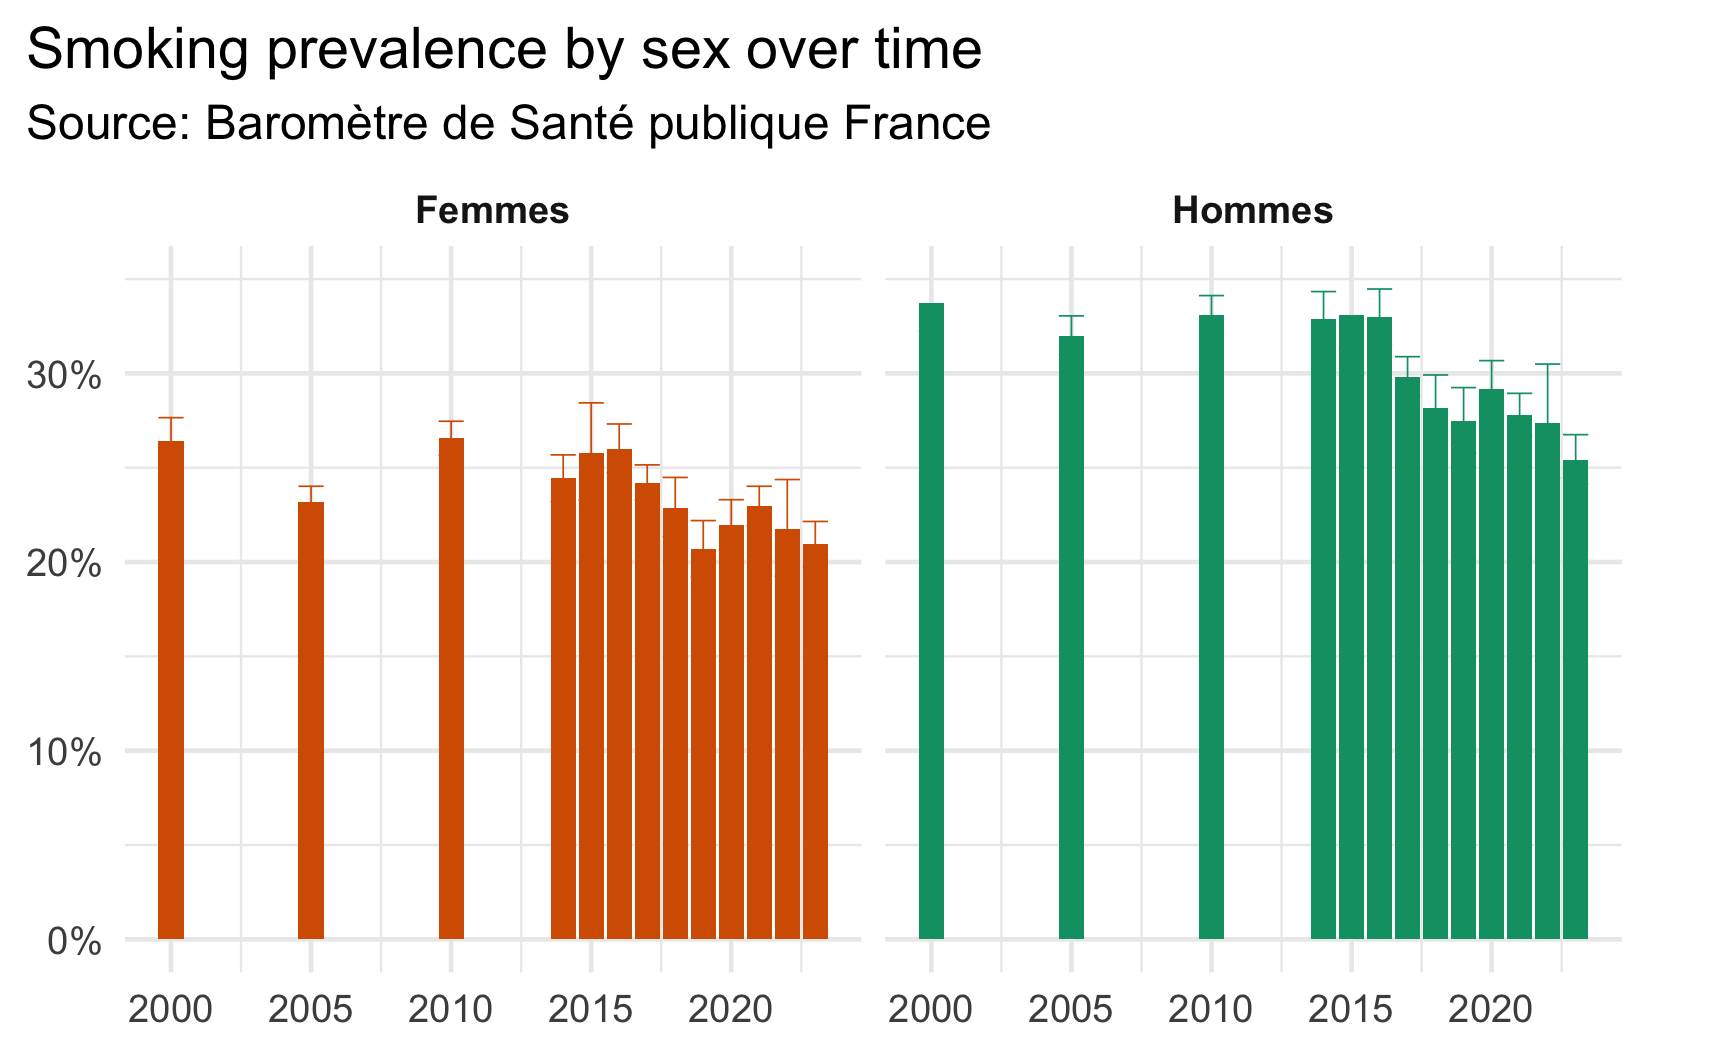
too many years × 2 groups makes the bars illegible and the error bars unreadable/overlapping
Even a Faceted Version is not Right
Code
ggplot(data = tabagisme |>filter(Sexe !="Hommes et Femmes") |>mutate(`Taux de prévalence`=`Taux de prévalence`/100,lwr =`Intervalle de confiance : Borne inférieure`/100,upr =`Intervalle de confiance : Borne supérieure`/100 ),mapping =aes(x = Année, y =`Taux de prévalence`, fill = Sexe)) +geom_bar(stat ="identity", position ="dodge") +geom_errorbar(mapping =aes(ymin = lwr, ymax = upr, colour = Sexe),position ="dodge",linewidth =0.3 ) +scale_fill_manual(values =c("Femmes"="#D55E00", "Hommes"="#009E73")) +scale_colour_manual(values =c("Femmes"="#D55E00", "Hommes"="#009E73")) +theme_minimal(base_size =18) +scale_y_continuous(labels = scales::percent, limits =c(0, 35)/100) +coord_cartesian(clip ="off") +theme(plot.margin =margin(t =10, r =40, b =10, l =10), plot.title.position ="plot",legend.position ="none",strip.text =element_text(face ="bold") ) +labs(x =NULL, title ="Smoking prevalence by sex over time", y =NULL,subtitle ="Source: Baromètre de Santé publique France" ) +facet_wrap(~Sexe)
Here, splitting fixes overlap,
But direct comparison is now harder as eyes must jump between panels.
Scales Matter
The Earth is warming
Code
library(ncdf4)library(tidyverse)if (1==0) {# Source: https://berkeleyearth.org/data/# High-Resolution Global Monthly Average Temperature, 5° x 5° Resolution Field nc_file <-"data/temp/Global_TAVG_Gridded_5deg.nc" nc <-nc_open(nc_file) latitude <-ncvar_get(nc, "latitude") longitude <-ncvar_get(nc, "longitude") time <-ncvar_get(nc, "time") temperature <-ncvar_get(nc, "temperature") # anomaly, dims: lon x lat x time climatology <-ncvar_get(nc, "climatology") # baseline, dims: lon x lat x month (12)nc_close(nc) n_lon <-length(longitude) n_lat <-length(latitude) n_time <-length(time) year <-floor(time) month <-round((time - year) *12) +1# Area weights (cos of latitude) weights_lat <-cos(latitude * pi /180) weights_lat[weights_lat <0] <-0 weight_matrix <-matrix(rep(weights_lat, each = n_lon), nrow = n_lon, ncol = n_lat)# Global average ANOMALY per time step (robust to coverage change) global_avg_anomaly <-numeric(n_time)for (t in1:n_time) { slice <- temperature[, , t] valid <-!is.nan(slice) global_avg_anomaly[t] <-sum(slice[valid] * weight_matrix[valid]) /sum(weight_matrix[valid]) }# Fixed global mean climatology per calendar month# Use ONLY cells with valid climatology in ALL 12 months, so the same# reference grid is used regardless of which cells later drop in/out# in the anomaly field. fixed_mask <-apply(climatology, c(1, 2), function(x) all(!is.nan(x))) global_mean_climatology_by_month <-numeric(12)for (m in1:12) { clim_slice <- climatology[, , m] global_mean_climatology_by_month[m] <-sum( clim_slice[fixed_mask] * weight_matrix[fixed_mask] ) /sum(weight_matrix[fixed_mask]) }# Reconstruct global average ACTUAL temperature global_avg_actual <- global_avg_anomaly + global_mean_climatology_by_month[month]# Combine into tibble dates <-as.Date(paste(year, month, "15", sep ="-")) global_temp_tb <-tibble(date = dates,time_decimal = time,global_avg_anomaly = global_avg_anomaly,global_avg_actual = global_avg_actual )save(global_temp_tb, file ="data/temp/global_temp_tb.rda")} else {# Load previously obtained results to save compilation timeload("data/temp/global_temp_tb.rda")}p_temp <-ggplot(data = global_temp_tb |>mutate(year = lubridate::year(date)) |>group_by(year) |>summarise(global_avg_actual =mean(global_avg_actual)), mapping =aes(x = year, y = global_avg_actual)) +geom_line() +labs(x =NULL, y ="Temperature (°C)",title ="Global Average Absolute Temperature, 1850–present",subtitle ="Source: Berkeley Earth" ) +theme_minimal(base_size =16)p_temp
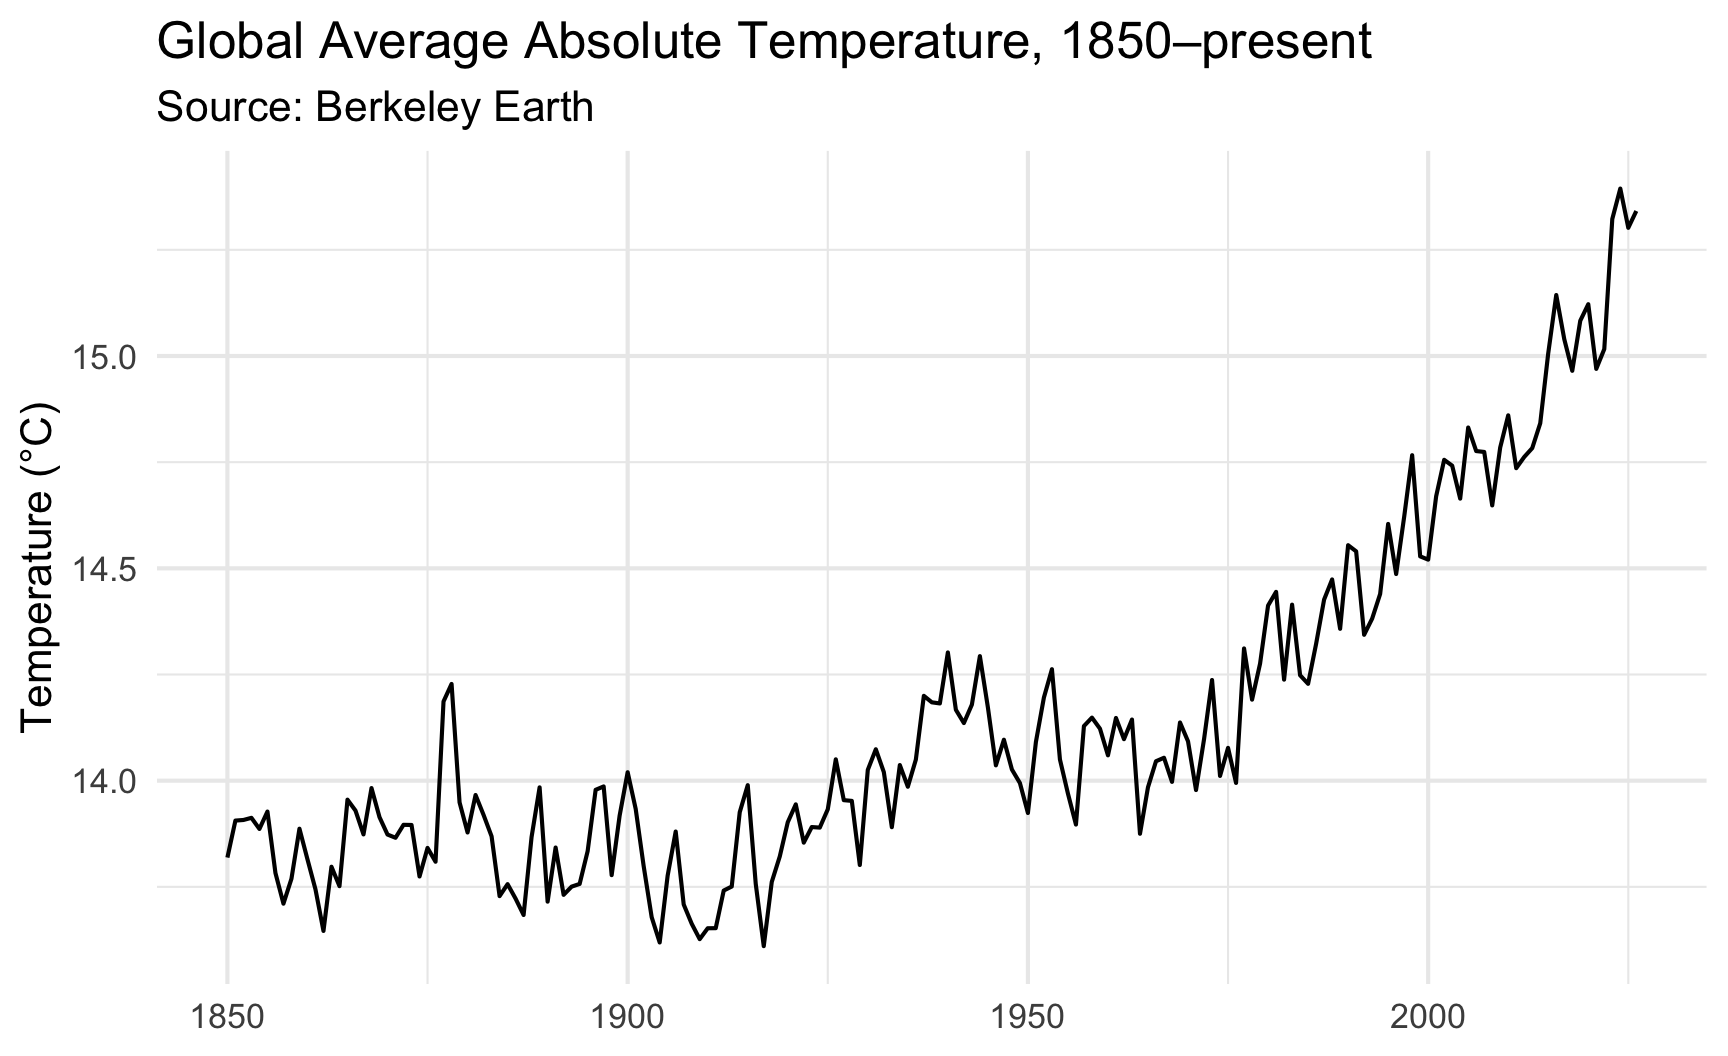
Example from Hayward (2015) through Glasbrenner (2018)
Here, the line looks dramatic: we observe a steep rise.
Look closely at the y-axis: what range does it actually span?
Same Data, Different Y-axis Range
Code
p_temp +scale_y_continuous(limits =c(-10, 30))
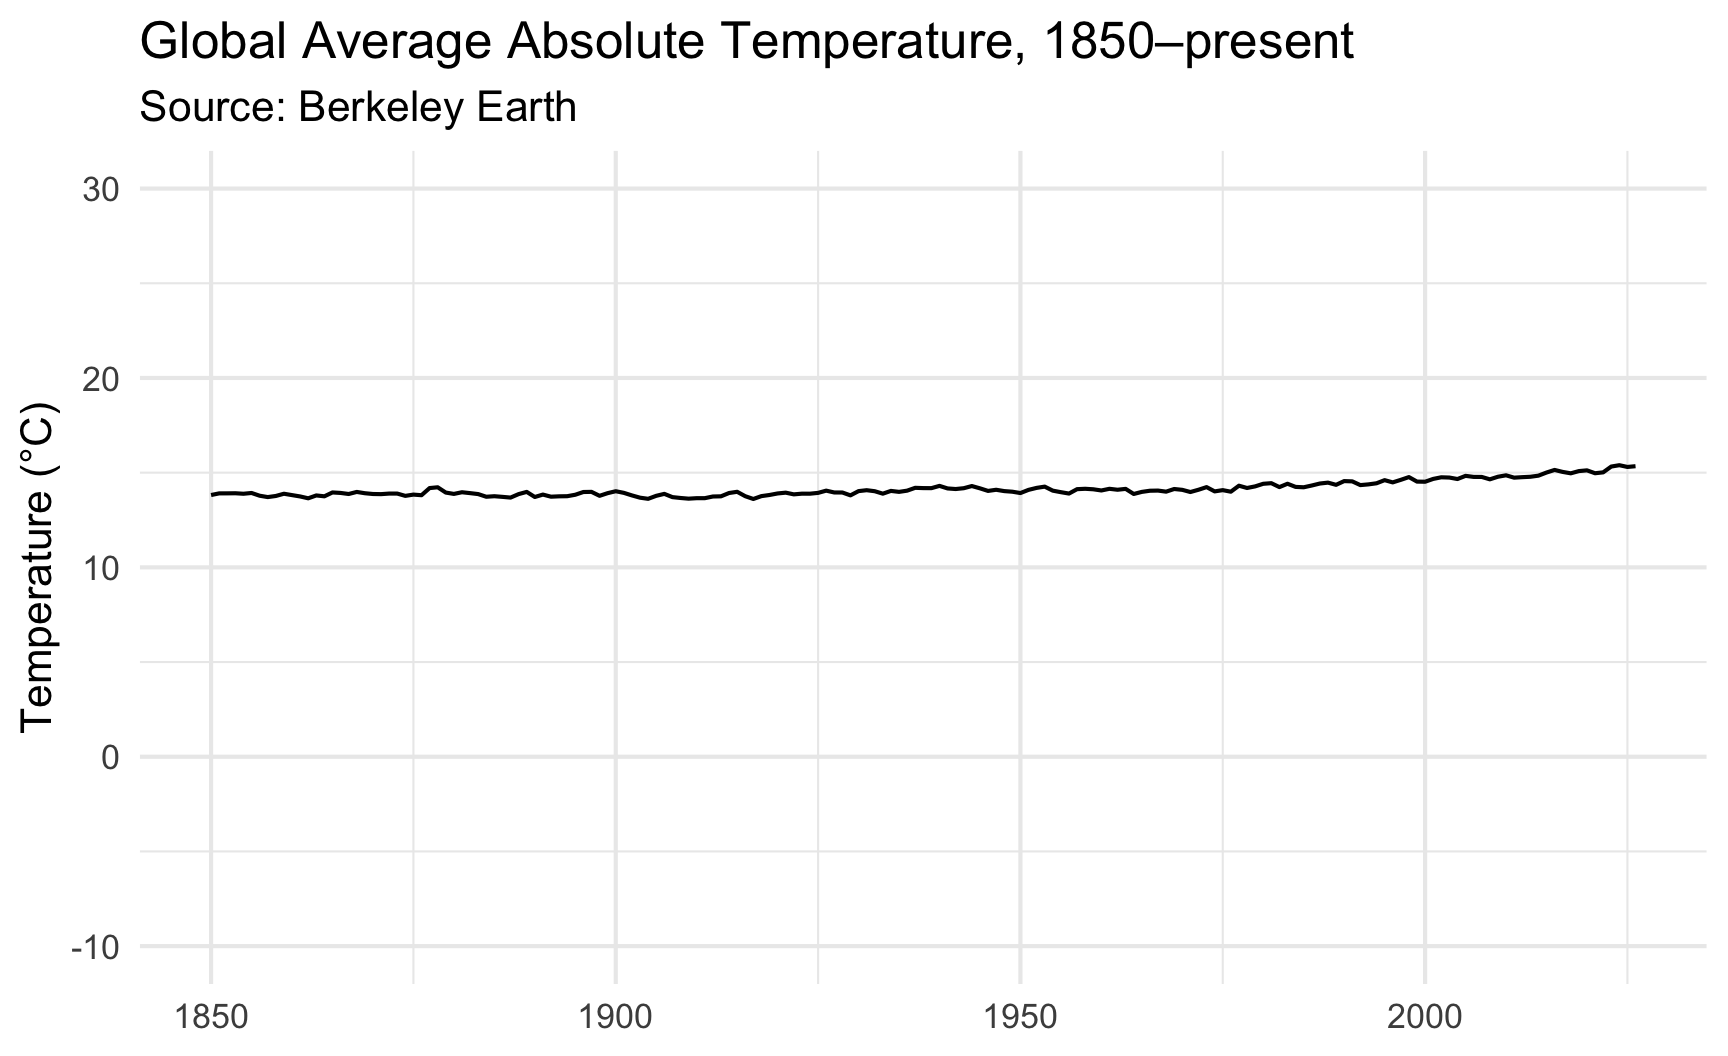
Same exact data, same exact curve.
Only the y-axis limits changed.
The dramatic-looking trend from the previous slide now looks almost flat.
Warning
Neither version is “wrong” mathematically, but each creates a completely different visual impression of the same underlying data.
The Honest Fix Here: Show the Anomaly, Not the Level
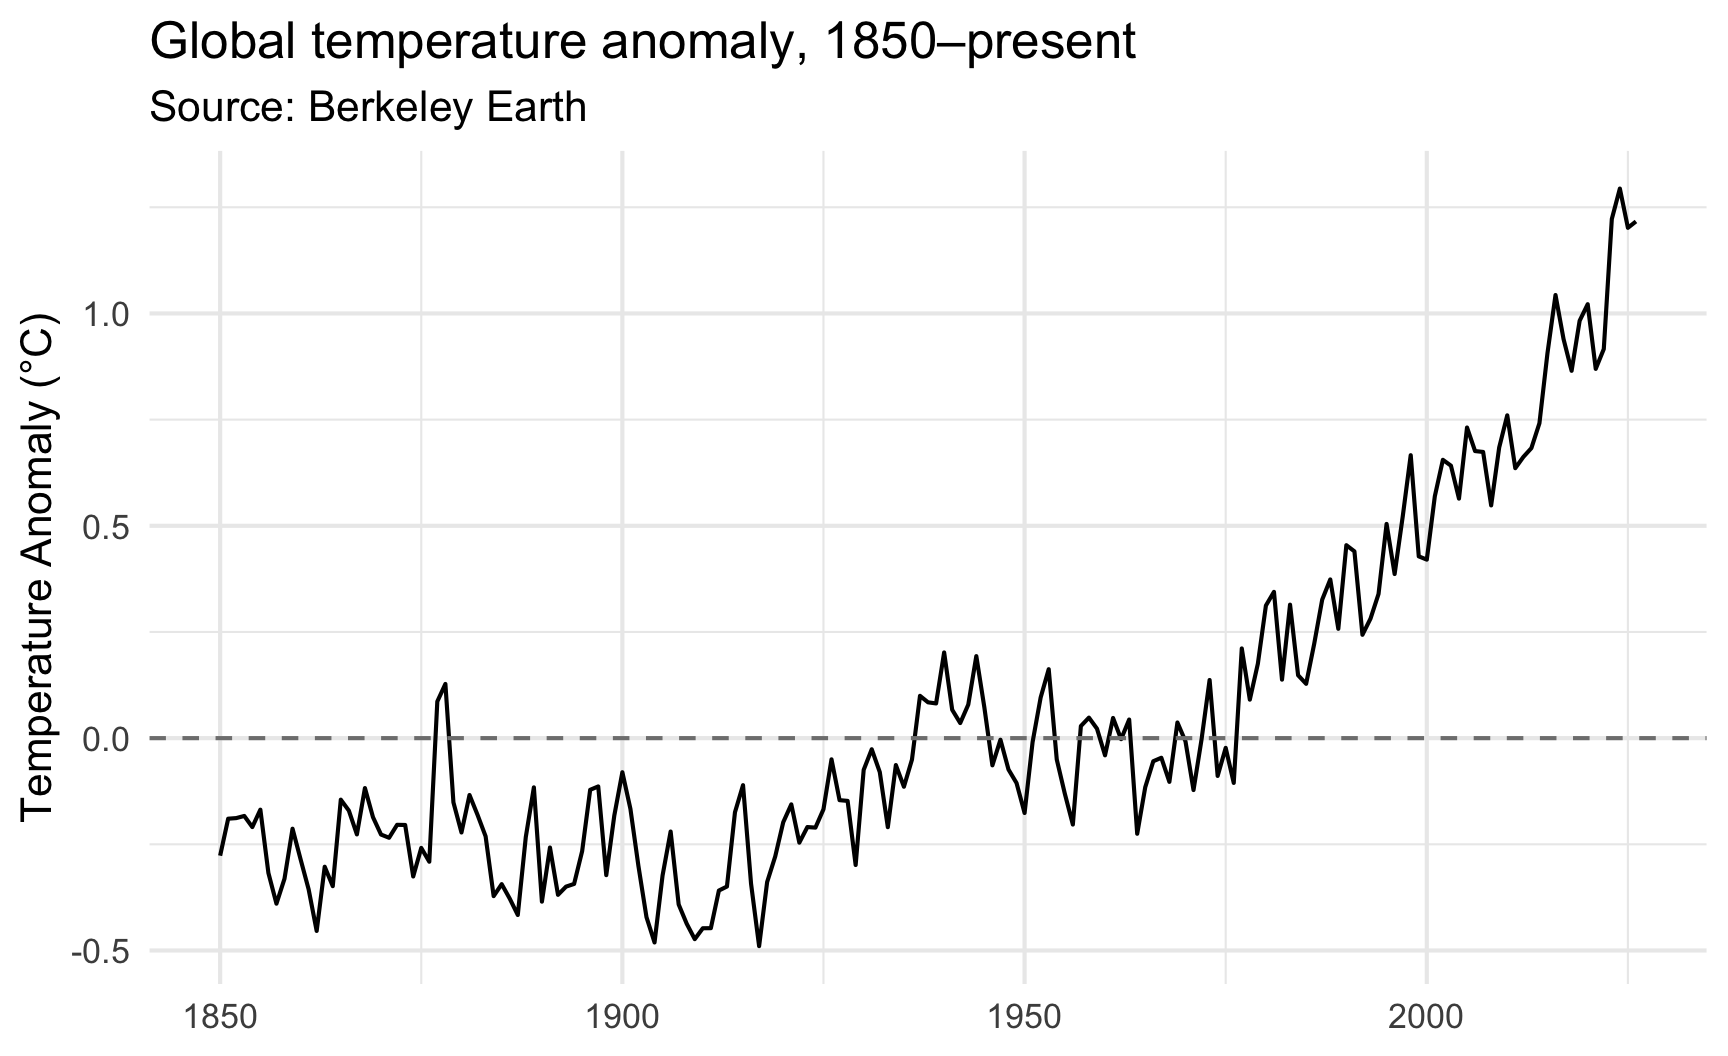
Rather than debating “what should the y-axis limits be?”, change the quantity being plotted.
The anomaly (departure from a reference climatology) is the standard way climate scientists communicate this data, because it:
is naturally centred around 0,
is less sensitive to an arbitrary choice of y-axis range,
sidesteps the scale debate entirely.
Tips
Tip
When a variable’s absolute level is not meaningful on its own (or its “natural” scale is ambiguous), consider whether a relative measure (anomaly, percent change, index, z-score) tells the story more robustly.
A Small Number Is Not a Small Effect
Be careful: an anomaly plot that looks visually modest can still represent a dramatic change (with high stakes).
According to IPCC reports, even a difference of 1°C in global average temperature is associated with substantial consequences: shifting precipitation patterns, increased frequency of extreme heat events, sea level rise, and ecosystem disruption.
The right scale for the y-axis depends on the story you are telling and on the real-world stakes of the quantity being measured, not just on statistical convention.
The X-axis May Also Be Wrong
Scales Matter: Uneven Time Intervals
Code
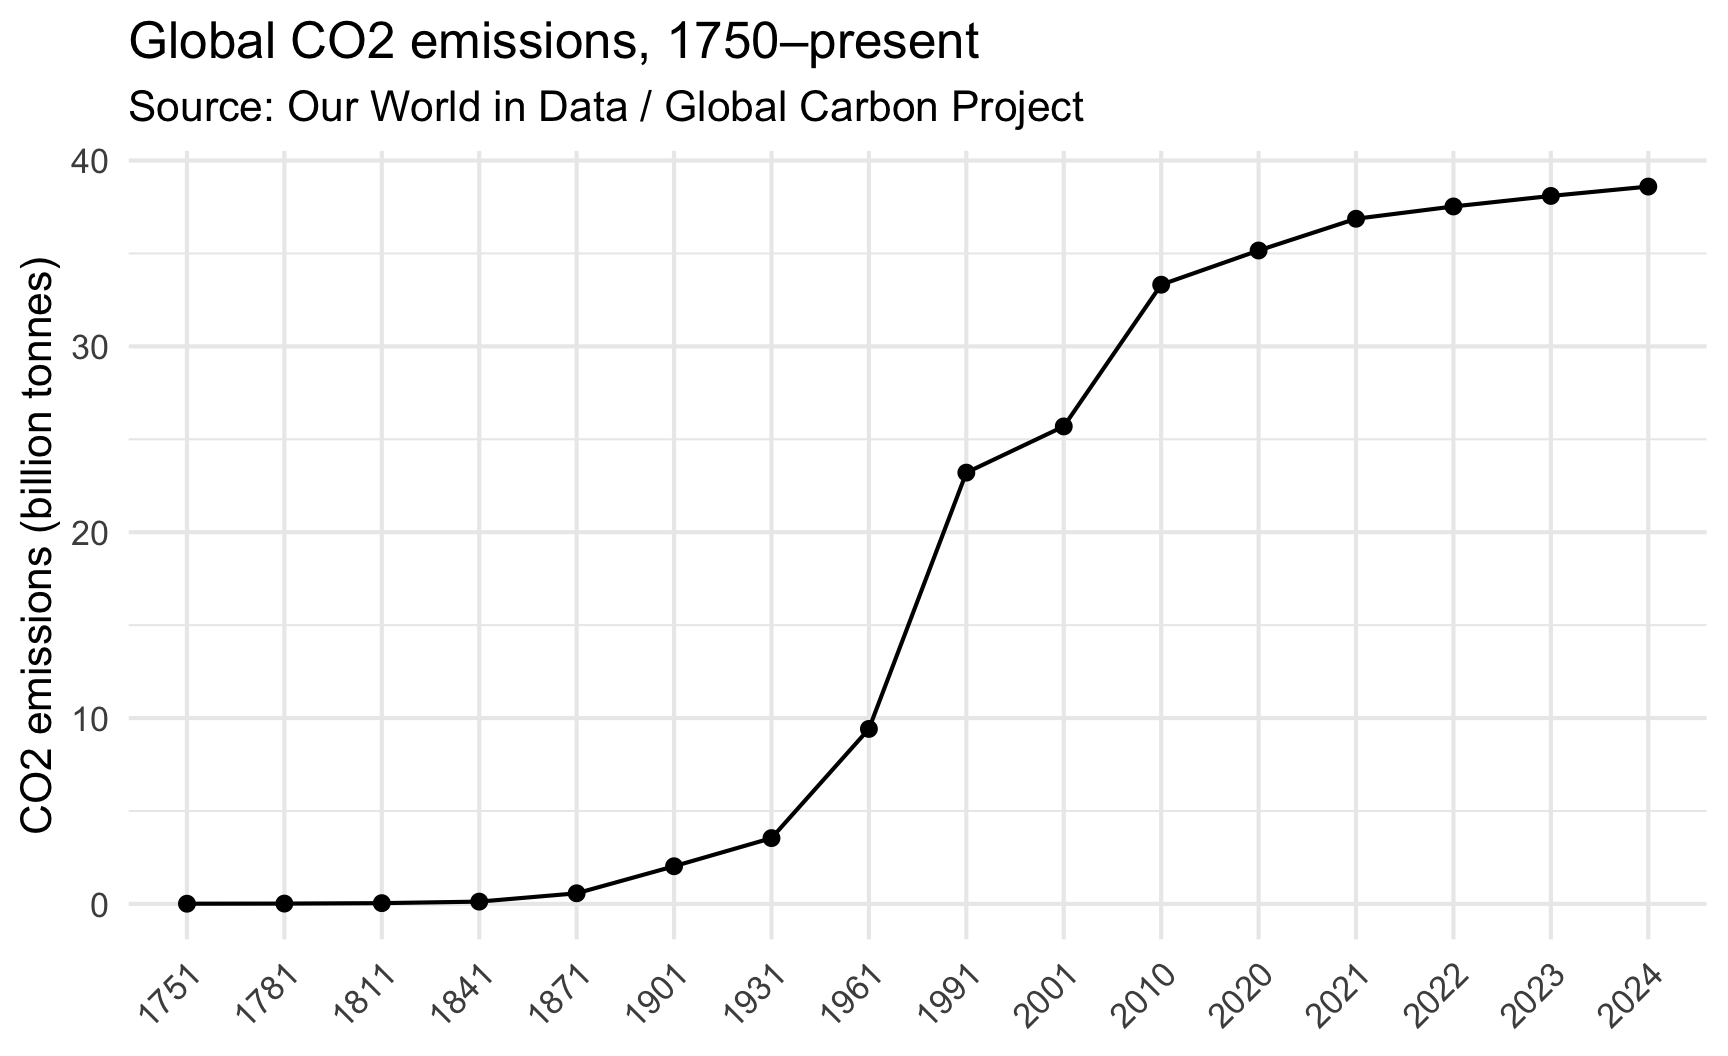
library(tidyverse)# Source: https://ourworldindata.org/grapher/annual-co2-emissions-per-country?country=~OWID_WRLco2_global <-read_csv("data/co2/annual-co2-emissions-per-country.csv") |>rename(co2_emissions =`Annual CO₂ emissions`) |>filter(Entity =="World")selected_years <-c(1751, 1781, 1811, 1841, 1871, 1901, 1931, 1961, 1991, 2001, 2010, 2020, 2021, 2022, 2023, 2024)co2_wrong <- co2_global |>filter(Year %in% selected_years) |>mutate(Year =factor(Year, levels = selected_years))ggplot(data = co2_wrong,mapping =aes(x = Year, y = co2_emissions /10^9, group =1)) +geom_line() +geom_point() +theme_minimal(base_size =16) +labs(x =NULL, y ="CO2 emissions (billion tonnes)",title ="Global CO2 emissions, 1750–present",subtitle ="Source: Our World in Data / Global Carbon Project" ) +theme(axis.text.x =element_text(angle =45, hjust =1))
Look at the last few points on the right: 2020, 2021, 2022, 2023, 2024.
The line looks almost flat there, as if global emissions had reached a plateau.
Question
Is this a fair reading of the data?
The Same Data, Honest Spacing
Code
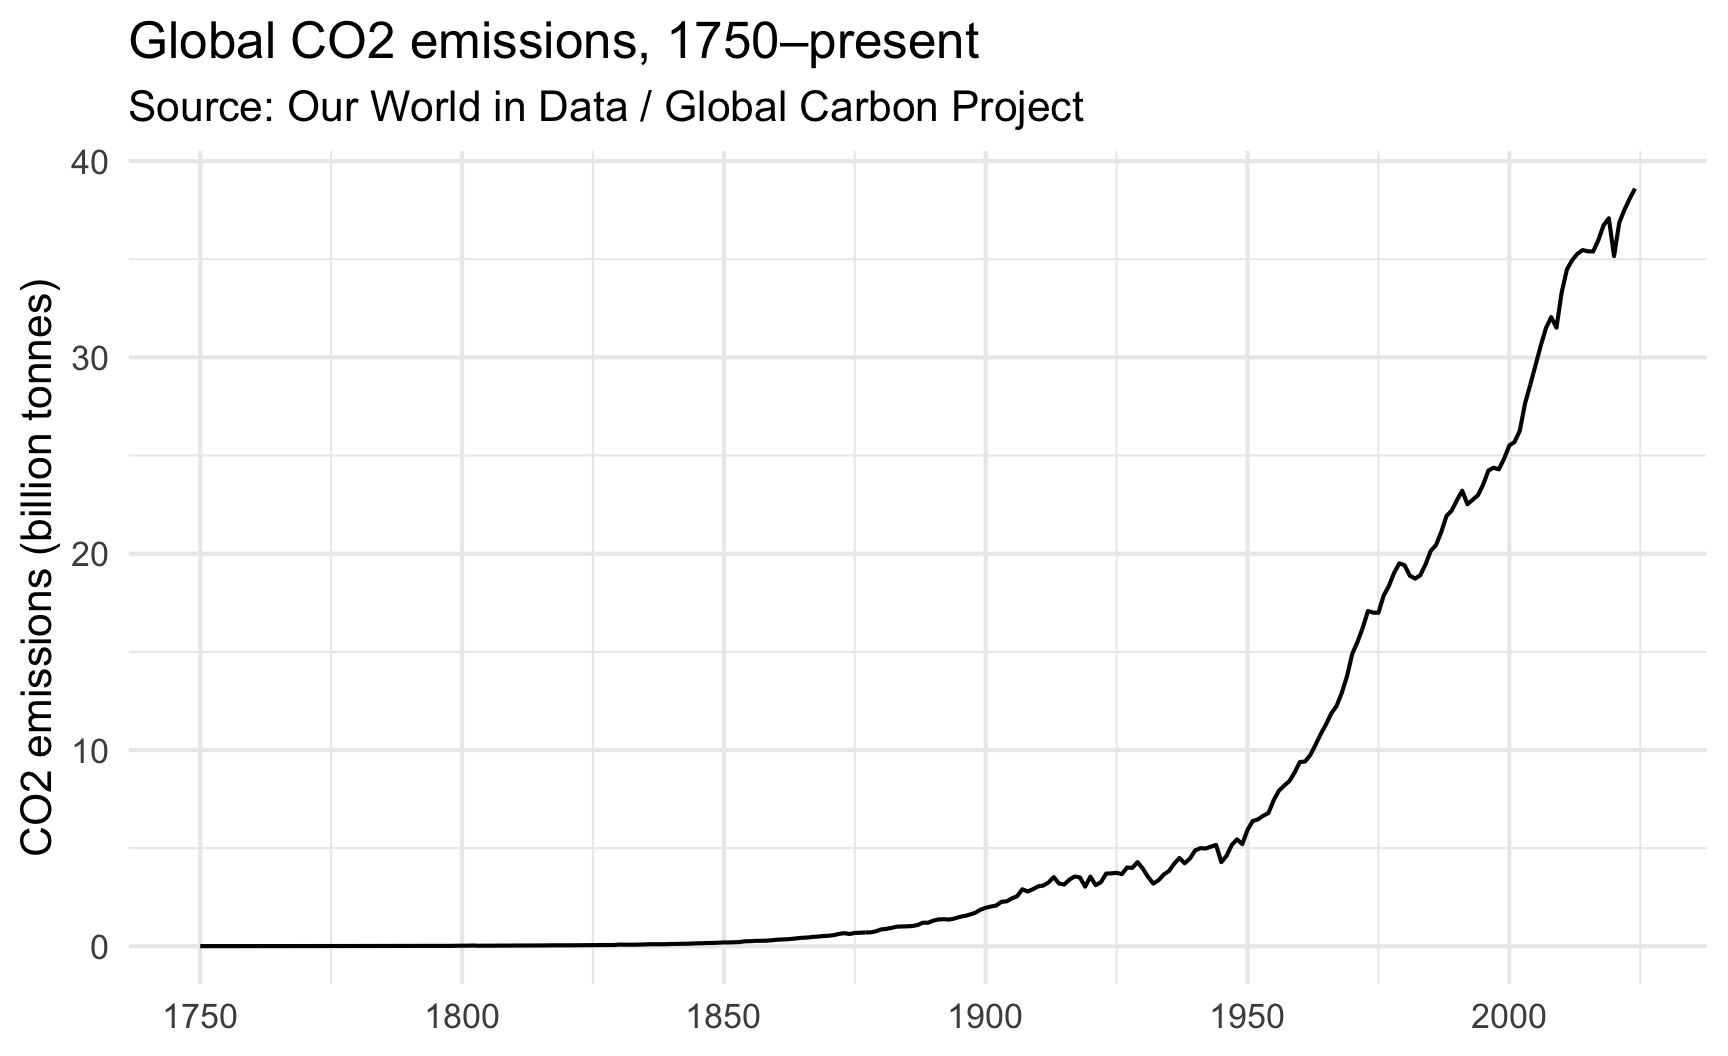
ggplot(data = co2_global,mapping =aes(x = Year, y = co2_emissions /10^9)) +geom_line() +theme_minimal(base_size =16) +labs(x =NULL, y ="CO2 emissions (billion tonnes)",title ="Global CO2 emissions, 1750–present",subtitle ="Source: Our World in Data / Global Carbon Project" )
Once every year is shown, with the x-axis correctly reflecting real time intervals, the “plateau” disappears.
What happened in the first plot:
1751 → 1781: 30 years, one segment
2020 → 2024: 4 years, one segment, but visually identical width.
Warning
It’s still too early to say emissions have peaked. A genuine plateau or decline needs several more years of sustained data to confirm, not an artifact of axis spacing.
From Creating a False Trend… to Hiding a Real One
In the CO2 example, we saw how compressing many years into evenly-spaced categories can manufacture a trend that wasn’t really there.
But equal spacing is not inherently dishonest. Sometimes the opposite problem occurs: too little detail, at the wrong resolution, hides a pattern that is genuinely there.
A different kind of question
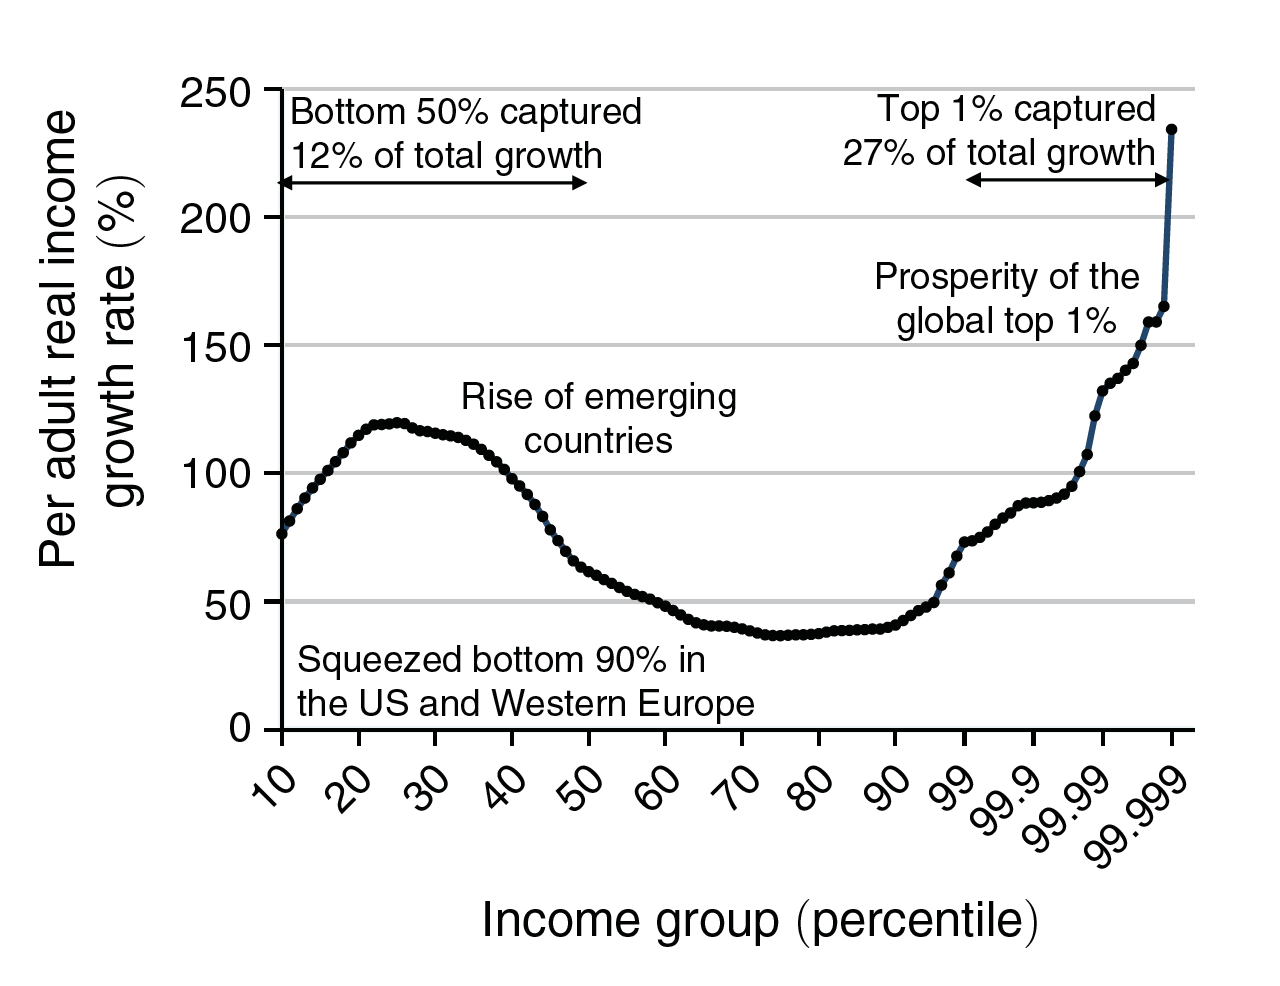
The famous “elephant curve” (Alvaredo et al. (2018)) asks: how has income grown across the entire global income distribution between 1980 and 2016?
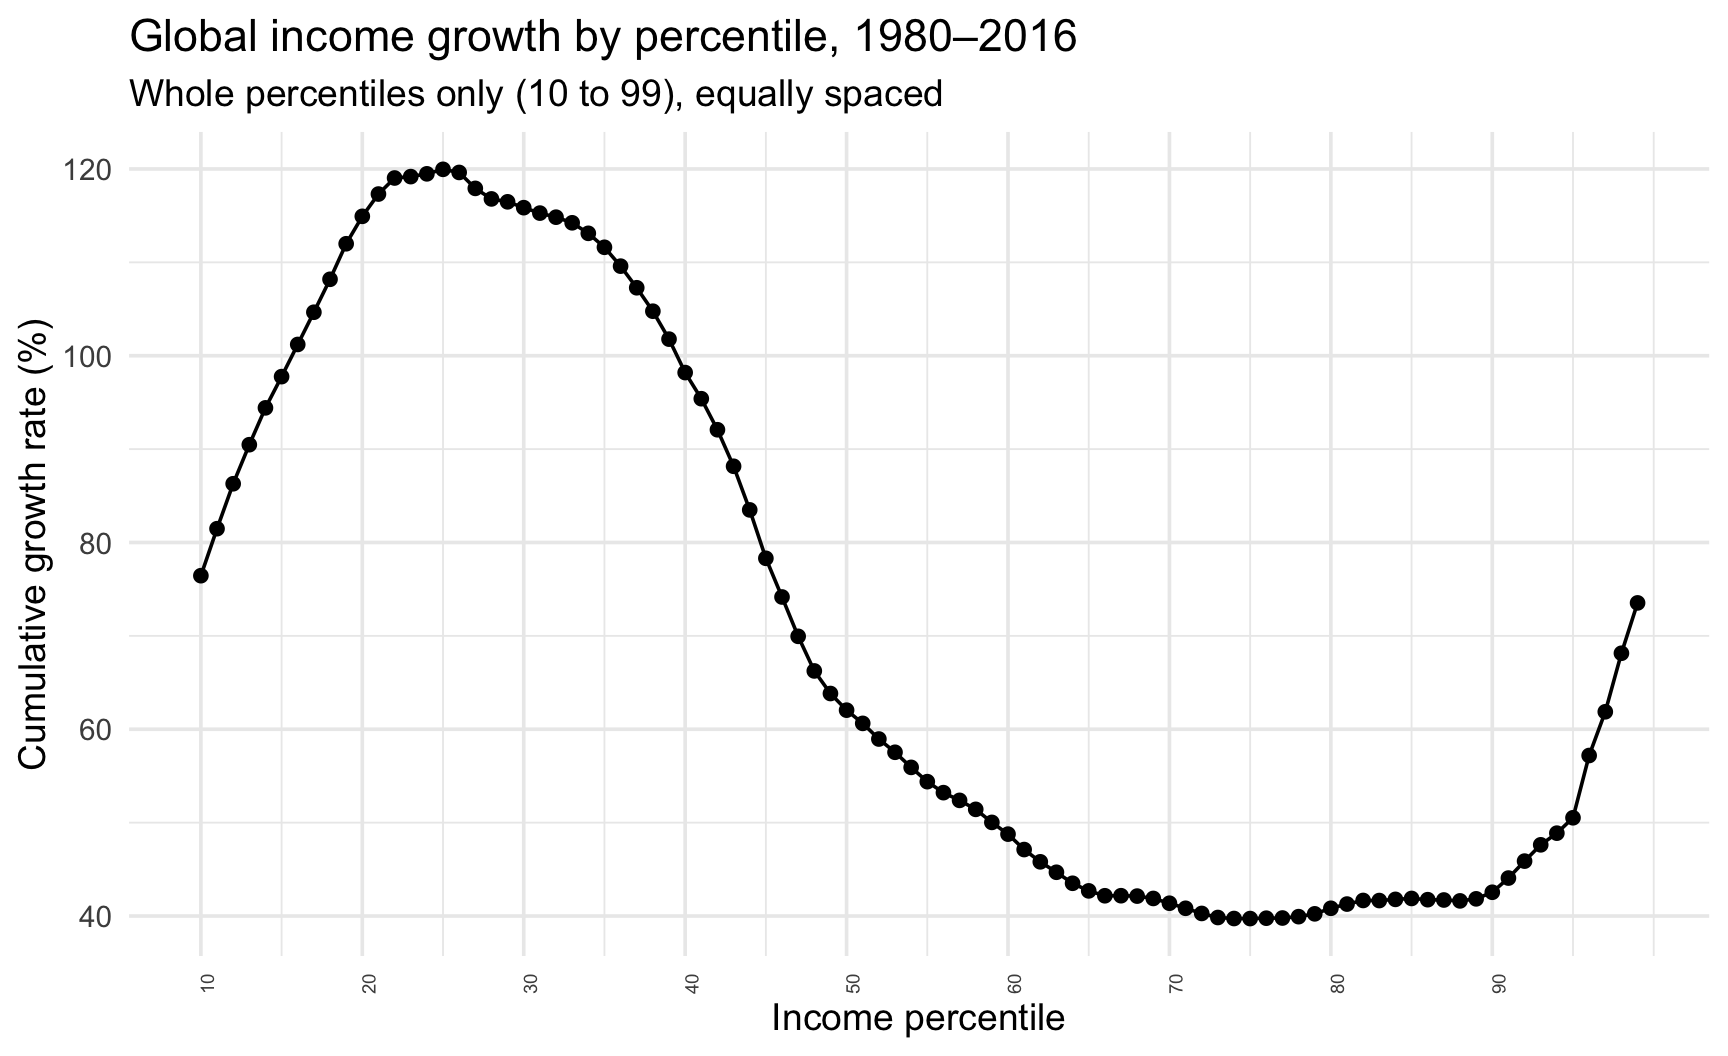
If we only look at whole percentiles, i.e., 10, 11, 12, …, 99, what happens to the very richest people in the world? They are all collapsed into a single point: percentile 99.
Without the Top 1% Decomposition
Code
library(tidyverse)library(readxl)# Source: The Elephant Curve of Global Inequality and Growth# Facundo Alvaredo; Lucas Chancel; Thomas Piketty; Emmanuel Saez; Gabriel Zucman, AEA 2018# https://doi.org/10.3886/e231566v1growth_tb <-read_excel("data/saez_2018/data_saez.xlsx", sheet ="Figure2-data", skip =1)# Keep only whole percentiles: 10, 11, ..., 99 (drop the 99.1, 99.2, ..., 99.999 decomposition)growth_no_decomp <- growth_tb |>filter(`Income group`==floor(`Income group`))ggplot(data = growth_no_decomp |>mutate(`Income group`=factor(`Income group`, levels =`Income group`),`Income group`=as.numeric(as.character(`Income group`)) ),mapping =aes(x =`Income group`, y =`Cumulative growth rate`, group =1)) +geom_line() +geom_point() +scale_x_continuous(breaks =seq(10, 99, by =10)) +theme_minimal(base_size =14) +labs(x ="Income percentile", y ="Cumulative growth rate (%)",title ="Global income growth by percentile, 1980–2016",subtitle ="Whole percentiles only (10 to 99), equally spaced" ) +theme(axis.text.x =element_text(angle =90, hjust =1, size =7))
Here the top 1% of the global income distribution is collapsed into a single point (percentile 99), just like every other percentile.
The curve rises modestly at the very end, but… nothing dramatic.
The paper’s central finding, about extreme divergence within that top 1%, is invisible here!
The Authors’ Version: Decomposing the Top 1%
The “elephant curve”: cumulative growth in real income by global income percentile, 1980–2016. Source: Alvaredo et al. (2018)
The authors decompose the top 1% into finer and finer slices: 99.1, 99.2, …, all the way to 99.999.
This decomposition reveals that growth accelerates sharply again right at the very top of the distribution (this is the famous upward spike of the “elephant’s trunk”):
compared to the poorest 50 percent, the richest 1 percent of individuals captured more than twice as much of the world’s income growth between 1980 and 2016
The Difference: Intent and Transparency
In the CO2 example
Squeezes recent, fast-changing years into the same width as old, slow-changing decades
Manufactures the appearance of a plateau that is not really there
No indication to the reader that anything unusual was done
The objective would be to reveal a false trend.
The elephant curve
Percentile axis is explicitly labeled and explained
Uneven spacing draws attention to a real and important feature (the top 1% diverging)
The choice is transparent and defensible from the data’s structure
The objective is to reveal a trend.
The lesson is not “never use uneven intervals”, or, “always decompose finely”
Both spacing choices and resolution choices shape what a chart reveals or conceals. They are legitimate when:
they reflect something meaningful about the data itself (e.g., isolating a small but important subgroup), and
they are clearly signposted to the reader (labeled axis, explanatory caption).
The problem in our CO2 example was not the technique; it was using it silently, to make a busy period look calm. The elephant curve uses similar techniques transparently, to make a genuinely dramatic pattern visible.
Dual Y-Scales
A Conspiracy Theory: MMR Vaccines and Autism
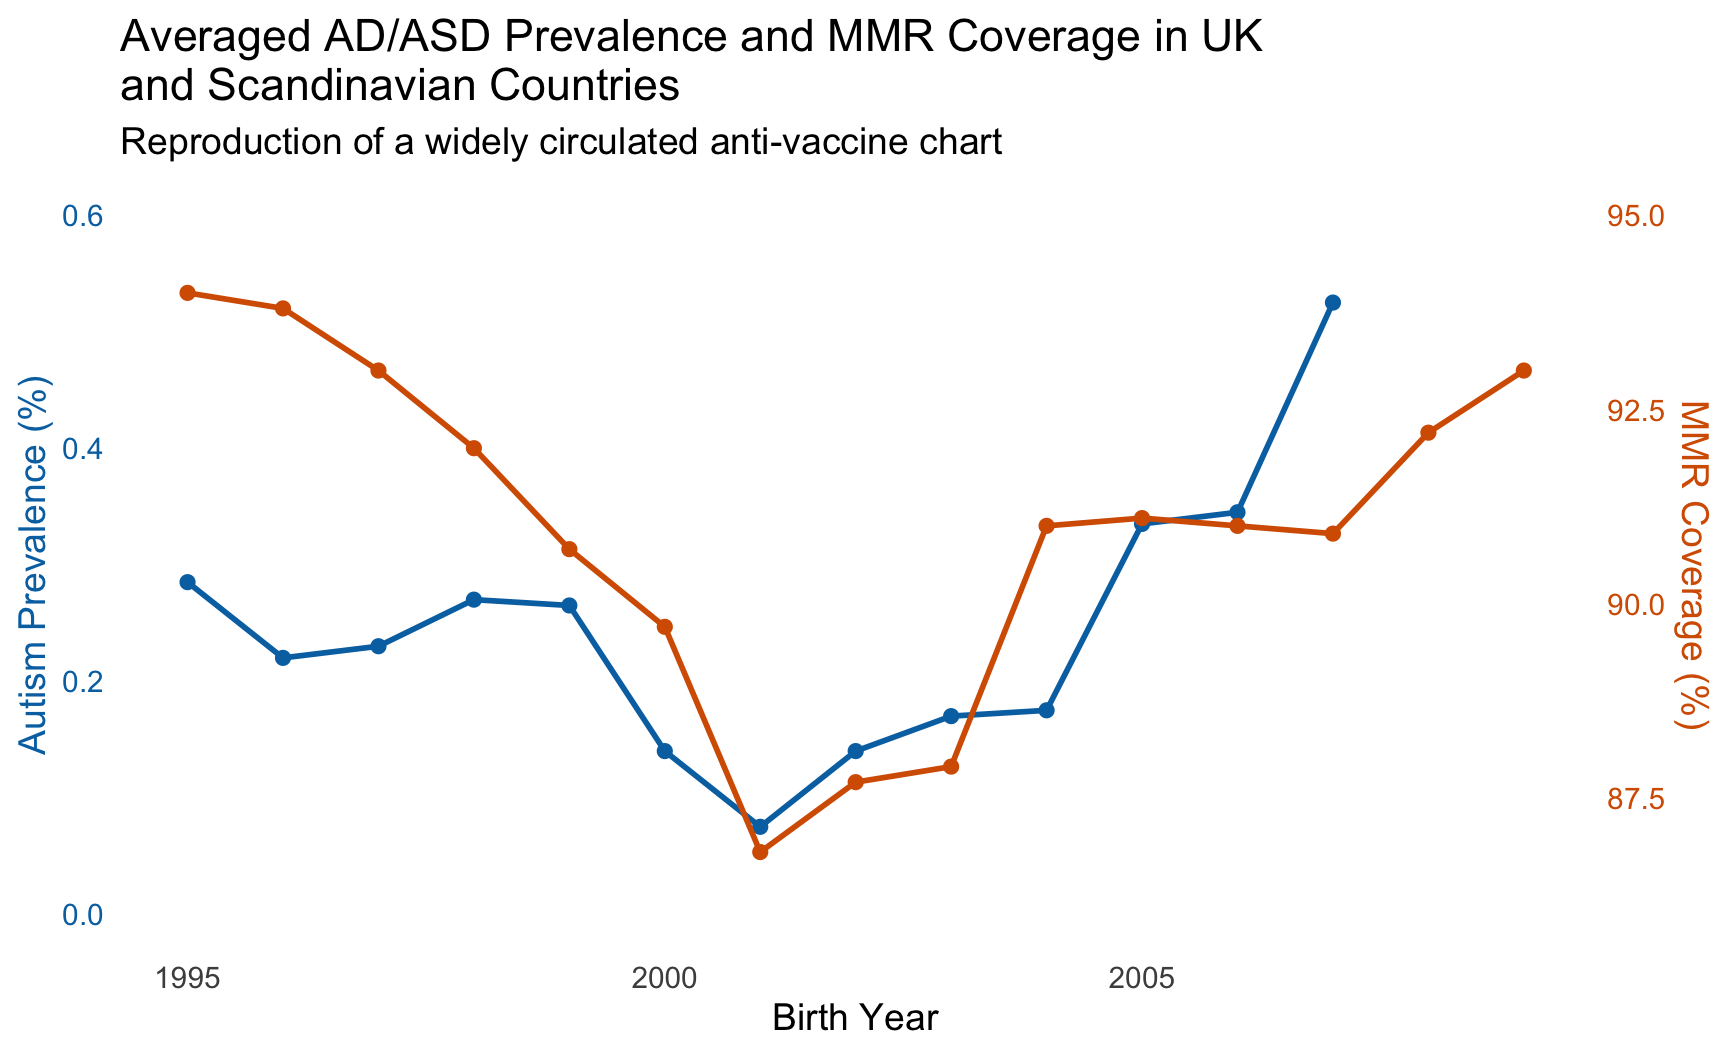
A well-known chart circulated online claims to show that rising autism rates track vaccination rates used to suggest a causal link between the MMR vaccine and autism.
This example is discussed by Bergstrom and West (2020) (Chapter 7).
At first glance, the two curves seem to move together.
Code
library(tidyverse)# Approximate values read off the original chart# Source: a shady Q4 journaltb_asd <-tribble(~birth_year, ~autism_prevalence,1995, 0.285,1996, 0.220,1997, 0.230,1998, 0.270,1999, 0.265,2000, 0.140,2001, 0.075,2002, 0.140,2003, 0.170,2004, 0.175,2005, 0.335,2006, 0.345,2007, 0.525)tb_mmr <-tribble(~birth_year, ~mmr_coverage,1995, 94.0,1996, 93.8,1997, 93.0,1998, 92.0,1999, 90.7,2000, 89.7,2001, 86.8,2002, 87.7,2003, 87.9,2004, 91.0,2005, 91.1,2006, 91.0,2007, 90.9,2008, 92.2,2009, 93.0)combined_data <-full_join(tb_asd, tb_mmr, by ="birth_year")# Each axis's range is chosen independently, and stretched/compressed# so the two curves visually "match up" and appear to move together.scale_factor <-0.6/ (95.0-86.0) # autism range / MMR rangeoffset <-86.0p_asd_misleading <-ggplot(data = combined_data, mapping =aes(x = birth_year)) +geom_line(aes(y = autism_prevalence), colour ="#0072B2", linewidth =1) +geom_point(aes(y = autism_prevalence), colour ="#0072B2", size =2) +geom_line(aes(y = (mmr_coverage - offset) * scale_factor), colour ="#D55E00", linewidth =1) +geom_point(aes(y = (mmr_coverage - offset) * scale_factor), colour ="#D55E00", size =2) +scale_y_continuous(name ="Autism Prevalence (%)",limits =c(0, 0.6),sec.axis =sec_axis(transform =~ . / scale_factor + offset,name ="MMR Coverage (%)" ) ) +labs(x ="Birth Year",title ="Averaged AD/ASD Prevalence and MMR Coverage in UK\nand Scandinavian Countries",subtitle ="Reproduction of a widely circulated anti-vaccine chart" ) +theme_minimal(base_size =14) +theme(panel.grid =element_blank(),axis.title.y =element_text(colour ="#0072B2"),axis.title.y.right =element_text(colour ="#D55E00"),axis.text.y =element_text(colour ="#0072B2"),axis.text.y.right =element_text(colour ="#D55E00") )p_asd_misleading
Autism prevalence is plotted from 0 to 0.6%. MMR coverage is plotted from 86% to 95%. Two completely different scales, overlaid on the same plot area.
Rescaling: Both Axes Must Include Zero
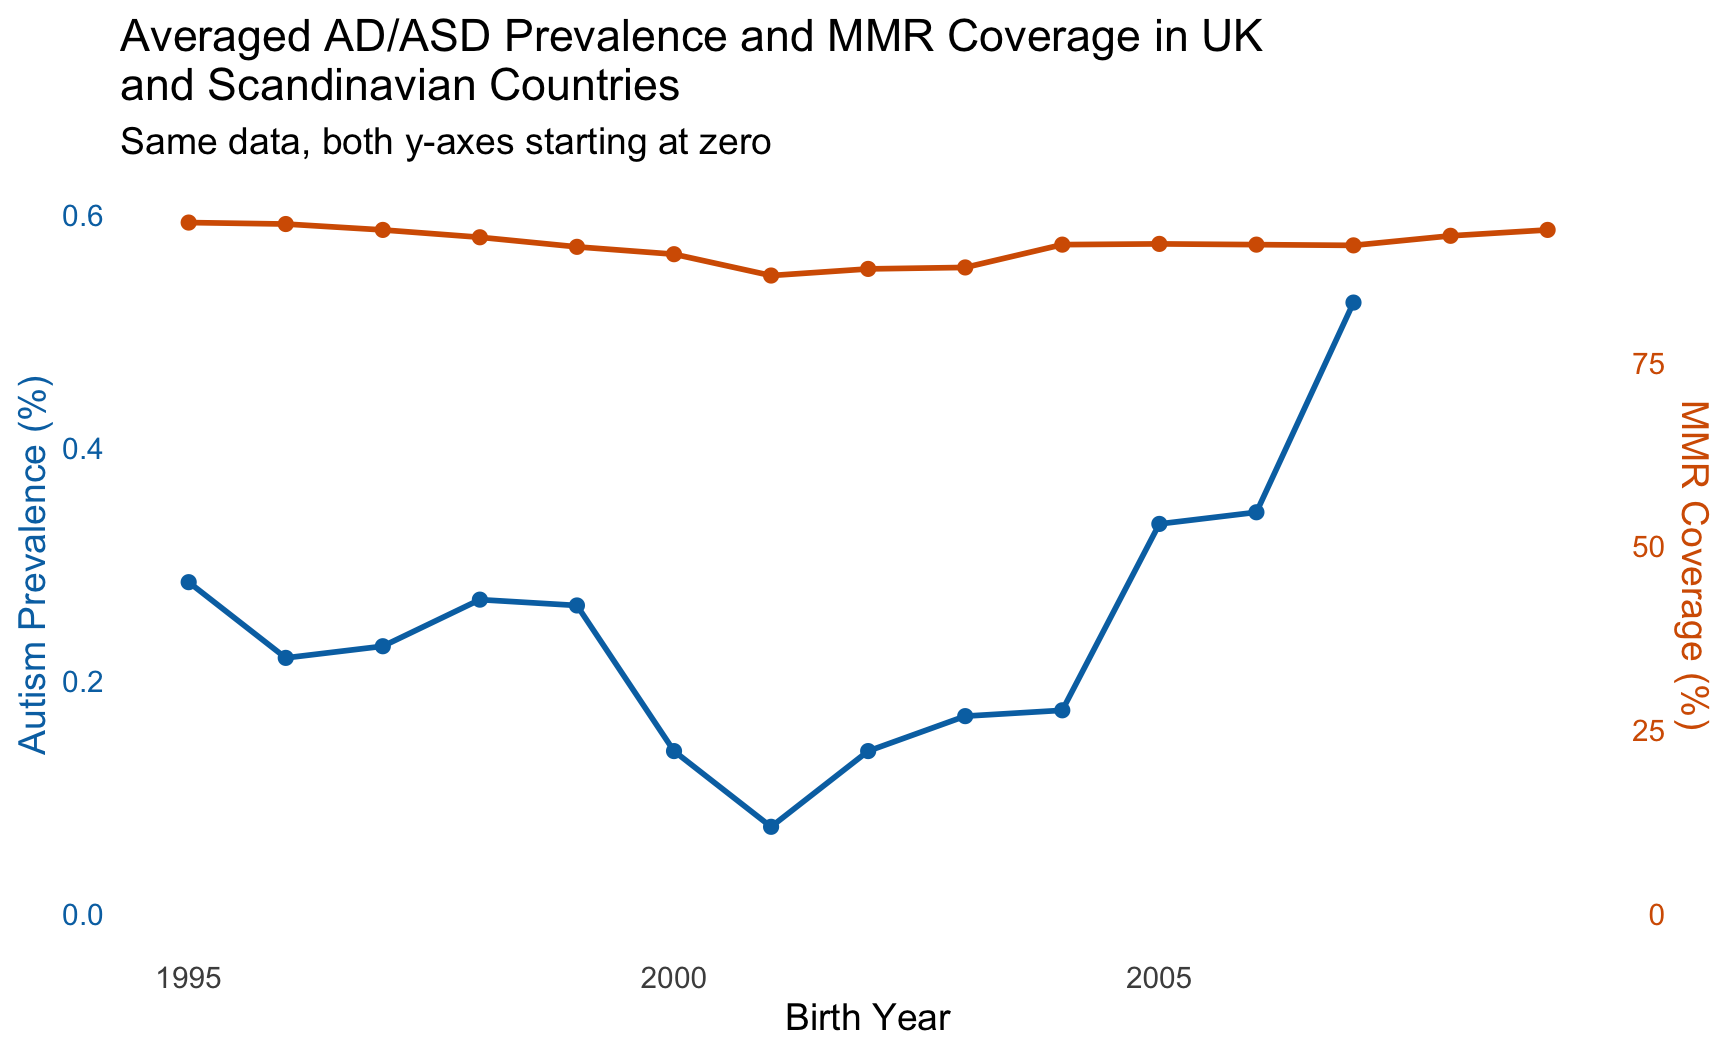
We do not have to show both trends on the same scale, but we do need to ensure that both axes include zero.
What we actually see over this period: a large proportional change in autism (roughly a tenfold increase from 2000 to 2007), but a very small proportional change in MMR coverage.
Code
# Same chart, but both y-axes now start at 0offset <-0scale_factor <-0.6/95.0# autism range / MMR range, both starting at 0p_asd_starting_0 <-ggplot(combined_data, aes(x = birth_year)) +geom_line(aes(y = autism_prevalence), colour ="#0072B2", linewidth =1) +geom_point(aes(y = autism_prevalence), colour ="#0072B2", size =2) +geom_line(aes(y = (mmr_coverage - offset) * scale_factor), colour ="#D55E00", linewidth =1) +geom_point(aes(y = (mmr_coverage - offset) * scale_factor), colour ="#D55E00", size =2) +scale_y_continuous(name ="Autism Prevalence (%)",limits =c(0, 0.6),sec.axis =sec_axis(transform =~ . / scale_factor + offset,name ="MMR Coverage (%)" ) ) +labs(x ="Birth Year",title ="Averaged AD/ASD Prevalence and MMR Coverage in UK\nand Scandinavian Countries",subtitle ="Same data, both y-axes starting at zero" ) +theme_minimal(base_size =14) +theme(panel.grid =element_blank(),axis.title.y =element_text(colour ="#0072B2"),axis.title.y.right =element_text(colour ="#D55E00"),axis.text.y =element_text(colour ="#0072B2"),axis.text.y.right =element_text(colour ="#D55E00") )p_asd_starting_0
The MMR curve now looks nearly flat, because it only ever varied within a narrow 86–94% range. The dramatic “coupling” of the two curves in the original chart was a pure artifact of stretching that narrow range to fill the full plot area.
Why Dual Axes Are Fundamentally Flawed
ggplot2 refused to support independent dual y-axes for a long time (Wickham 2010)
“Plots with separate y scales (not y-scales that are transformations of each other) are fundamentally flawed […] They are not invertible: given a point on the plot space, you cannot uniquely map it back to a point in the data space […] They are easily manipulated to mislead: there is no unique way to specify the relative scales of the axes, leaving them open to manipulation […] They are arbitrary: why have only 2 scales, not 3, 4, or ten?”
There is no unique, “correct” way to align two independently-scaled axes. Any relationship you want to suggest between two series can be manufactured simply by choosing the right offset and stretch factor for the second axis.
For a more nuanced view, see Wong et al. (2021): they survey financial reports and find dual-axis charts appear in about 19% of published time-series charts in that domain. They argue that, used carefully by professionals for fine-grained correlation analysis, they can reveal relationships that single-axis, normalized, or scatterplot alternatives miss.
Binning
Where the Tax Money Is? A WSJ Editorial
Code
library(tidyverse)# Source: IRS# Individual Income Tax, All Returns: Tax Liability, Tax Credits, # and Tax Payments — Size of adjusted gross income# URL: https://www.irs.gov/pub/irs-soi/08in02ar.xlsirs <- readxl::read_excel("data/irs/08in02ar.xls", sheet ="TBL33", skip =10, col_names =FALSE, n_max =18) |>rename(group =`...1`, taxable_inc =`...4`) |>mutate(group =str_replace(group, " under ", "-"),group =str_replace(group, ",000,000", "million"),group =fct_inorder(group) )ggplot(data = irs,mapping =aes(x = group, y = taxable_inc /10^9)) +geom_bar(stat ="identity") +labs(x ="Adjusted gross income level ($)",y ="Total taxable income ($ billions)",title ="Total Taxable Income in 2008",subtitle ="Source: IRS, SOI Tax Stats — Individual Income Tax Returns" ) +theme_minimal(base_size =12) +theme(axis.text.x =element_text(angle =45, hjust =1),plot.title.position ="plot" )
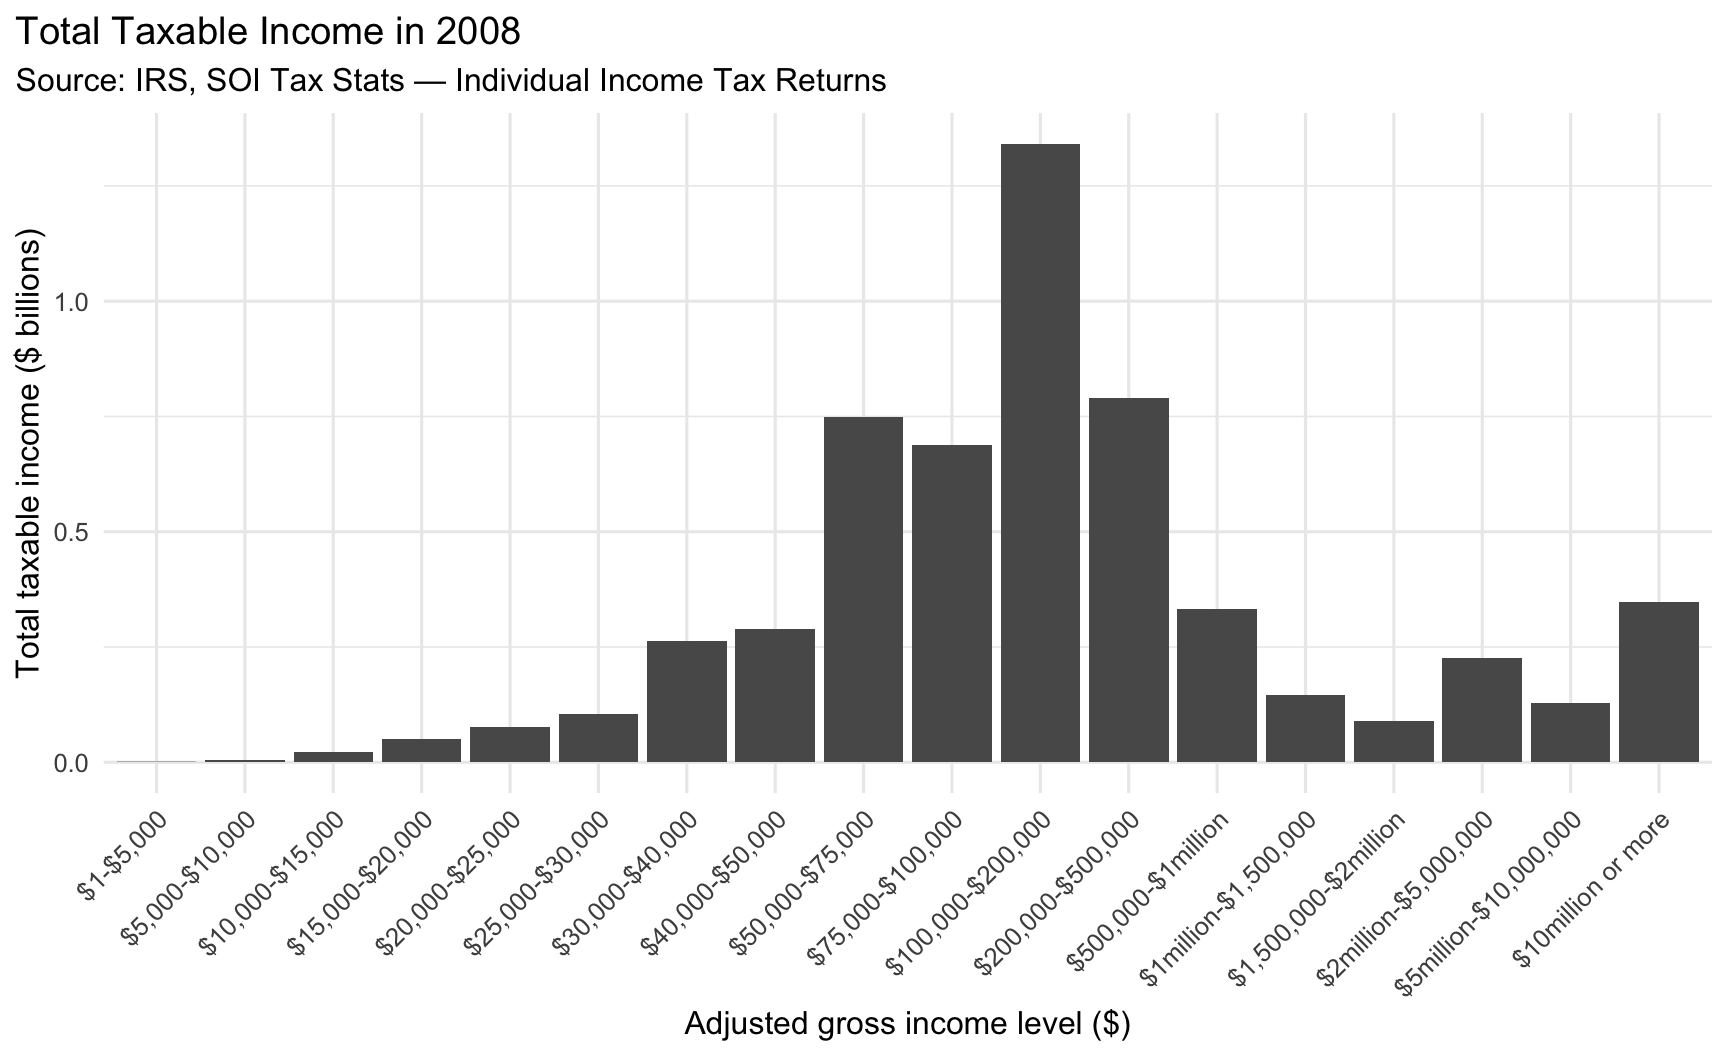
A dominant theme of President Obama’s budget speech was that our fiscal problems would vanish if only the wealthiest Americans were asked “to pay a little more.”
The editorial uses this chart to argue that the middle class, not “the rich,” holds most of the taxable income. So, any serious deficit reduction must eventually reach the middle class.
The tallest bar sits at $100,000–$200,000.
But… Look at the Bin Widths
IRS income bracket
Bracket width
$1-$5,000
$4k
$5,000-$10,000
$5k
$10,000-$15,000
$5k
$15,000-$20,000
$5k
$20,000-$25,000
$5k
$25,000-$30,000
$5k
$30,000-$40,000
$10k
$40,000-$50,000
$10k
$50,000-$75,000
$25k
$75,000-$100,000
$25k
$100,000-$200,000
$100k
$200,000-$500,000
$100k
$500,000-$1million
$300k
$1million-$1,500,000
$500k
$1,500,000-$2million
$500k
$2million-$5,000,000
$3M
$5million-$10,000,000
$5M
$10million or more
∞
The IRS’s own reporting brackets are not equally wide.
Narrow bands (a few thousand dollars) sit at the bottom of the distribution; the bracket “$100,000 under $200,000” is $100,000 wide, it is one of the widest bins on the whole chart.
Warning
A bar’s height reflects both how many taxpayers fall in that bin and how wide the bin is. A wide bin isn’t automatically tall, but if it happens to also contain a lot of taxpayers, its height gets a double boost: more people, and a wider net catching them. Comparing raw bar heights across unequally-sized bins conflates these two effects.
It is Easy to Draw the Opposite Conclusion
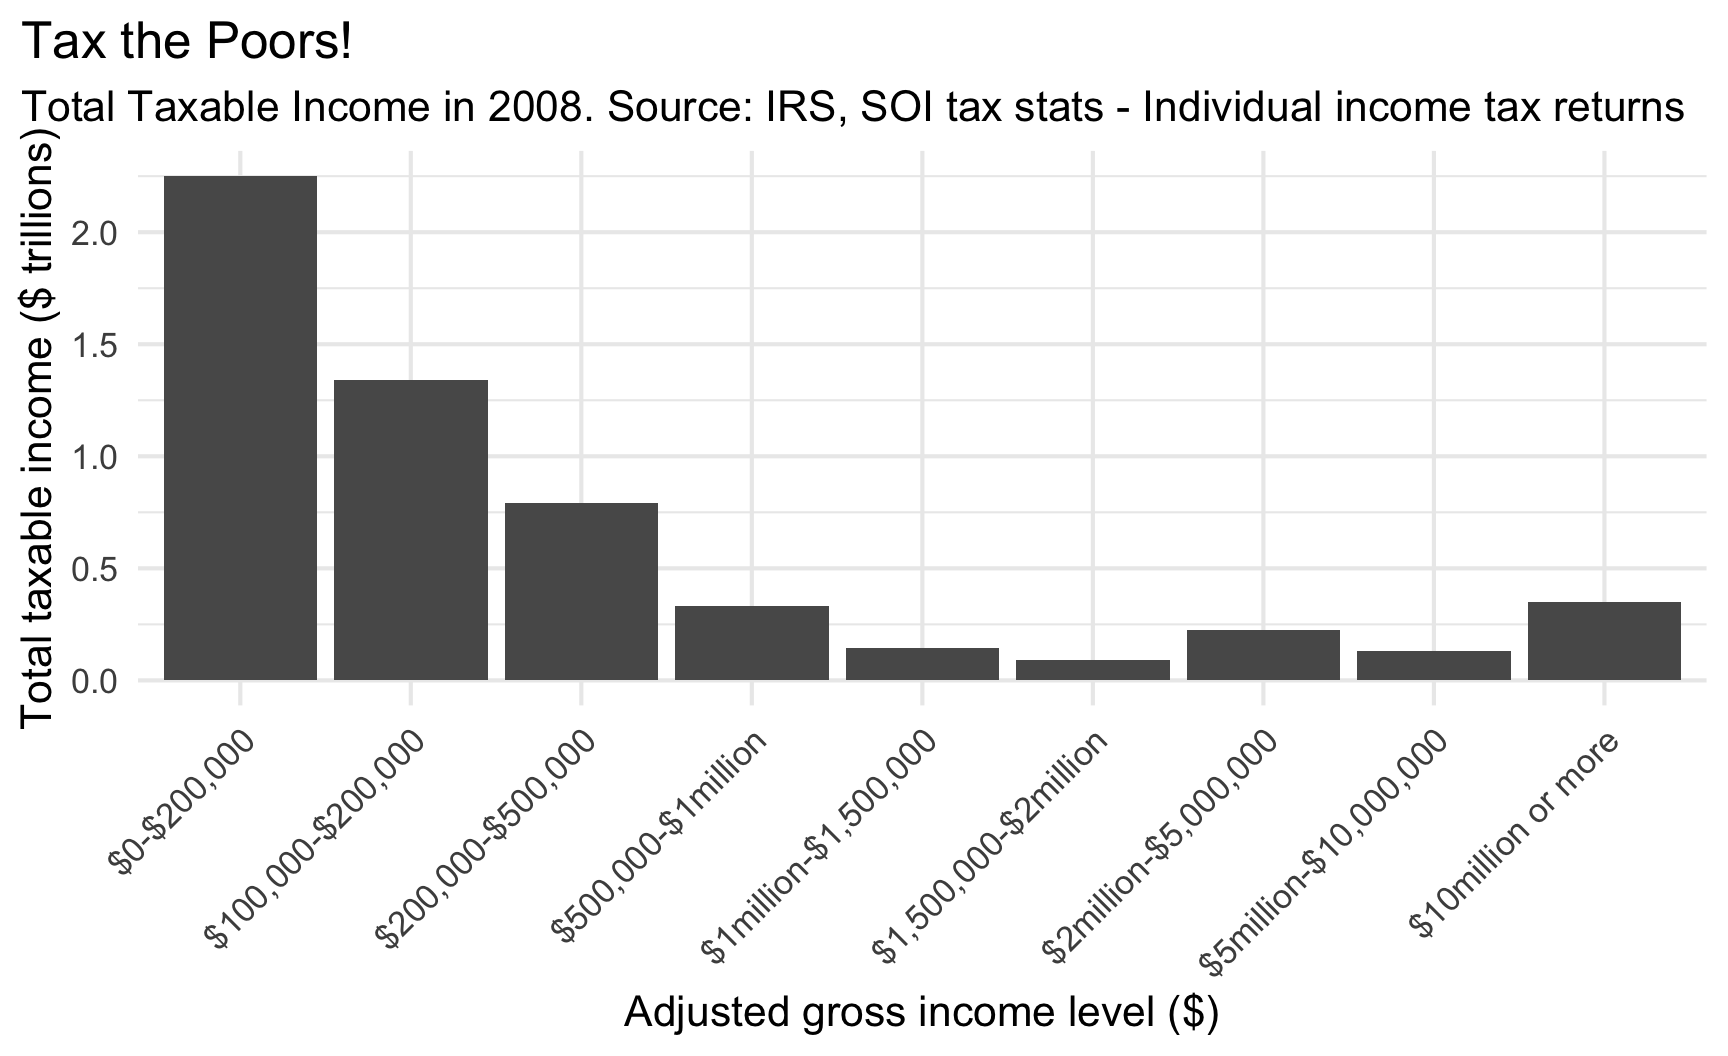
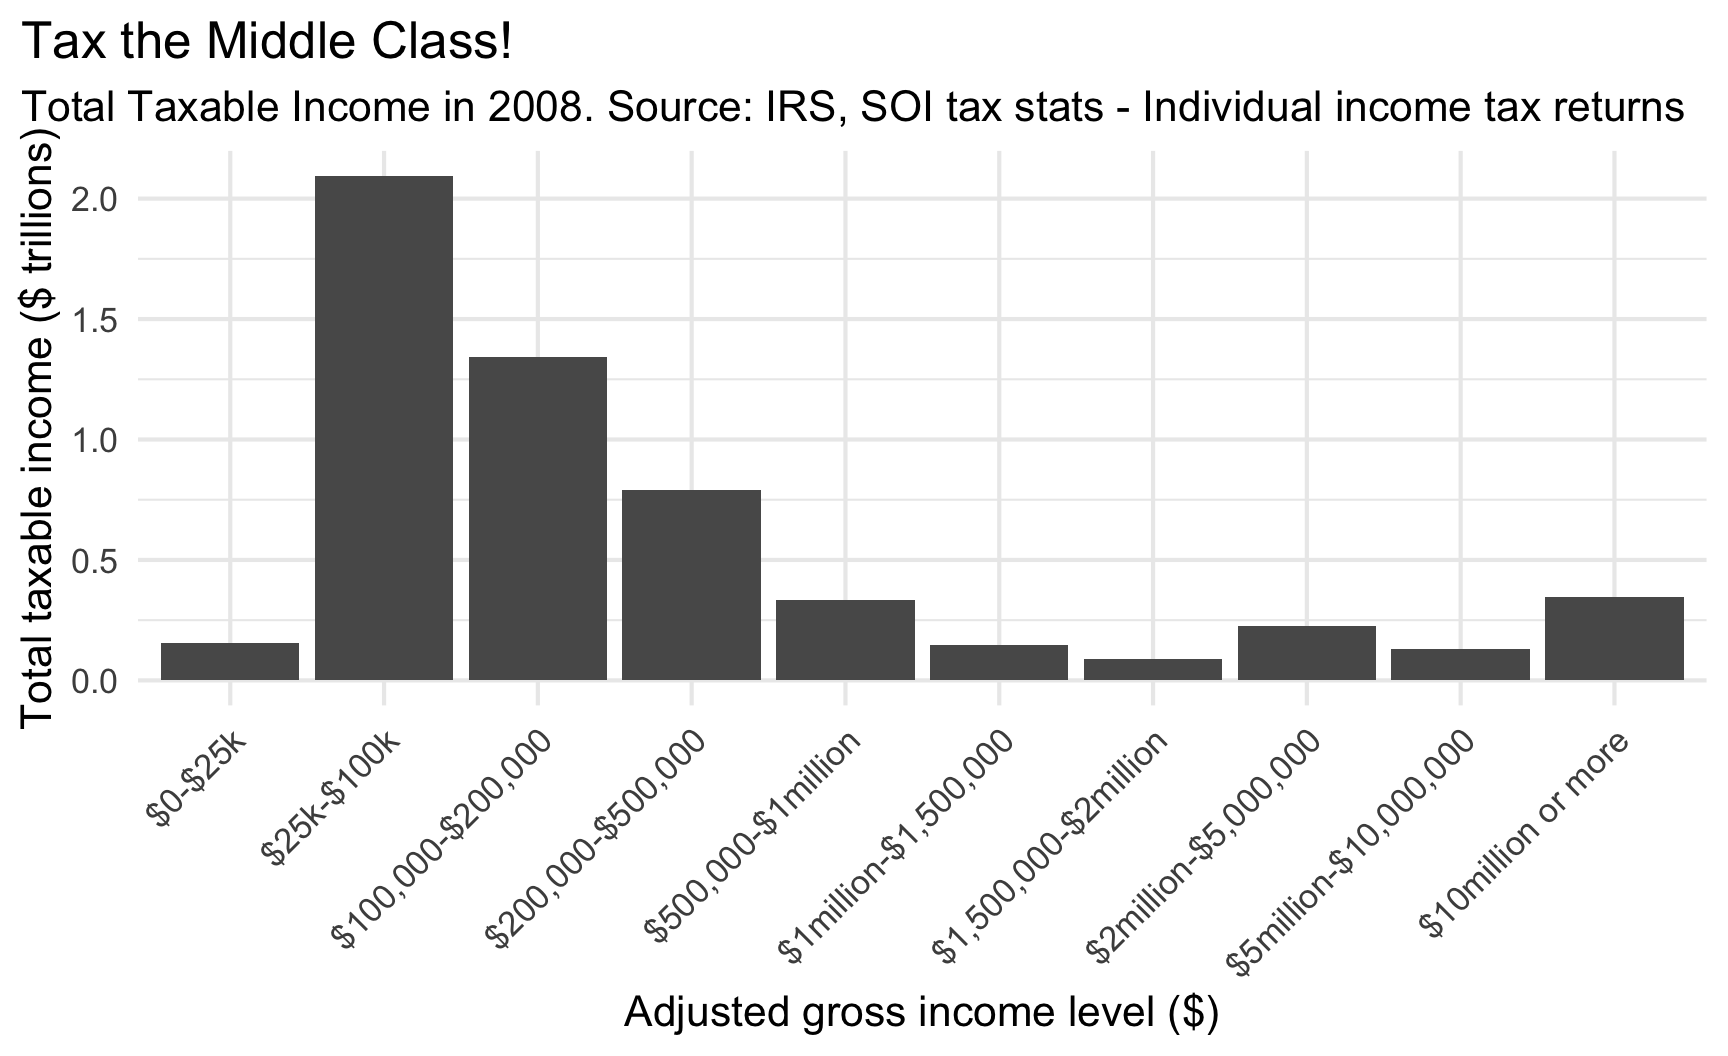
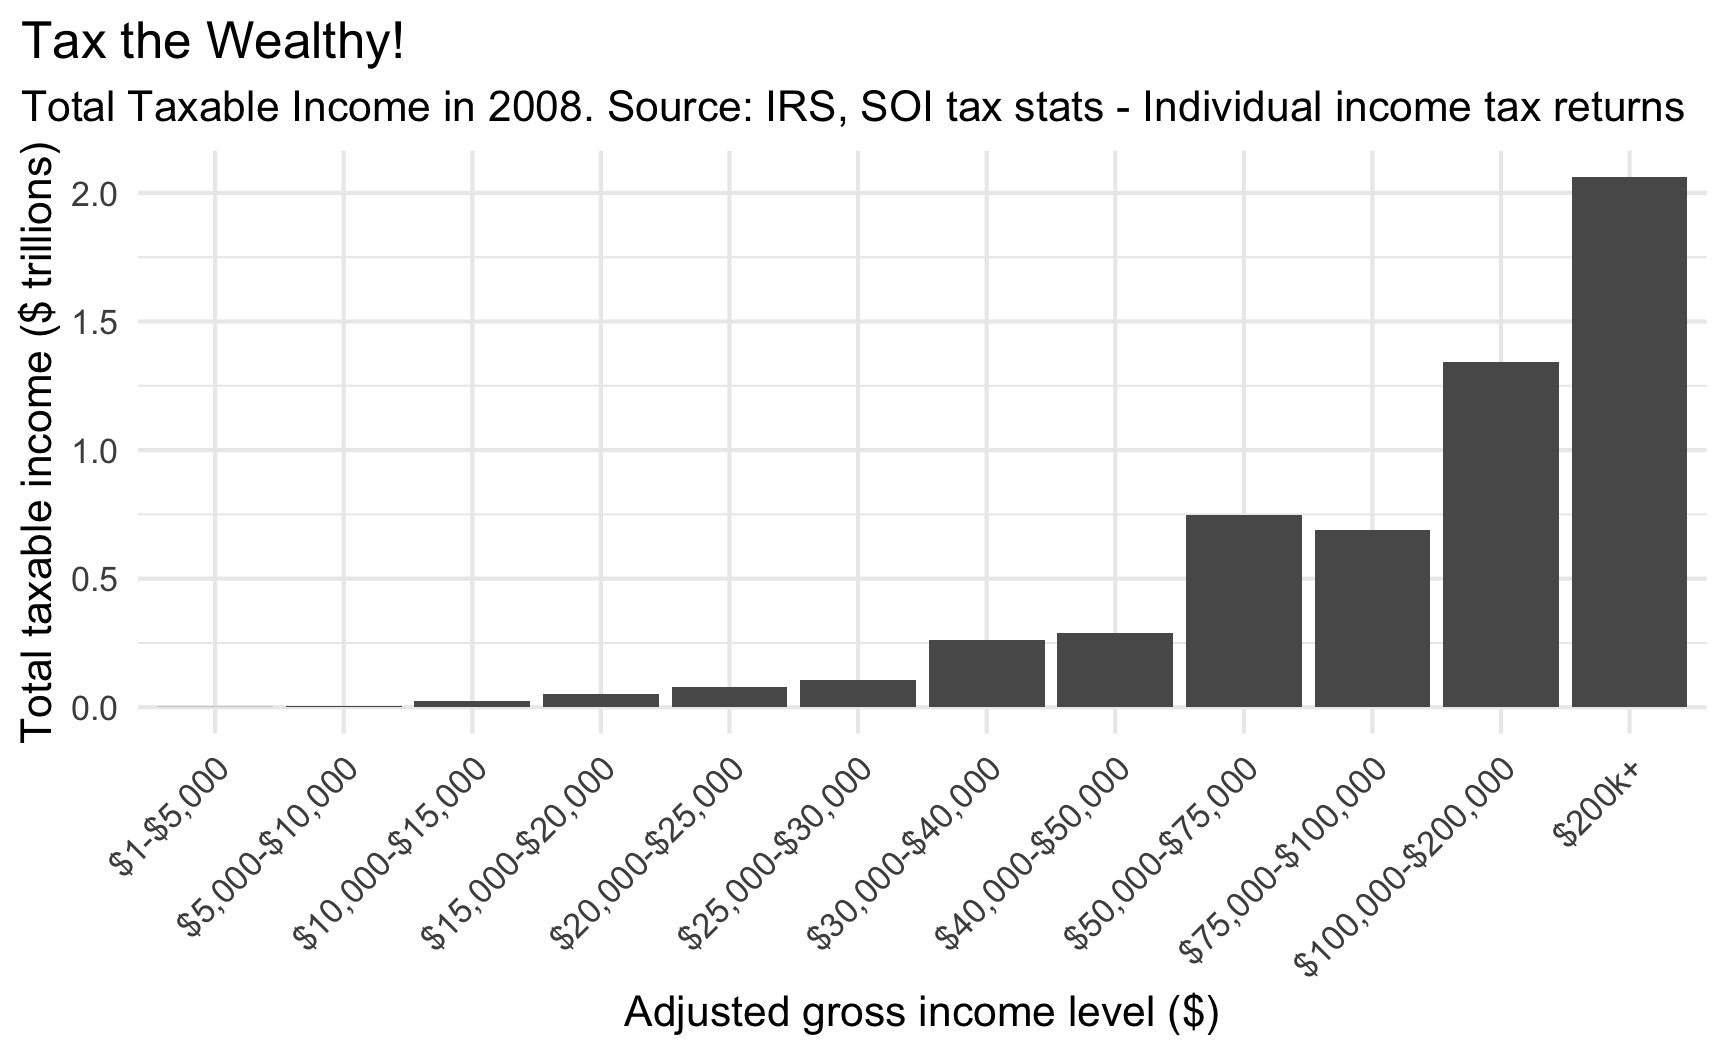
As Brendan Nyhan pointed out in a 2011 critique of this very chart (Nyhan 2011), political scientist Ken Schultz showed that re-binning the same underlying IRS data can be used to tell three completely different stories
Code
plot_irs_data <-function(data, title) {ggplot(data = data,# Amounts in thousands of dollars initiallymapping =aes(x = group, y = taxable_inc /10^9) ) +geom_bar(stat ="identity") +labs(x ="Adjusted gross income level ($)",y ="Total taxable income ($ trillions)",title = title,subtitle ="Total Taxable Income in 2008. Source: IRS, SOI tax stats - Individual income tax returns" ) +theme_minimal(base_size =16) +theme(axis.text.x =element_text(angle =45, hjust =1),plot.title.position ="plot" )}p_tax_poors <-plot_irs_data(data = irs |>mutate(group =fct_recode(group,"$0-$200,000"="$1-$5,000", "$0-$200,000"="$5,000-$10,000", "$0-$200,000"="$10,000-$15,000", "$0-$200,000"="$15,000-$20,000","$0-$200,000"="$20,000-$25,000", "$0-$200,000"="$25,000-$30,000", "$0-$200,000"="$30,000-$40,000", "$0-$200,000"="$40,000-$50,000","$0-$200,000"="$50,000-$75,000", "$0-$200,000"="$75,000-$100,000" ) ),title ="Tax the Poors!")p_tax_middle <-plot_irs_data(data = irs |>mutate(group =fct_recode(group,"$0-$25k"="$1-$5,000","$0-$25k"="$5,000-$10,000","$0-$25k"="$10,000-$15,000","$0-$25k"="$15,000-$20,000","$0-$25k"="$20,000-$25,000","$25k-$100k"="$25,000-$30,000","$25k-$100k"="$30,000-$40,000","$25k-$100k"="$40,000-$50,000","$25k-$100k"="$50,000-$75,000","$25k-$100k"="$75,000-$100,000" ) ),title ="Tax the Middle Class!")p_tax_wealthy <-plot_irs_data(data = irs |>mutate(group =fct_recode(group,"$200k+"="$200,000-$500,000","$200k+"="$500,000-$1million","$200k+"="$1million-$1,500,000","$200k+"="$1,500,000-$2million","$200k+"="$2million-$5,000,000","$200k+"="$5million-$10,000,000","$200k+"="$10million or more" ) ),title ="Tax the Wealthy!")
Coarse bins at the bottom, fine bins at the top.
A binning similar to that of the IRS.
Fine bins at the bottom, one giant bin (“$200k+”) at the top.
Bins Are a Design Choice, Not a Given
What to check whenever you see a bar chart with a categorical/binned x-axis
Are all the bins the same width? If not, ask why, and consider whether a wide bin is inflating its bar just by definition.
Who chose the bin boundaries, and could they have chosen differently? Even “official” categories, like the IRS’s own reporting brackets, are a choice, not a law of nature.
Does the story change if you re-bin? If three defensible re-binnings of the same data produce three opposite headlines, none of the charts alone tells you the full picture. You need the underlying continuous distribution, not any one binning of it.
This is the binning equivalent of the axis-scaling lessons from earlier: a chart can be completely accurate at the level of each individual number, and still mislead through the structural choices made before a single bar is drawn.
Comparing Quantities with Different Denominators
Casualties in Road Accidents
Code
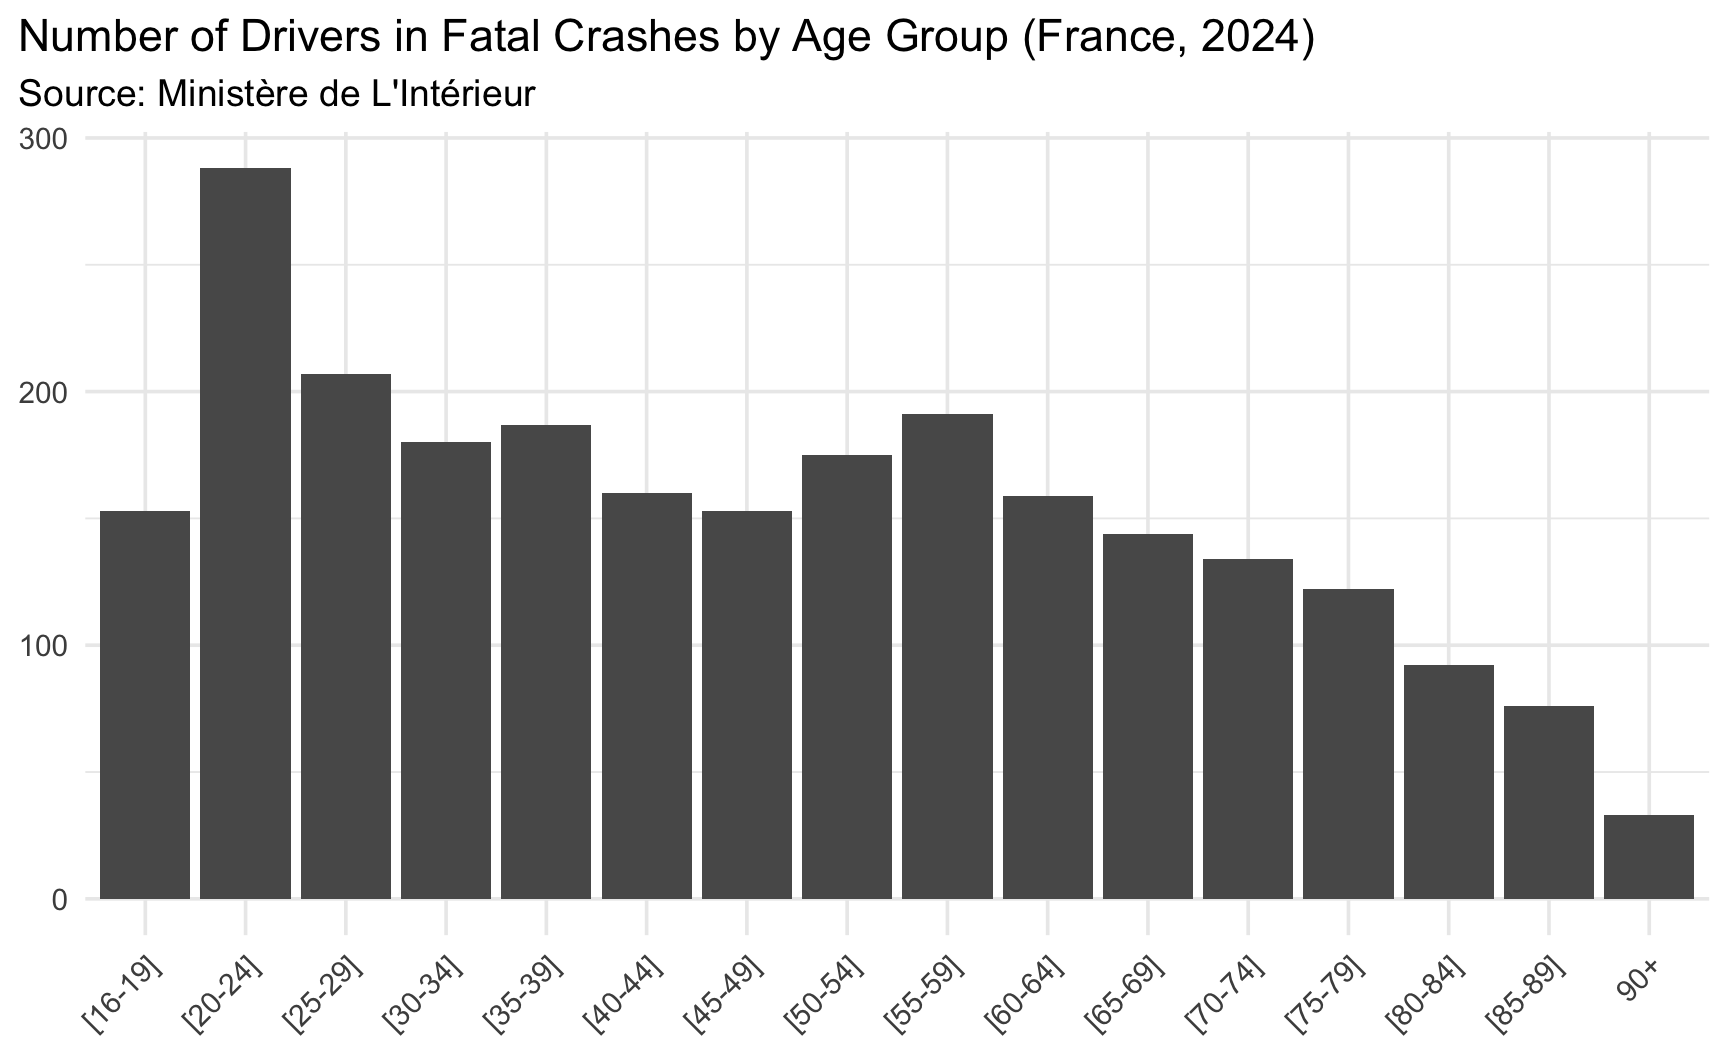
library(tidyverse)# Source: Ministère de L'Intérieur (France)# Bases de données annuelles des accidents corporels de la circulation routière# Table des usagers impliqués dans les accidents corporels en 2024 en France# URL: https://www.data.gouv.fr/api/1/datasets/r/f57b1f58-386d-4048-8f78-2ebe435df868accidents <-read_csv2("data/accidents-usagers/usagers-2024.csv") |>filter(grav ==2, catu ==1) |># Drivers killed in accidentsmutate(age =2024- an_nais,age_categ =case_when( age %in%16:19~"[16-19]", age %in%20:24~"[20-24]", age %in%25:29~"[25-29]", age %in%30:34~"[30-34]", age %in%35:39~"[35-39]", age %in%40:44~"[40-44]", age %in%45:49~"[45-49]", age %in%50:54~"[50-54]", age %in%55:59~"[55-59]", age %in%60:64~"[60-64]", age %in%65:69~"[65-69]", age %in%70:74~"[70-74]", age %in%75:79~"[75-79]", age %in%80:84~"[80-84]", age %in%85:89~"[85-89]", age >=90~"90+",TRUE~"error" ),age_categ =factor(age_categ, levels =c("[16-19]", "[20-24]", "[25-29]", "[30-34]", "[35-39]", "[40-44]", "[45-49]", "[50-54]", "[55-59]", "[60-64]", "[65-69]", "[70-74]", "[75-79]", "[80-84]", "[85-89]", "90+" )) )ggplot(data = accidents |>count(age_categ) |>filter(!is.na(age_categ)), mapping =aes(x = age_categ, y = n)) +geom_bar(stat ="identity") +labs(x =NULL, y =NULL, title ="Number of Drivers in Fatal Crashes by Age Group (France, 2024)",subtitle ="Source: Ministère de L'Intérieur" ) +theme_minimal(base_size =14) +theme(plot.title.position ="plot", axis.text.x =element_text(angle =45, hjust =1))
This chart could tempt you into some questionable conclusions:
Are 16-19 year-olds better drivers than 20-24 year-olds?
Is there no decline in driving ability among the elderly?
Warning
The absolute number of fatal crashes is not the same as the relative risk of a fatal crash. Different age groups don’t drive the same amount. The exposure differs completely across groups.
Correcting for Exposure
Code
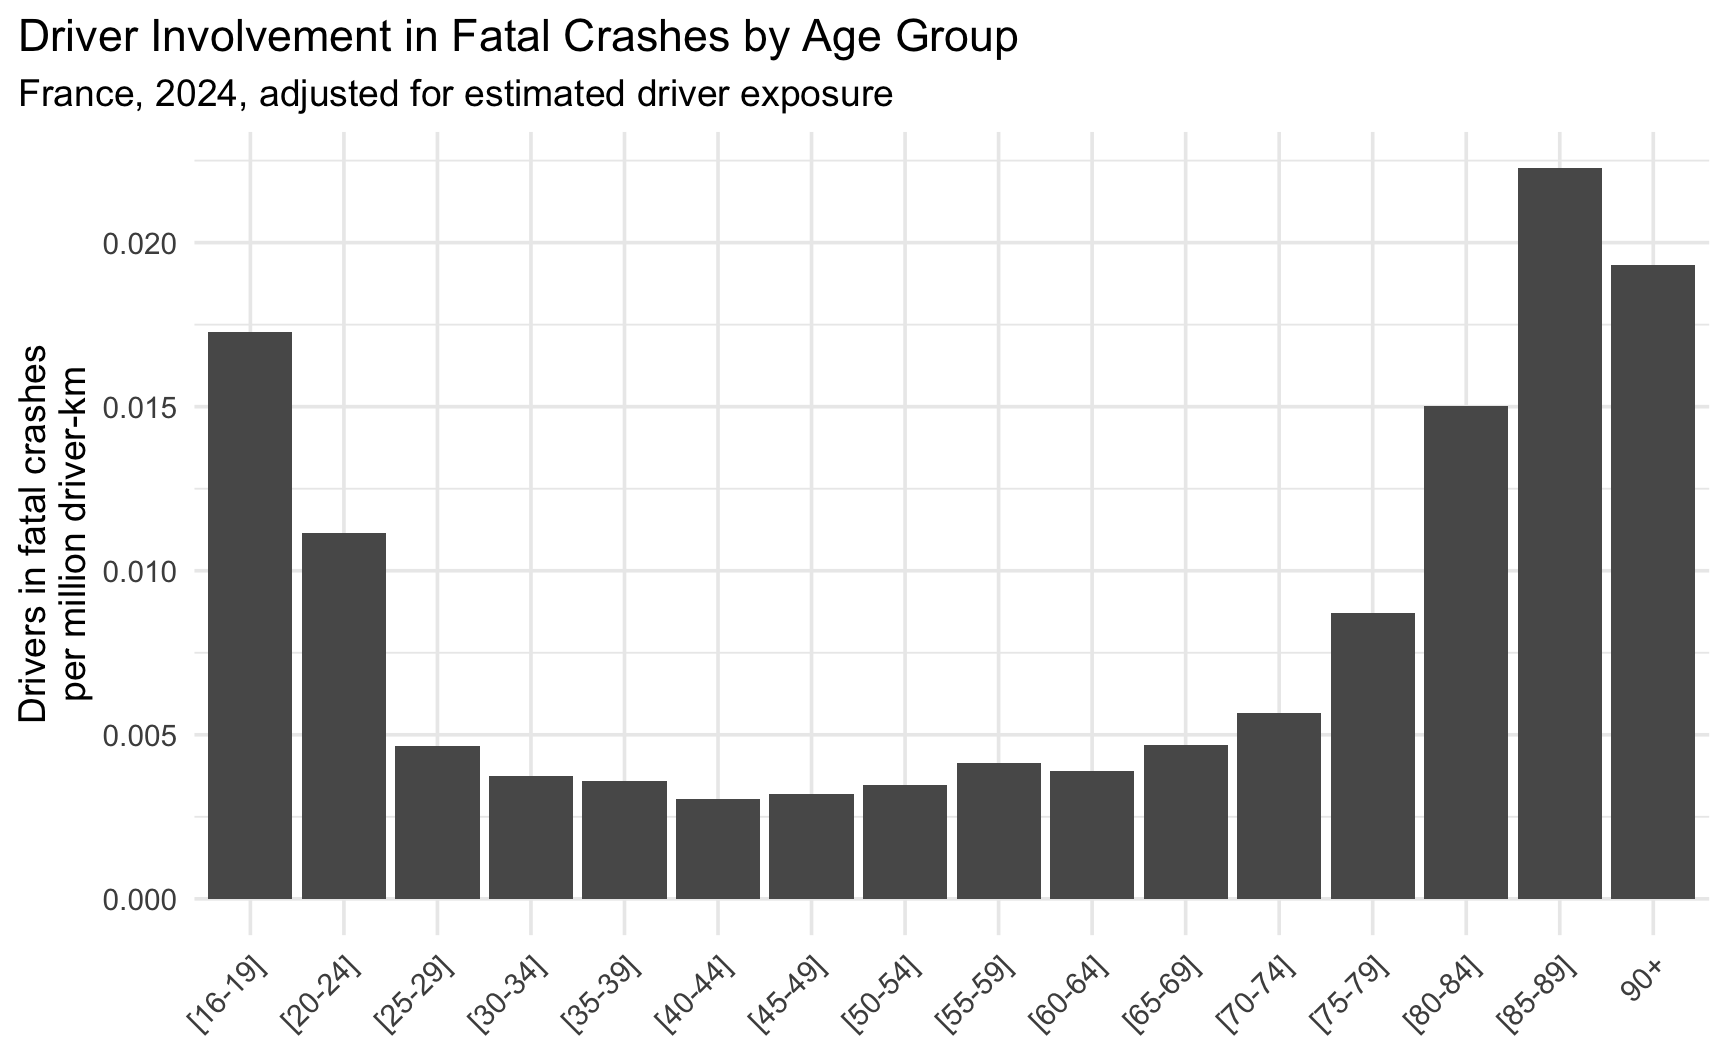
# Illustrative reconstructed estimates — NOT official statistics.# Based on interpolating France's 2018–2019 Enquête Mobilité des Personnes (SDES)# and ONISR / Kantar Enquête Parc Auto by age group.tb_conduct <-tribble(~age_categ, ~Population, ~Conducteurs_estimes, ~Taux_estime,"[16-19]", 3414463, 1042520, 0.305,"[20-24]", 3962084, 2459888, 0.621,"[25-29]", 3887931, 3557371, 0.915,"[30-34]", 4059181, 3711415, 0.914,"[35-39]", 4309100, 3856144, 0.895,"[40-44]", 4371443, 3911889, 0.895,"[45-49]", 4138342, 3700874, 0.894,"[50-54]", 4515825, 4038869, 0.894,"[55-59]", 4408109, 4002981, 0.908,"[60-64]", 4294869, 3894901, 0.907,"[65-69]", 3948016, 3404332, 0.862,"[70-74]", 3669343, 3159940, 0.861,"[75-79]", 3154606, 2336002, 0.741,"[80-84]", 1849039, 1361439, 0.736,"[85-89]", 1341052, 975373, 0.727,"90+", 962609, 683676, 0.710)# These figures are reconstructed estimates, not official statistics. # They are based on France’s 2018–2019 Enquête Mobilité des Personnes (SDES) # and interpolated by age group. # They should be treated as indicative values, not observed data.km_parcourus_age <-tribble(~age_categ, ~km_an,"[16-19]", 8500,"[20-24]", 10500,"[25-29]", 12500,"[30-34]", 13000,"[35-39]", 13500,"[40-44]", 13500,"[45-49]", 13000,"[50-54]", 12500,"[55-59]", 11500,"[60-64]", 10500,"[65-69]", 9000,"[70-74]", 7500,"[75-79]", 6000,"[80-84]", 4500,"[85-89]", 3500,"90+", 2500)accidents_exposition <- accidents |>count(age_categ, name ="n_conducteurs") |>left_join(tb_conduct, by ="age_categ") |>left_join(km_parcourus_age, by ="age_categ") |>mutate(driver_km = Conducteurs_estimes * km_an,crashes_per_million_driver_km = n_conducteurs / driver_km *1e6 )ggplot(data = accidents_exposition |>filter(!is.na(age_categ)),mapping =aes(x = age_categ, y = crashes_per_million_driver_km)) +geom_col() +labs(x =NULL,y ="Drivers in fatal crashes\nper million driver-km",title ="Driver Involvement in Fatal Crashes by Age Group",subtitle ="France, 2024, adjusted for estimated driver exposure" ) +theme_minimal(base_size =14) +theme(plot.title.position ="plot", axis.text.x =element_text(angle =45, hjust =1) )
Once we divide by an estimate of kilometres actually driven per age group, a very different picture emerges: risk is highest among the youngest and oldest drivers. The classic U-shaped age-risk curve well documented in road safety research.
Caution
These exposure figures (population driving, km driven per year) are reconstructed illustrative estimates (with ChatGPT), not official statistics. They are interpolated from SDES/ONISR survey data for teaching purposes only. Treat them as indicative, not as a source to cite.
Always Ask “Out of What?”
Whenever you compare counts across groups, ask what the natural denominator is
Raw counts answer: “how much does this group contribute to the total?”
Rates (count ÷ exposure) answer: “how risky/likely is this outcome, for someone in this group?”
Groups rarely have the same size, activity level, or exposure. Hence, a chart of raw counts alone can make the safest group look dangerous, and vice versa, purely as an artifact of how many people (or how much activity) sits behind each bar.
This is the same principle behind incidence rates in epidemiology, crime rates per capita, or click-through rates in A/B testing: the denominator is doing as much interpretive work as the numerator.
Marine Le Pen and the Euro: A Graph Controversy
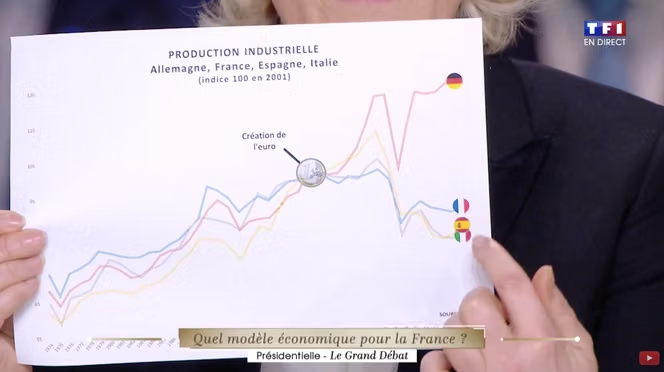
Marine Le Pen showing a chart of industrial production in the four largest economies of the eurozone during the first presidential debate, on Monday, March 20. TF1. Source: Les Décodeurs (2017)
During the first 2017 presidential debate on TF1, Marine Le Pen used a chart, shown briefly on camera, comparing industrial production in four European countries: France, Italy, Spain, and Germany (see Les Décodeurs 2017, where this example is taken from, for more details).
According to her interpretation, the chart showed “sans appel” (beyond dispute) the decline of French, Italian, and Spanish economies compared to German industry.
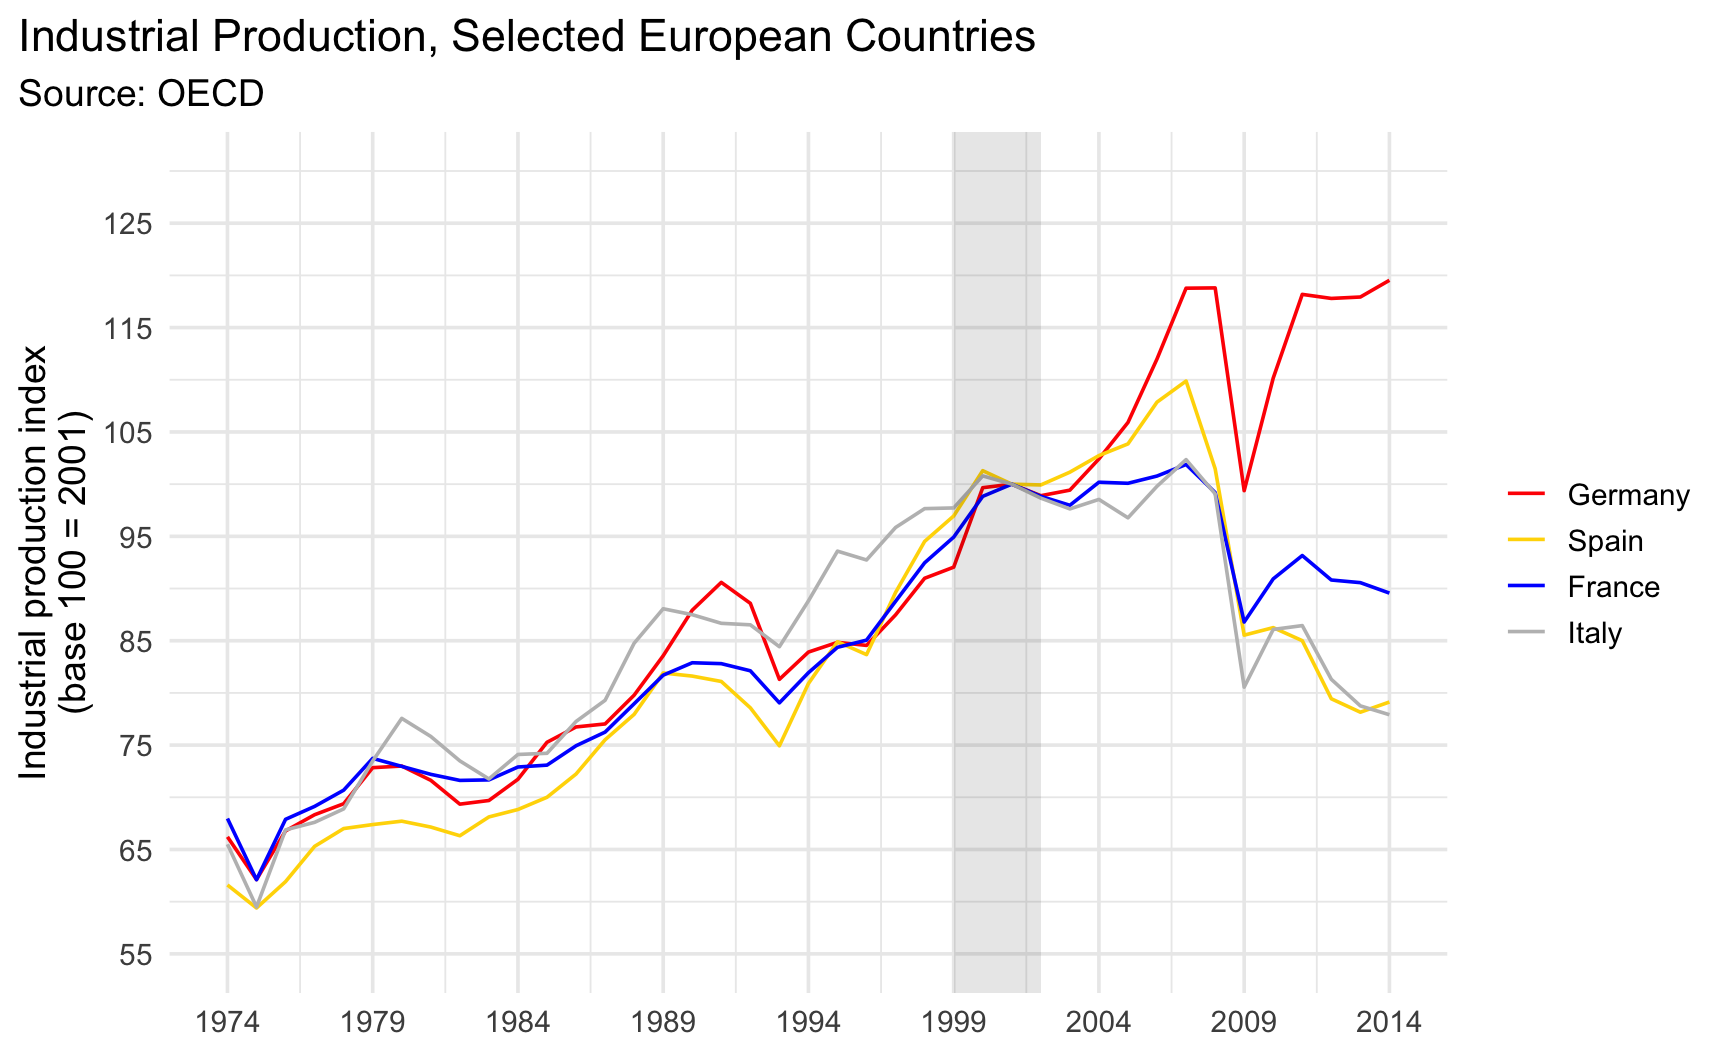
The Same Data, Base 100 in 2001
Here is a reproduction of the graph she showed on TV, using the same OECD data.
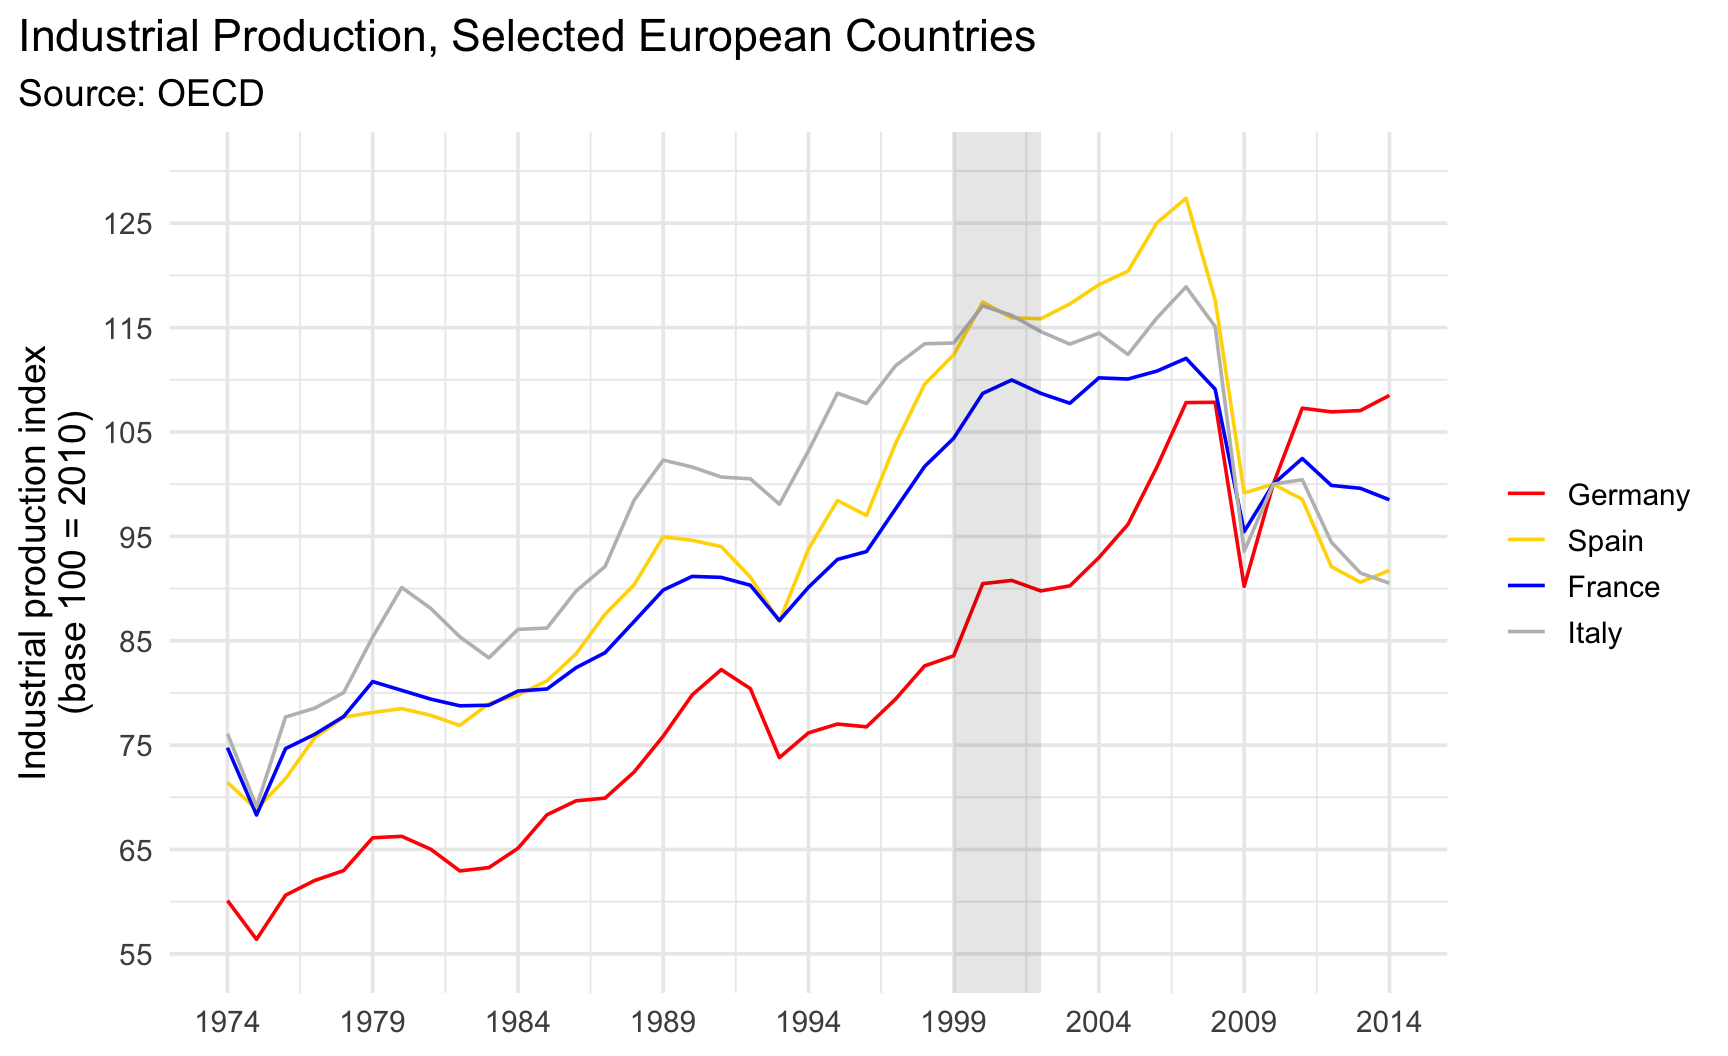
With a base of 100 in 2010 instead: same underlying dynamics, same data. However, the curves no longer cross around the early 2000s, making the chart far less dramatic.
Warning
Changing the reference year didn’t touch a single data point. It only changed where all four curves are pinned to the same value (100), which mechanically determines where they appear to “cross” or “diverge” on the chart.
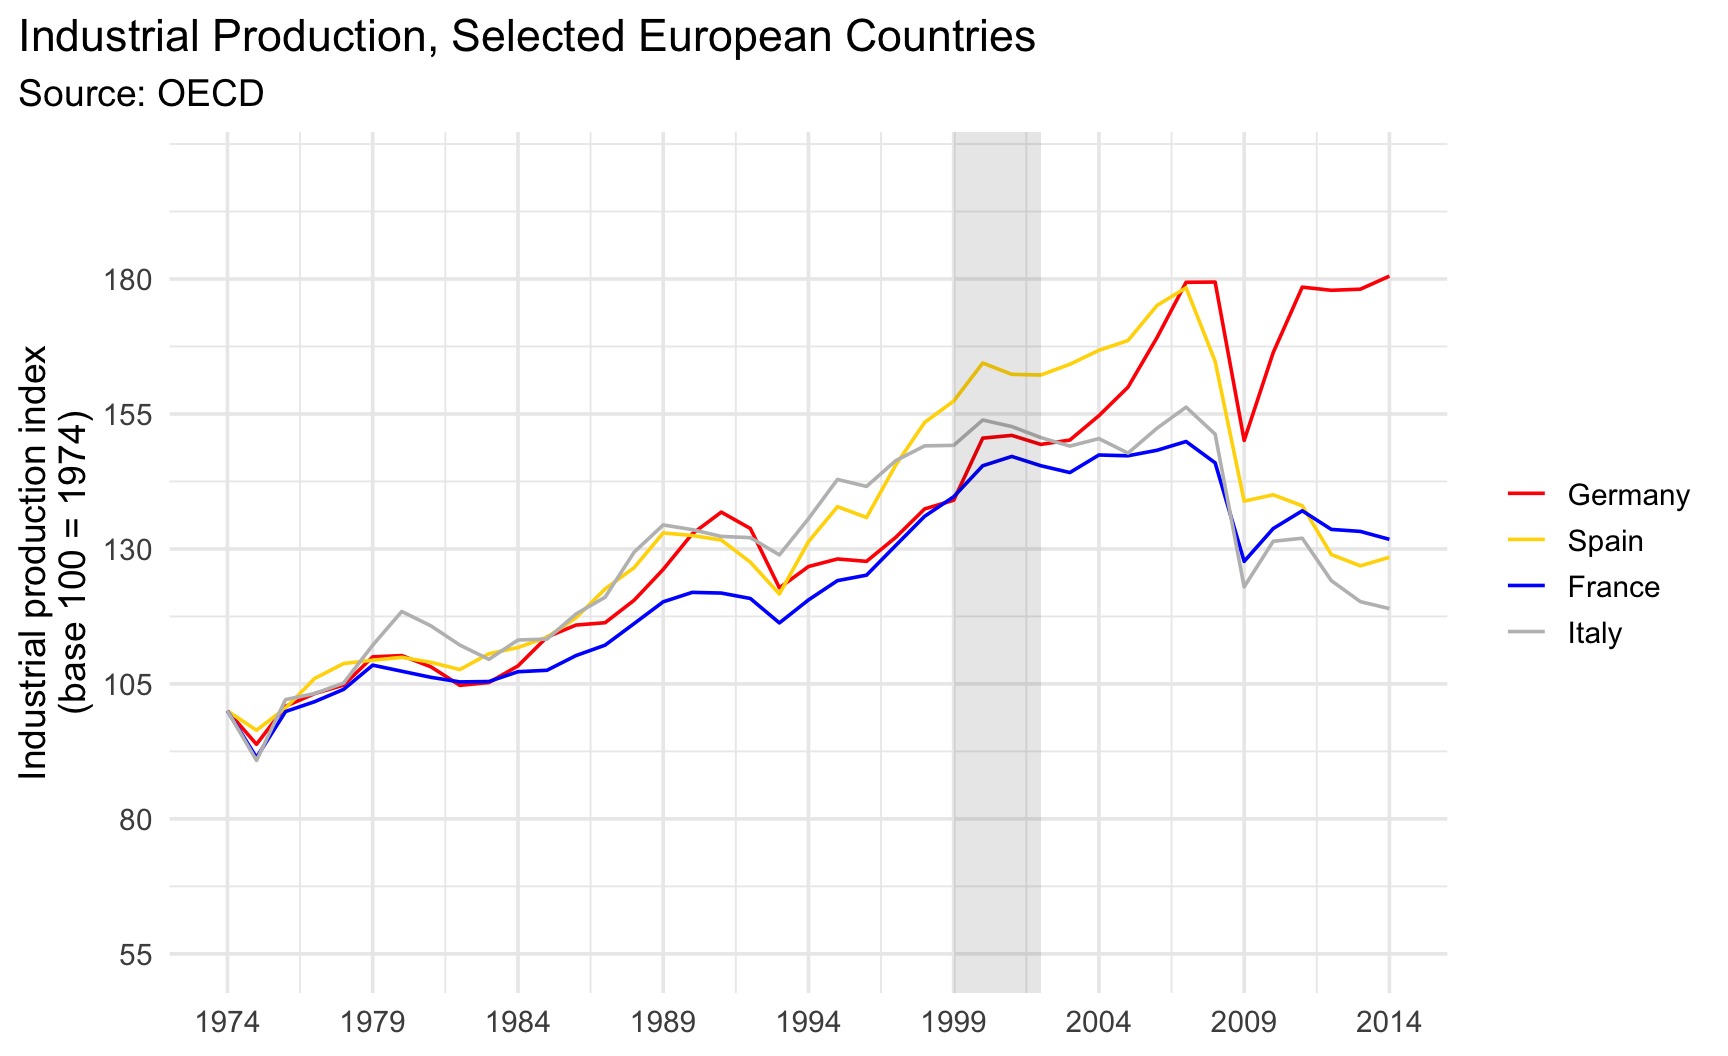
From 1974 to 2001, France and Germany grow at nearly the same pace (+47% for France, +51% for Germany), there is no sign of France “falling behind” before the euro.
The divergence becomes real and substantial only after 2001: from 2001 to 2014, France’s index actually falls by about 12%, while Germany’s rises by about 20%.
So is the euro to blame?
The timing itself isn’t manufactured here. The two countries really do start diverging close to when the euro was introduced. But correlation in timing is not proof of causation: this same window also includes Germany’s mid-2000s labour-market reforms (the Hartz reforms), sustained wage moderation, and each country’s differing exposure to the 2008 financial crisis. The chart cannot, by itself, distinguish “the euro caused this” from “several other things happened to Germany and France at around the same time.”
What a Lower Starting Point Does Not Mean
If Germany’s curve (red) sits below France’s in the 1970s–1990s, it is tempting to conclude that Germany was less productive in absolute terms than France during that period.
This is not what the chart shows.
Because both curves are pinned to the same value (100) at the reference year, a curve starting lower before reaching 100 simply means that country’s production grew proportionally more over that stretch than a curve that started higher.
It says nothing about which country produced more in absolute terms at any point.
The Reference Year Is a Choice, Not a Given
What to check whenever you see an index chart (base 100 = …)
What year was chosen as the reference, and why? A reference year immediately before a policy change (like the euro) can make everything after it look like a consequence of that change, even when the divergence started earlier or would appear regardless of the reference point.
Would the story change with a different reference year? If so, the “crossing” or “divergence” you’re seeing may be a property of the chosen baseline, not of the data itself.
Remember: index values compare growth, not levels.
A lower index value does not mean a lower absolute value, only a smaller change relative to whatever year was pinned to 100.
Timing correlation is not causal proof. Even when a divergence genuinely starts near a policy change, other events in the same window can be equally or more responsible.
In this example, the underlying data never changes, but the anchor point you choose to normalize against can dramatically reshape the visual story, and even a real divergence still needs more than a chart to establish its cause.
Some Rules for Good Practices
Three Rules
The Principle for Proportional Ink
Show the Data
Reduce the Clutter
Rule 1: The Principle for Proportional Ink
Rule 1: The Principle for Proportional Ink
Tufte and Graves-Morris (1983) (Chapter 2, p. 56) enunciated a principle to attenuate misperception and miscommunication on visualizations:
The representation of numbers, as physically measured on the surface of the graphic itself, should be directly proportional to the numerical quantities represented.
Bergstrom and West (2020) (Chapter 7) build on this principle to derive the principle for proportional ink:
When a shaded region is used to represent a numerical value, the size (i.e., area) of that shaded region should be directly proportional to the corresponding value.
Note
Among the examples we saw earlier, this principle is violated by the bar chart with axes that fail to reach zero.
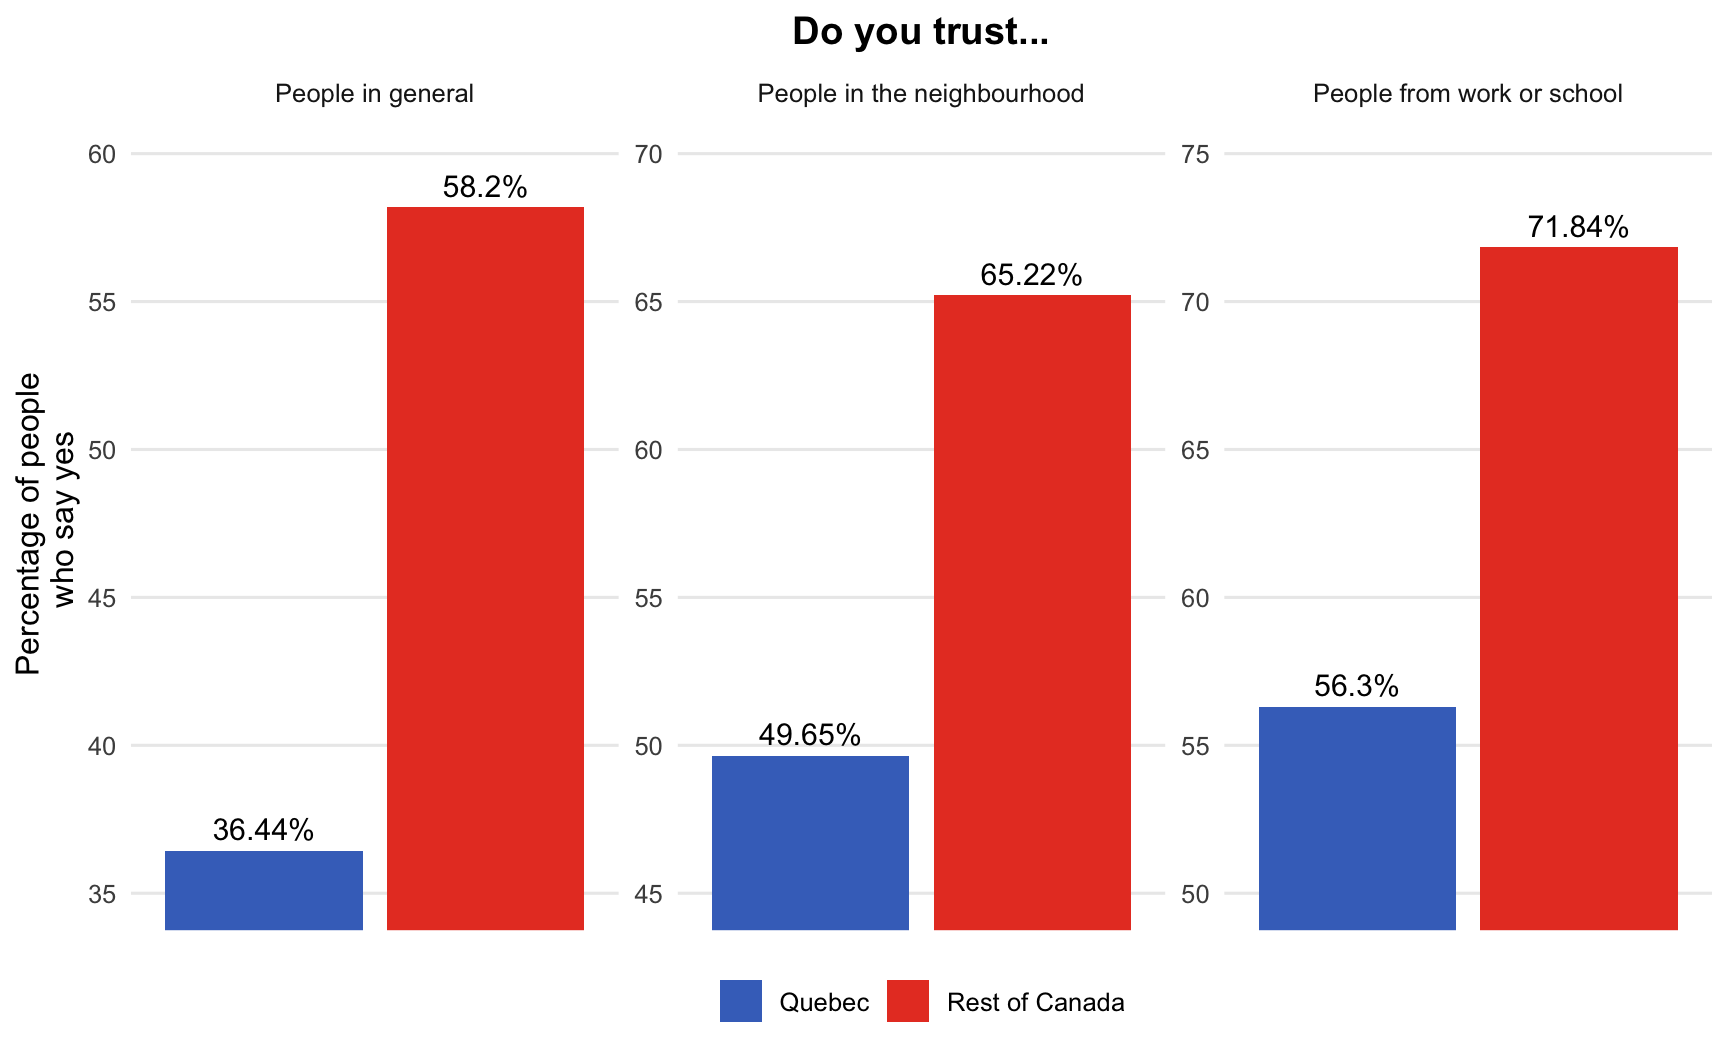
Proportional Ink: The Trust Chart, Revisited
Code
library(tidyverse)library(ggh4x)# Approximate values read off the "updated version" chart (Maclean's / Potter 2017)# Source: @Potter_2017_snowstormtrust_data <-tribble(~question, ~region, ~pct_trust,"People in general", "Quebec", 36.44,"People in general", "Rest of Canada", 58.2,"People in the neighbourhood", "Quebec", 49.65,"People in the neighbourhood", "Rest of Canada", 65.22,"People from work or school", "Quebec", 56.3,"People from work or school", "Rest of Canada", 71.84) |>mutate(question =factor(question, levels =c("People in general", "People in the neighbourhood", "People from work or school" )),x =1 )ggplot(data = trust_data,mapping =aes(x = x, y = pct_trust, fill = region)) +geom_col(position =position_dodge(width =0.9), width =0.8) +geom_text(mapping =aes(label =paste0(pct_trust, "%")),position =position_dodge(width =0.9),vjust =-0.5,size =4,show.legend =FALSE ) +facet_wrap(~ question, scales ="free_y") +facetted_pos_scales(y =list( question =="People in general"~scale_y_continuous(limits =c(35, 60)), question =="People in the neighbourhood"~scale_y_continuous(limits =c(45, 70)), question =="People from work or school"~scale_y_continuous(limits =c(50, 75)) ) ) +scale_fill_manual(NULL,values =c("Quebec"="#4472C4", "Rest of Canada"="#E8412B") ) +labs(x =NULL, y ="Percentage of people\n who say yes",title ="Do you trust..." ) +theme_minimal(base_size =12) +theme(legend.position ="bottom",panel.grid.major.x =element_blank(),panel.grid.minor =element_blank(),plot.title =element_text(hjust =0.5, face ="bold"),axis.text.x =element_blank() )
Code
ratio_value <-58.2/36.44# ratio of the actual valuesarea_qc <-1* (36.44-35) # ink area for Quebec (bar height above truncated axis)area_rest <-1* (58.2-35) # ink area for Rest of Canadaratio_area <- area_rest / area_qc # ratio of ink (areas)c(value_ratio = ratio_value, ink_ratio = ratio_area)
value_ratio   ink_ratio
   1.597146   16.111111
In the first panel, the value for the Rest of Canada (58.2%) is only about 1.6 times larger than that of Quebec (36.44%). But because the y-axis is truncated at 35, the ink (bar area) for the Rest of Canada is more than 16 times that of Quebec
This represents a tenfold exaggeration of the true ratio.
A Note: This Rule Is About Shaded Areas
Tip
The proportional ink principle applies specifically to shaded regions representing values. It does not constrain line graphs in the same way.
A bar chart emphasizes magnitudes: the bar’s area is a shaded region standing in for a value, so that area must be proportional to the value.
A line graph emphasizes changes: the line itself carries no area, so truncating its y-axis distorts the visual slope, but doesn’t violate proportional ink in the same sense.
This is why axis truncation is a much more serious violation for bar charts than for line charts!
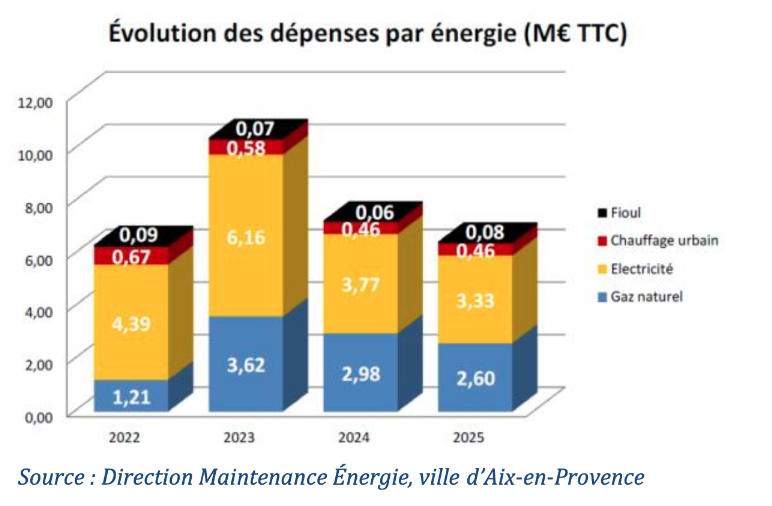
The ink used for the smallest items (Fioul) is much higher than necessary. The 3D perspective inflates the visible area of every segment, but proportionally more so for the thin parts at the top and bottom of each bar.
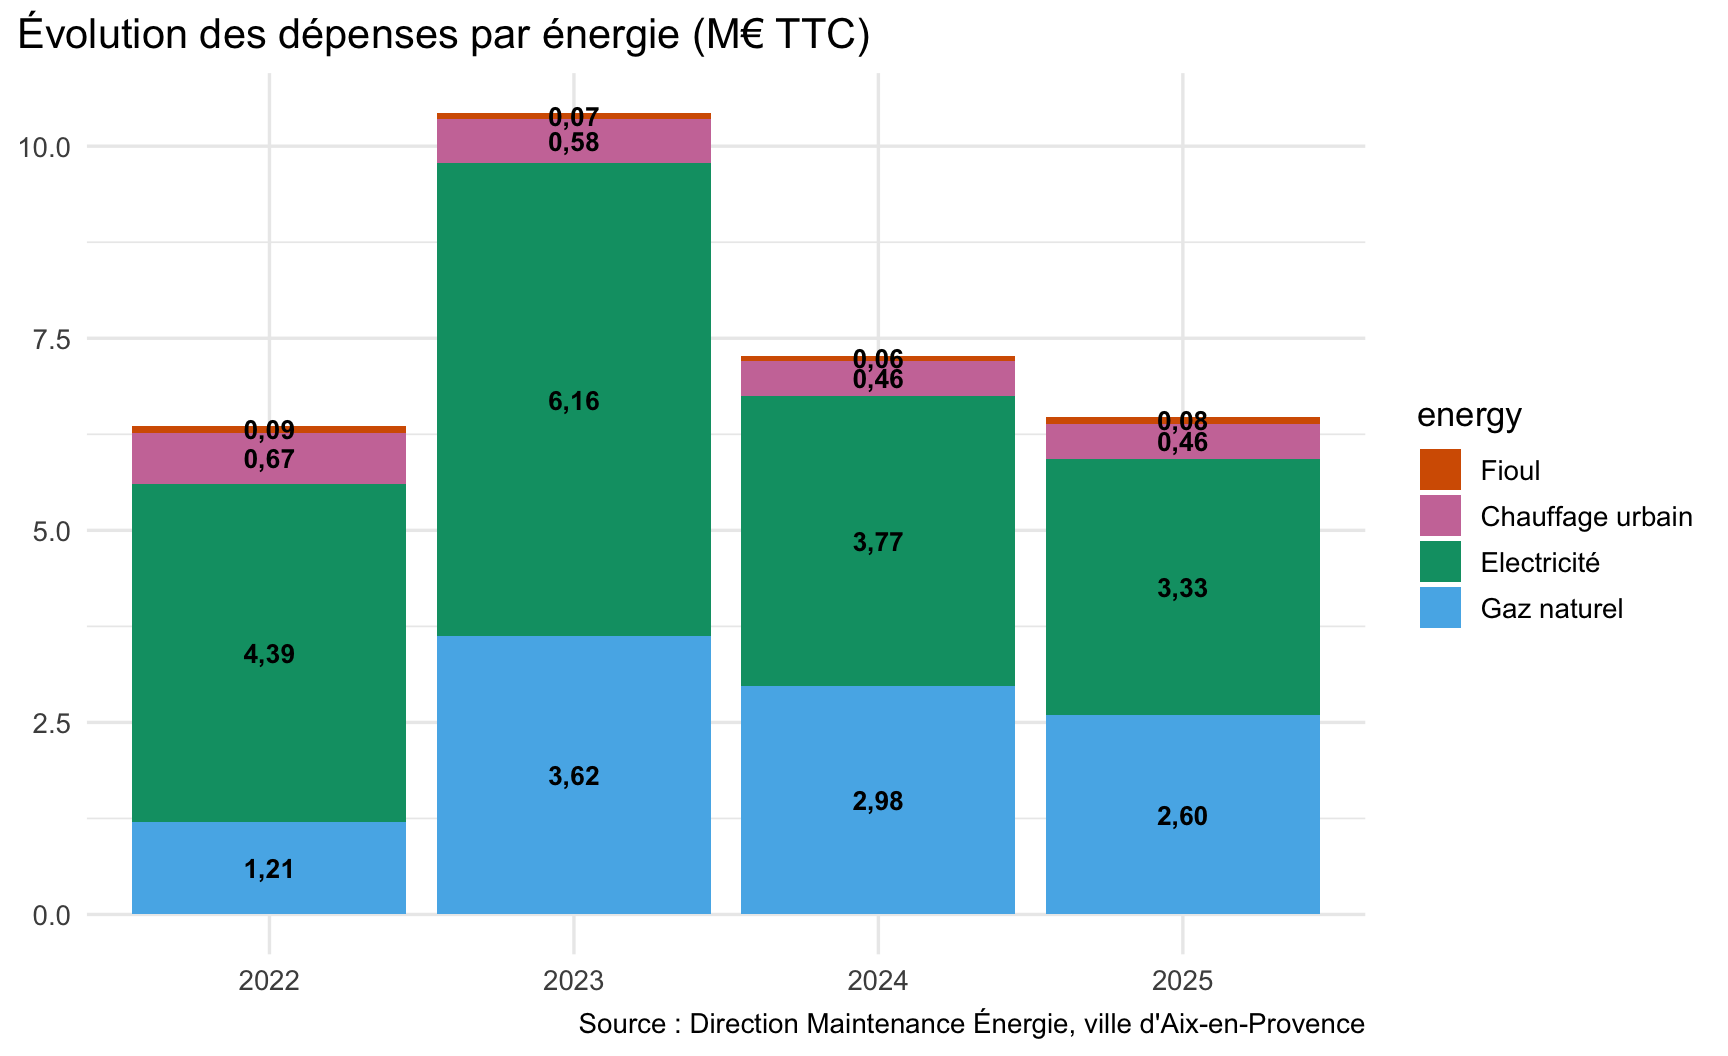
A Clean 2D Alternative
Code
library(tidyverse)# Values read off the original chart# Source: Rapport annuel sur la situation de la ville d'Aix-en-Provence en # matière de développement durable - 2025# Direction Maintenance Énergie, ville d'Aix-en-Provenceenergy_data <-tribble(~year, ~energy, ~value,2022, "Gaz naturel", 1.21,2022, "Electricité", 4.39,2022, "Chauffage urbain", 0.67,2022, "Fioul", 0.09,2023, "Gaz naturel", 3.62,2023, "Electricité", 6.16,2023, "Chauffage urbain", 0.58,2023, "Fioul", 0.07,2024, "Gaz naturel", 2.98,2024, "Electricité", 3.77,2024, "Chauffage urbain", 0.46,2024, "Fioul", 0.06,2025, "Gaz naturel", 2.60,2025, "Electricité", 3.33,2025, "Chauffage urbain", 0.46,2025, "Fioul", 0.08) |>mutate(year =factor(year),energy =factor( energy, levels =c("Fioul", "Chauffage urbain", "Electricité", "Gaz naturel")) )ggplot(data = energy_data,mapping =aes(x = year, y = value, fill = energy)) +geom_bar(stat ="identity") +geom_text(mapping =aes(label = scales::number(value, decimal.mark =",")),position =position_stack(vjust =0.5),colour ="black",fontface ="bold",size =3.5 ) +scale_fill_manual(values =c("Fioul"="#D55E00", "Chauffage urbain"="#CC79A7","Electricité"="#009E73", "Gaz naturel"="#56B4E9") ) +labs(x =NULL, y =NULL,title ="Évolution des dépenses par énergie (M€ TTC)",caption ="Source : Direction Maintenance Énergie, ville d'Aix-en-Provence" ) +theme_minimal(base_size =13) +theme(plot.title.position ="plot")
With a flat 2D stacked bar chart, every segment’s area is directly proportional to its value, there is no perspective distortion.
Here, the “Fioul” segment (the smallest) is now honestly tiny, exactly as it should be.
But this representation is still not easy to interpret if one is interested in trends within the categories.
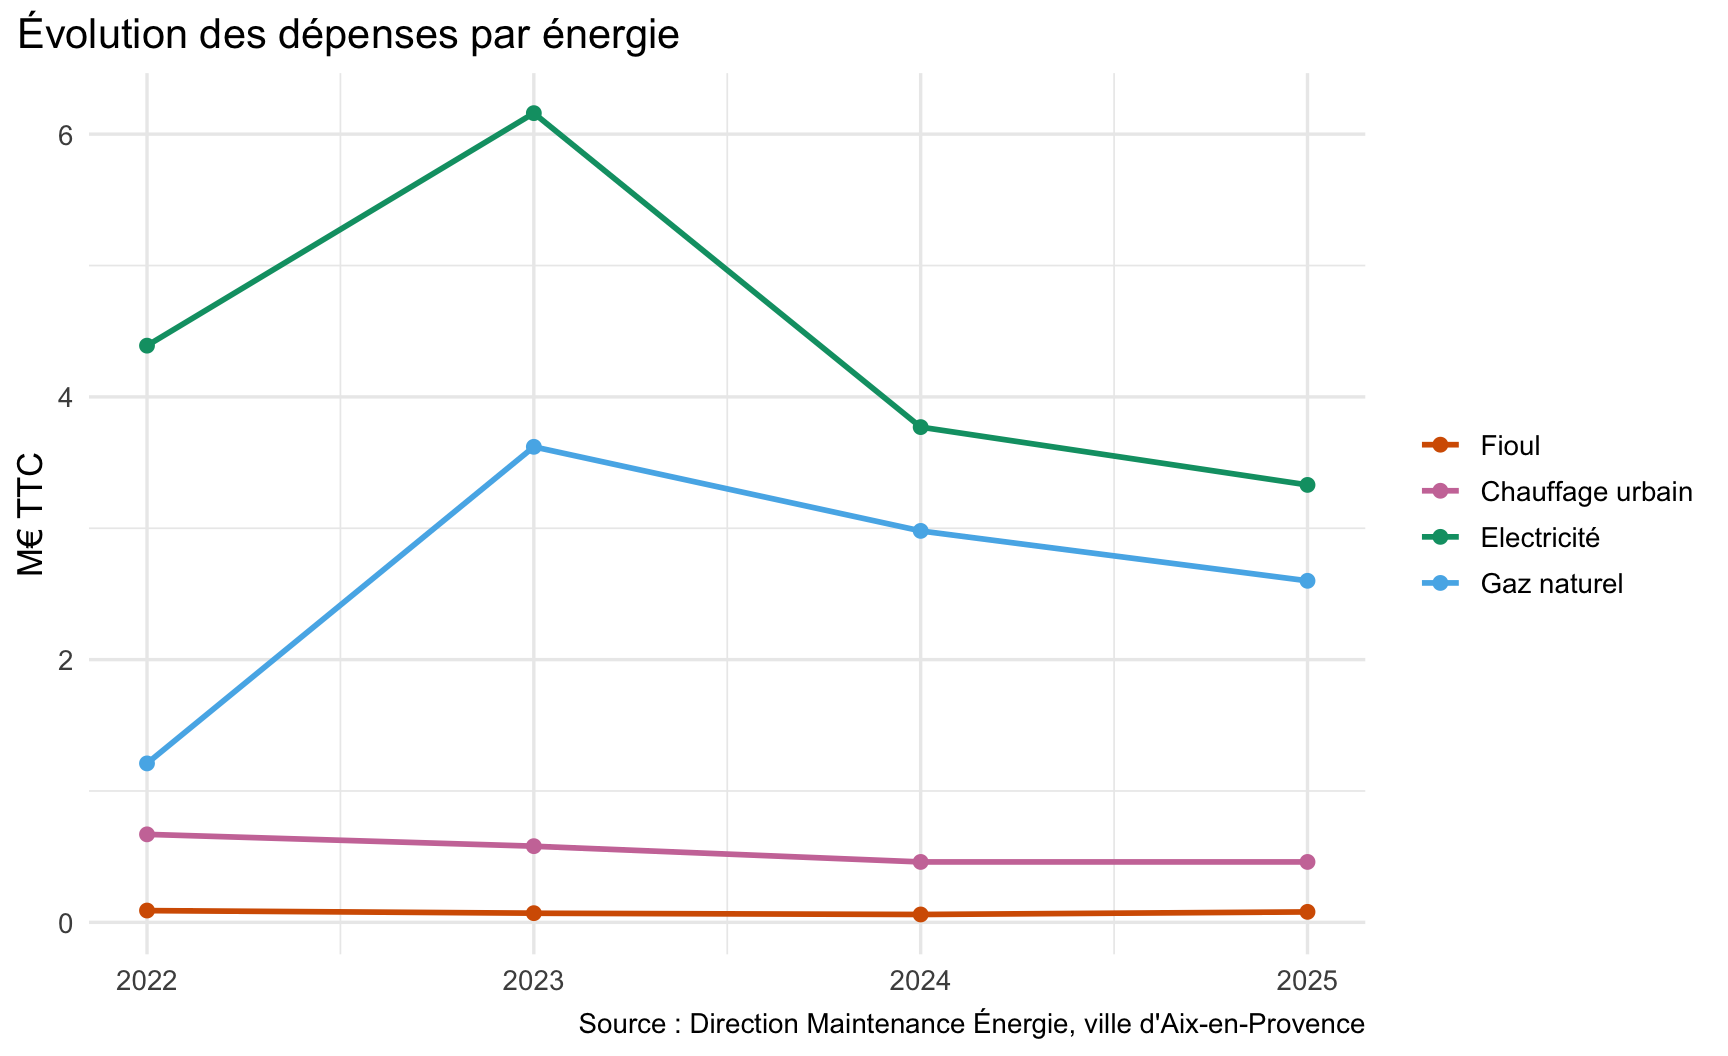
Multiple Graphs Depending on The Information to Convey
Code
ggplot(data = energy_data |>mutate(year =as.numeric(as.character(year))),mapping =aes(x = year, y = value, colour = energy)) +geom_line(linewidth =1) +geom_point(size =2) +scale_colour_manual(NULL,values =c("Fioul"="#D55E00", "Chauffage urbain"="#CC79A7","Electricité"="#009E73", "Gaz naturel"="#56B4E9") ) +scale_x_continuous(breaks =2022:2025) +labs(x =NULL, y ="M€ TTC",title ="Évolution des dépenses par énergie",caption ="Source : Direction Maintenance Énergie, ville d'Aix-en-Provence" ) +theme_minimal(base_size =13) +theme(plot.title.position ="plot")
This line chart will allow interpreting trend within categories.
But this is done at the expense of being able to observe the overall trend!
A Third View: Faceting
Code
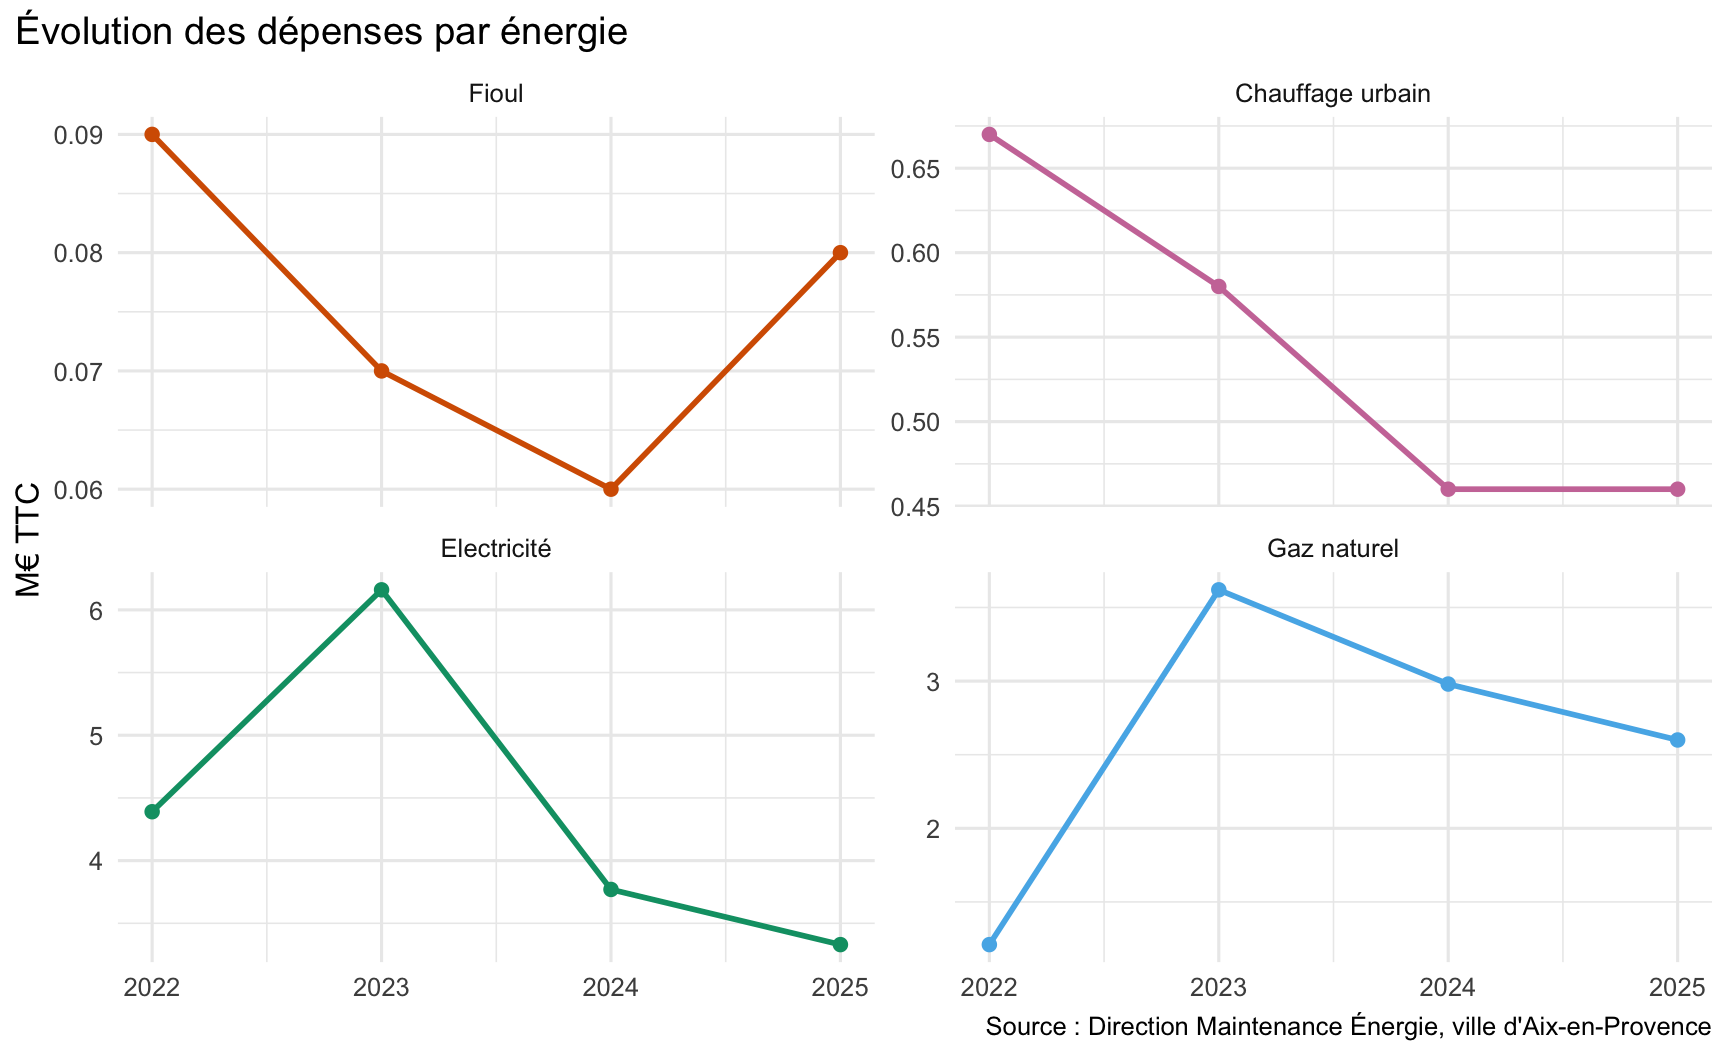
ggplot(data = energy_data |>mutate(year =as.numeric(as.character(year))),mapping =aes(x = year, y = value, colour = energy)) +geom_line(linewidth =1) +geom_point(size =2) +facet_wrap(~energy, scales ="free_y", ncol =2) +scale_colour_manual(NULL, guide ="none",values =c("Fioul"="#D55E00", "Chauffage urbain"="#CC79A7","Electricité"="#009E73", "Gaz naturel"="#56B4E9") ) +scale_x_continuous(breaks =2022:2025) +labs(x =NULL, y ="M€ TTC",title ="Évolution des dépenses par énergie",caption ="Source : Direction Maintenance Énergie, ville d'Aix-en-Provence" ) +theme_minimal(base_size =12) +theme(plot.title.position ="plot")
Faceting gives each energy source its own panel with its own y-axis, so the trend within each category becomes clearly visible, even for small categories like Fioul.
A similar pattern emerges in every panel: a rise in 2023, followed by a steady decline.
Warning
Note that faceting does not solve the overall-trend problem from the stacked bar chart: it trades one limitation for another. Each panel has its own axis range, so you can no longer read off the total spending or compare absolute magnitudes across categories. You have gained per-category trend clarity, but lost the aggregate view entirely.
3D Pie Charts and Proportional Ink Rule:
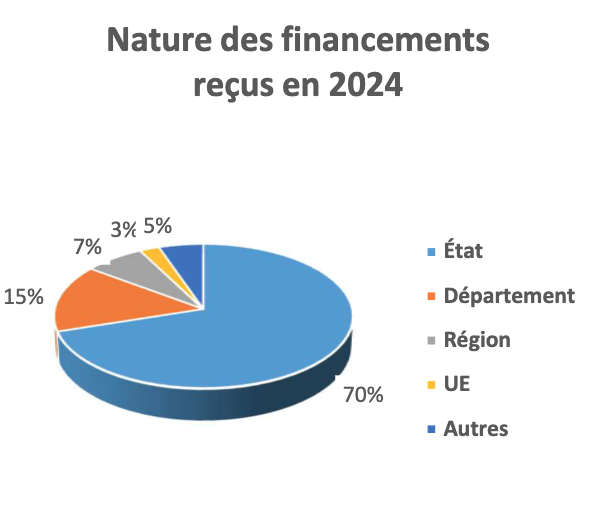
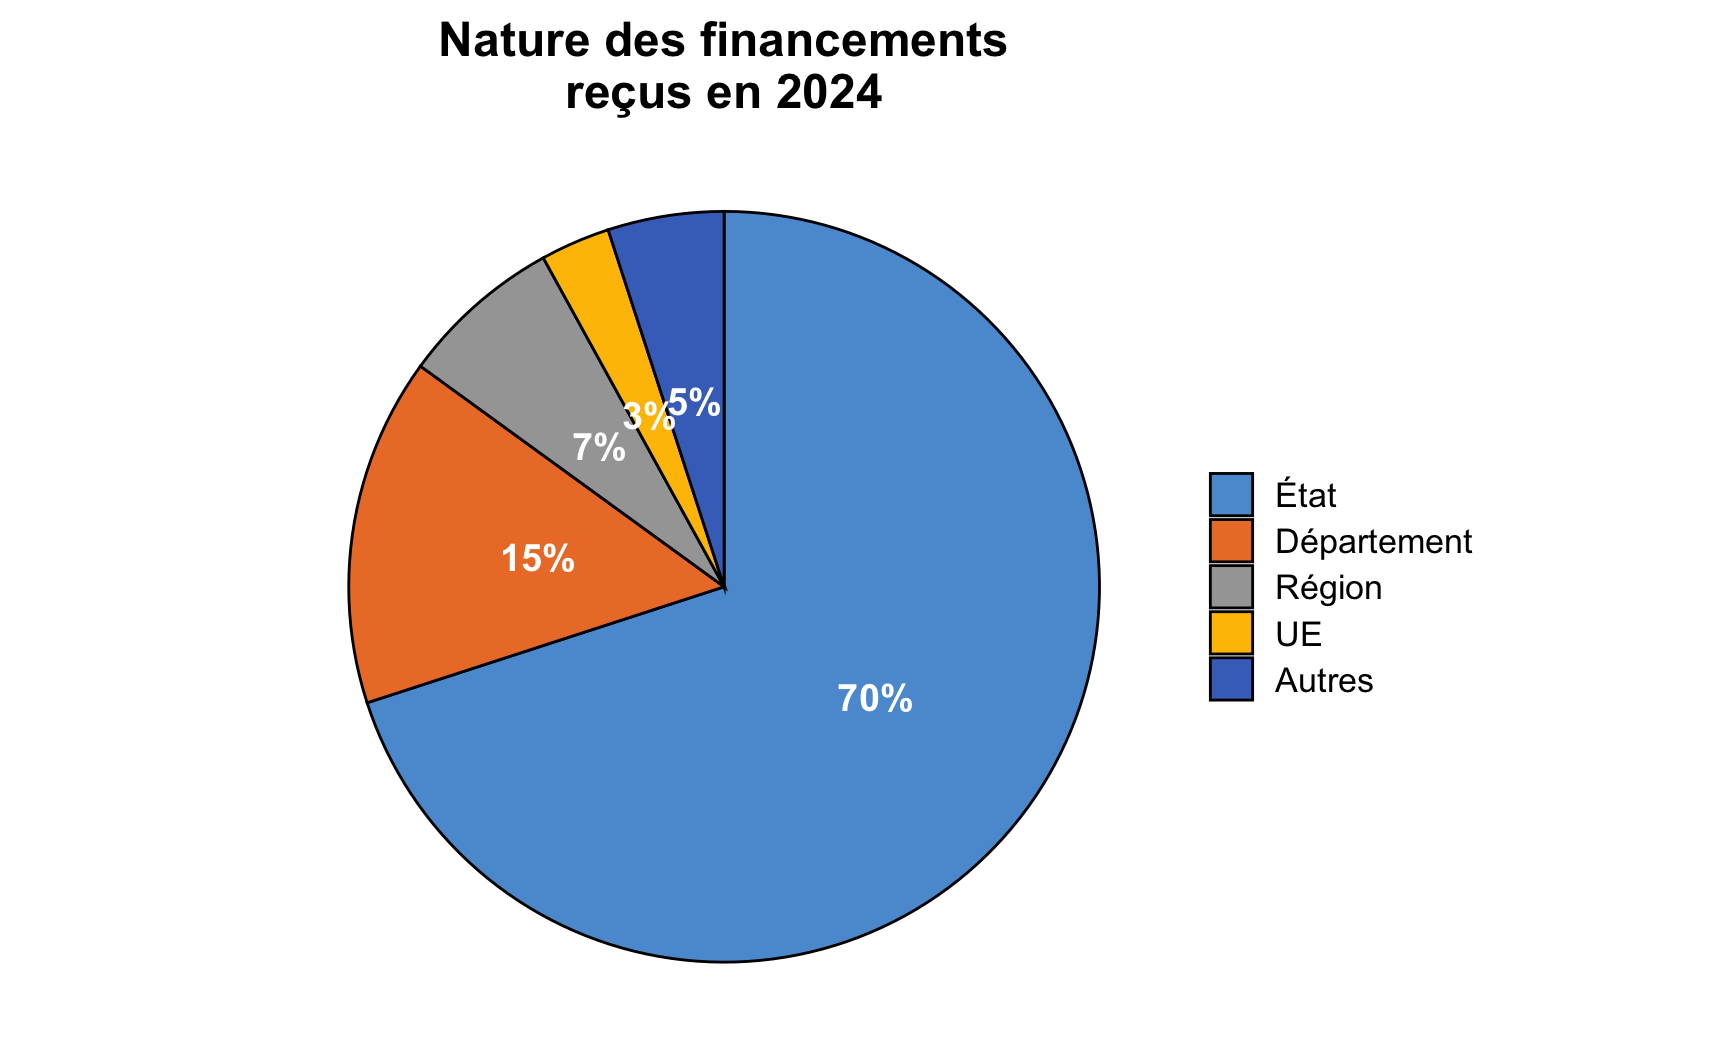
3D pie charts also suffer from an issue regarding the proportional ink rule.
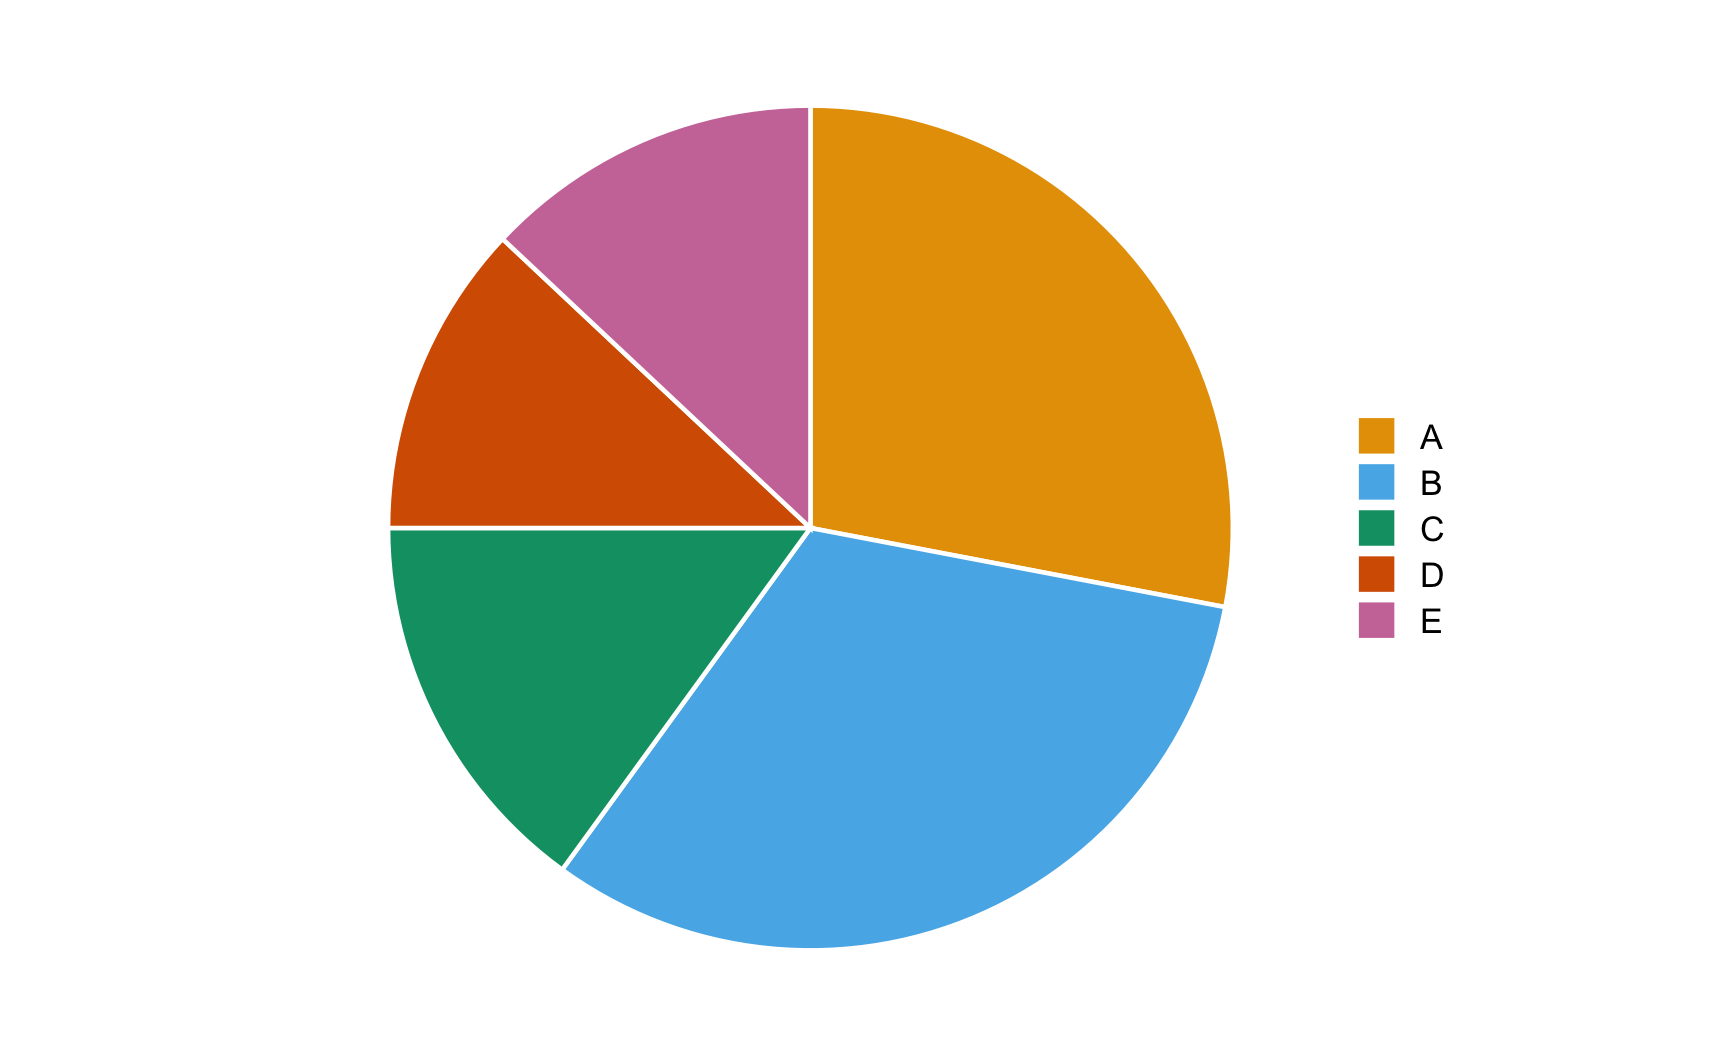
If you guessed A and D, or were not sure, you are in good company: distinguishing two similar angles is genuinely hard for the human visual system: Cleveland and McGill (1984) found in their classic study ranking how accurately people judge different visual encodings: position/length is decoded far more accurately than angle or area.
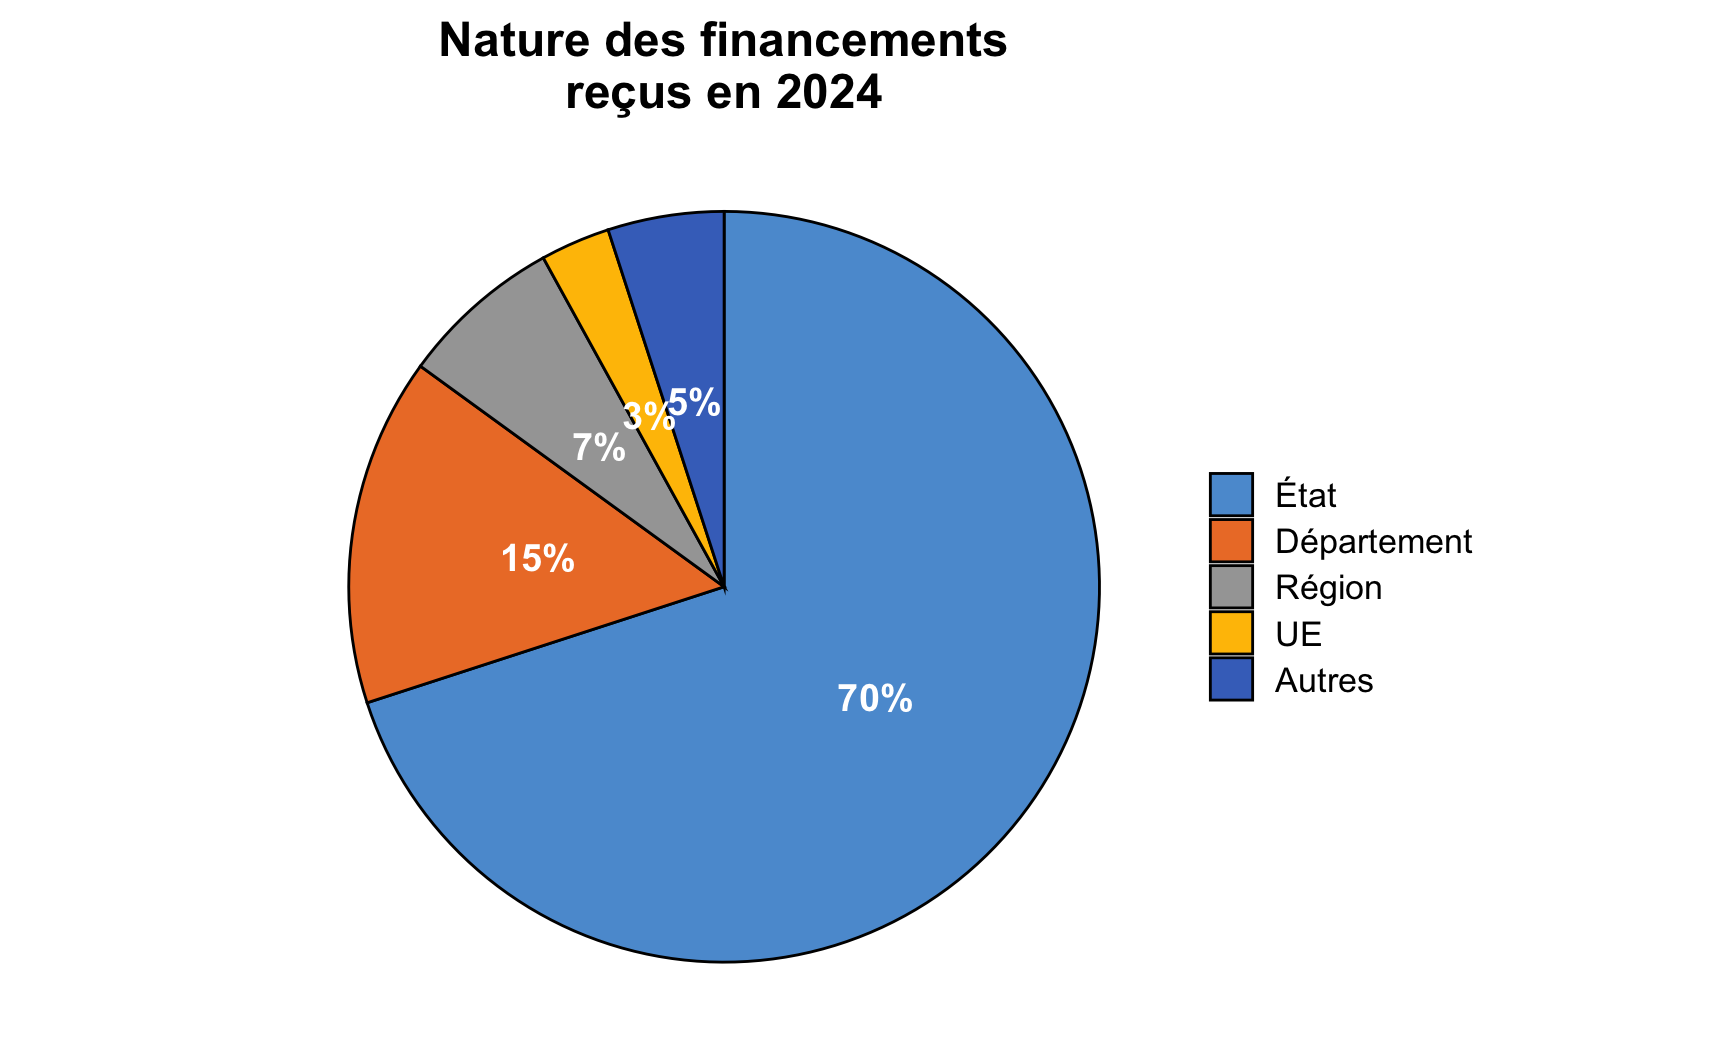
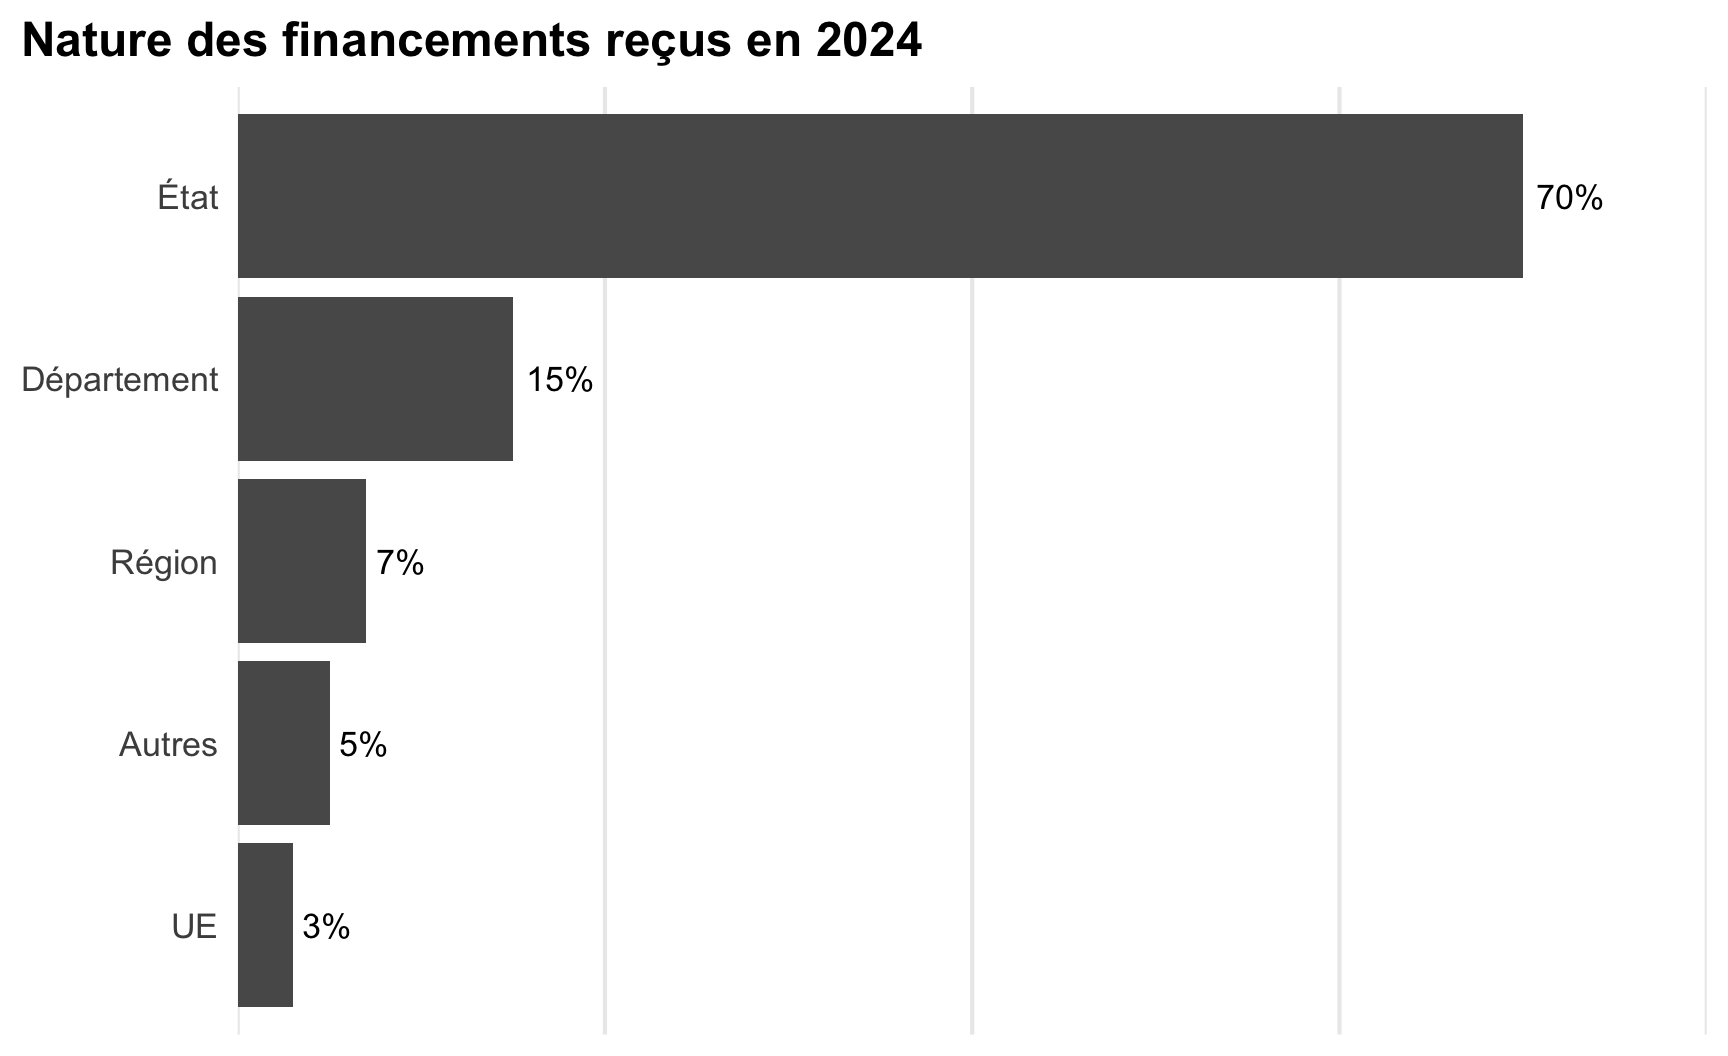
Using the bar chart, the same values as those shown earlier in the pie chart are almost instantly comparable.
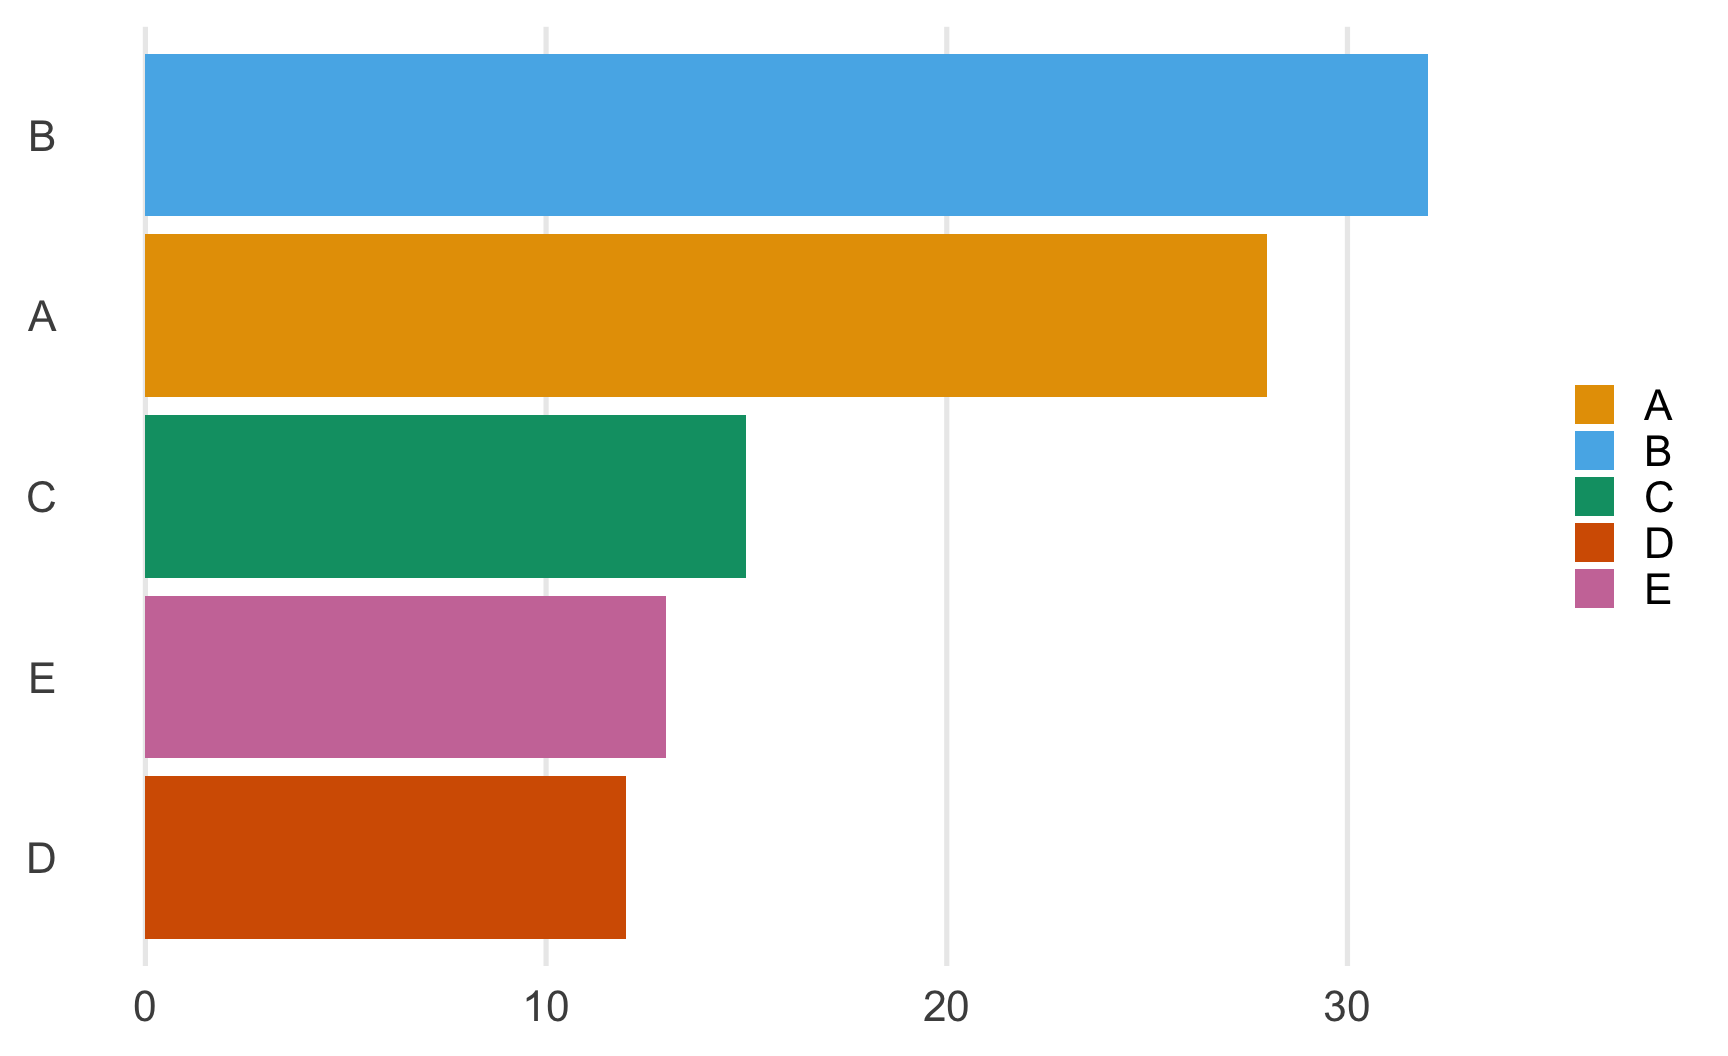
Note that in the bar chart, ordering the categories from largest to smallest lets readers compare at a glance.
Rule 2: Show the Data
Rule 2: Show the Data
When the dataset allows, having a look at the data by means of simple visualization, such as a scatterplot for exampe, allows you to:
get an idea of the data’s structure
spot potential outliers, and question whether they might be an error in the data
In the first chapter of the book, Healy (forthcoming) mentions four fictitious data from Anscombe (1973), with \(n=10\) obserbation per dataset:
x1
x2
x3
x4
y1
y2
y3
y4
10
10
10
8
8.04
9.14
7.46
6.58
8
8
8
8
6.95
8.14
6.77
5.76
13
13
13
8
7.58
8.74
12.74
7.71
9
9
9
8
8.81
8.77
7.11
8.84
11
11
11
8
8.33
9.26
7.81
8.47
14
14
14
8
9.96
8.10
8.84
7.04
6
6
6
8
7.24
6.13
6.08
5.25
4
4
4
19
4.26
3.10
5.39
12.50
12
12
12
8
10.84
9.13
8.15
5.56
7
7
7
8
4.82
7.26
6.42
7.91
5
5
5
8
5.68
4.74
5.73
6.89
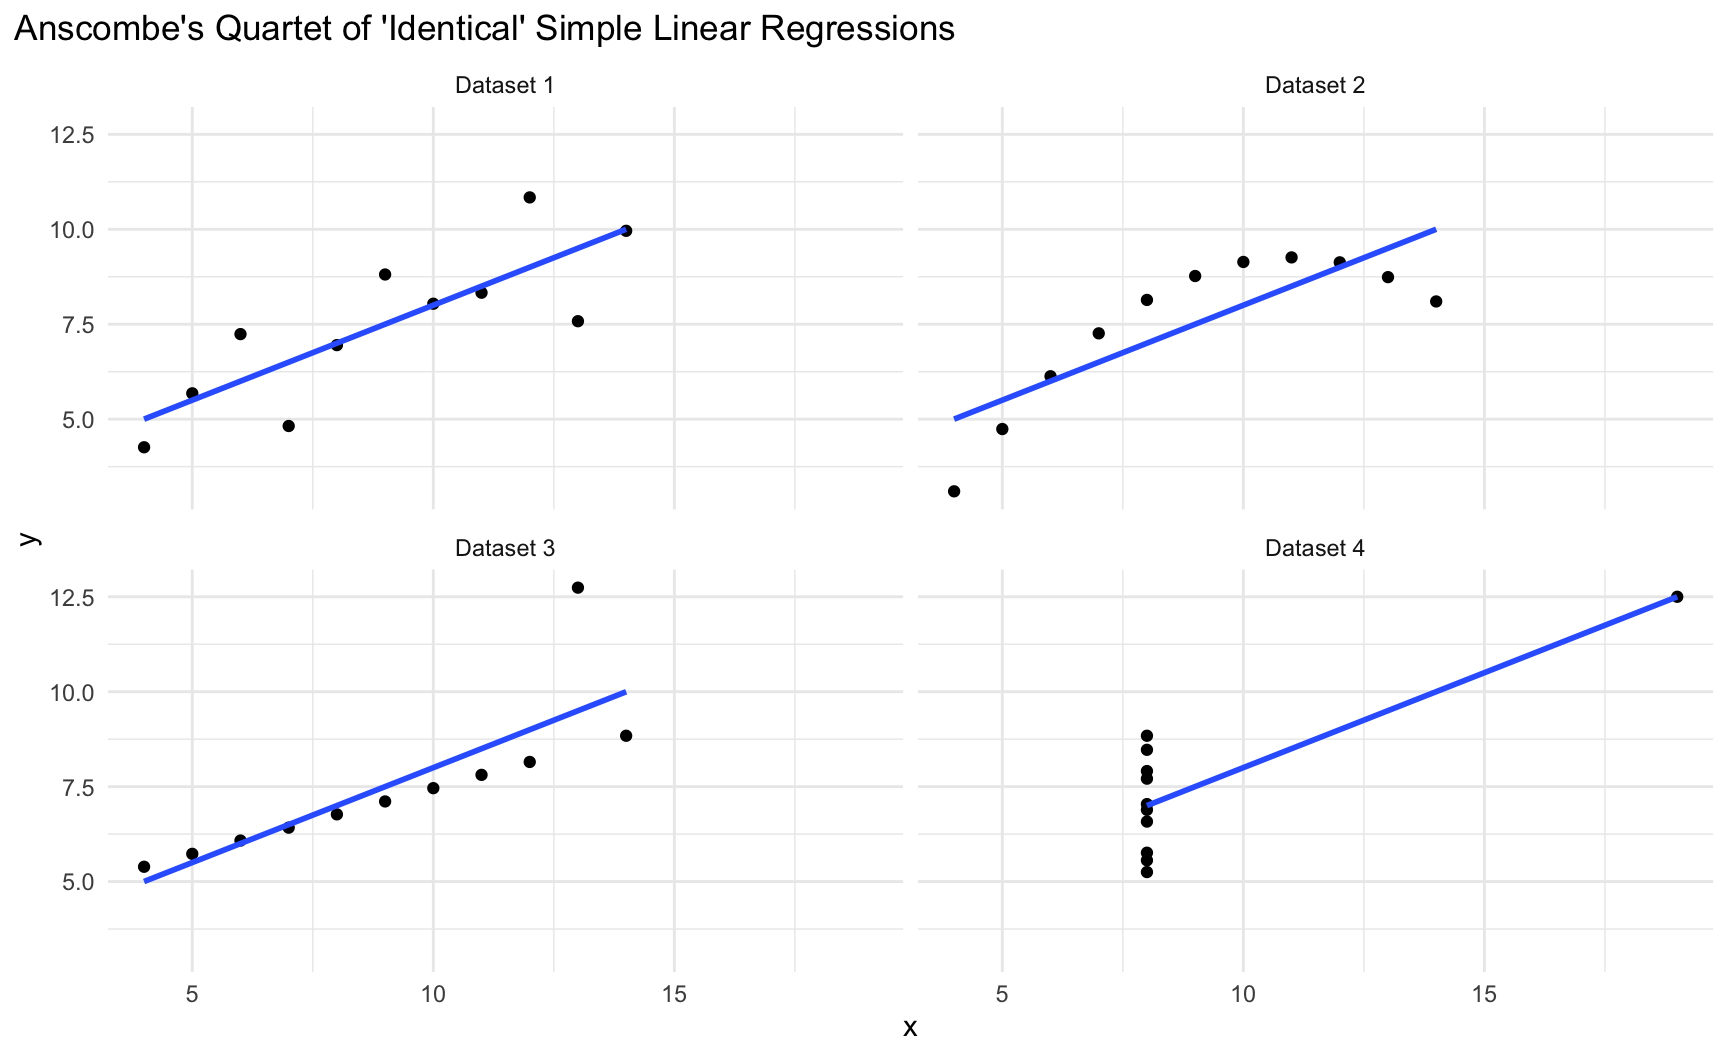
Four different datasets :
same mean for x, nearly the same mean for y,
and the same strong correlation (0.81) in every single one.
Code
# Fictitious data from Anscombe (1973)tb_anscombe <- anscombe |>select(x = x1, y = y1) |>mutate(dataset ="Dataset 1") |>bind_rows( anscombe |>select(x = x2, y = y2) |>mutate(dataset ="Dataset 2") ) |>bind_rows( anscombe |>select(x = x3, y = y3) |>mutate(dataset ="Dataset 3") ) |>bind_rows( anscombe |>select(x = x4, y = y4) |>mutate(dataset ="Dataset 4") )# Four fictitious datasets, each with n=11 pairs (x,y).# Same mean for x, and almost for y in each dataset, and a strong # correlation of 0.81 between x and ytb_anscombe |>group_by(dataset) |>summarise(mean_x =mean(x), mean_y =mean(y),corr_xy =cor(x, y) ) |> knitr::kable()
dataset
mean_x
mean_y
corr_xy
Dataset 1
9
7.500909
0.8164205
Dataset 2
9
7.500909
0.8162365
Dataset 3
9
7.500000
0.8162867
Dataset 4
9
7.500909
0.8165214
By these summary numbers alone, they look identical.
Same Statistics, But…
Code
ggplot(data = tb_anscombe,mapping =aes(x = x, y = y)) +geom_point() +geom_smooth(method ="lm", se =FALSE) +facet_wrap(~ dataset, ncol =2) +labs(title ="Anscombe's Quartet of 'Identical' Simple Linear Regressions") +theme_minimal() +theme(plot.title.position ="plot")
The scatterplot reveals four completely different underlying structures:
a genuine linear relationship,
a clear non-linear curve,
a perfect line broken by a single outlier,
and a relationship driven entirely by one extreme point.
A Real Example
A real example, also cited in Healy (forthcoming) (Chapter 1) offers a real use case for the importance of looking at the data.
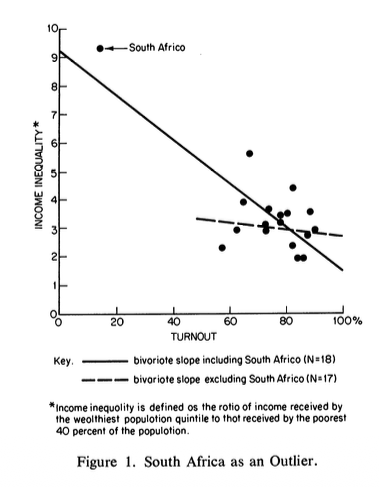
Hewitt (1977) found a significant association between voter turnout and income inequality, based on a quantitative analysis of eighteen countries (higher income inequality leading to lower voter turnout).
Jackman (1980), commenting on Hewitt’s paper, showed that this result was driven by a single observation.
Excluding that one observation from the sample changes the conclusions of Hewitt’s paper entirely.
A simple scatterplot, in this case, would have given an immediate hint that one point was doing all the work.
With big data, looking at the data directly becomes harder: you cannot just eyeball thousands or millions of points in a single scatterplot.
But exploration is still possible:
sampling subsets,
using density plots or 2D histograms instead of raw scatterplots,
computing robust statistics (such as the median) alongside standard ones can all help reveal structure and flag outliers that summary statistics alone would hide!
Rule 3: Reduce the Clutter
Rule 3: Reduce the Clutter
Schwabish (2014) offers a useful framework for thinking about chart clutter, i.e., any visual element that does not help the reader extract the underlying pattern or comparison, and instead adds cognitive load.
Common sources of clutter
Heavy gridlines, background shading, borders, and 3D effects
Redundant labels, legends, or repeated information
Textures, patterns, or excessive color variation used where simple shading would do
Too many data points or categories crammed into a single view without any grouping or summarization.
Chartjunk: Style Over Substance
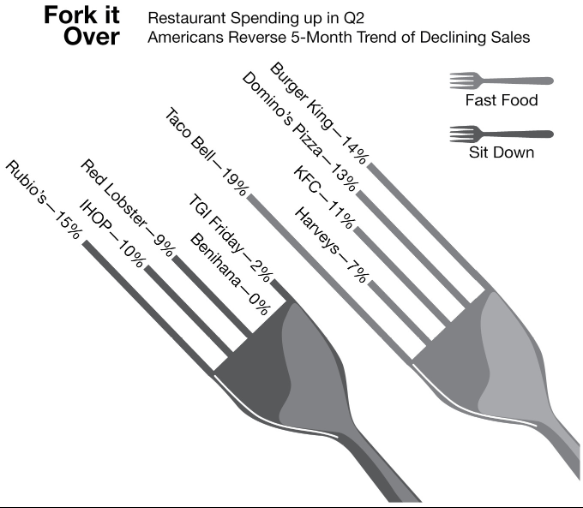
Source: A dataviz from USA Today, shown in Bergstrom and West (2020)
The bars which should convey a visual message occupy a small fraction of the total space used by the graph.
The slanted angle is unusual: it distorts the reader’s perception of the bars’ relative heights.
The two forks side by side make comparison between them more difficult.
The objective of such an eye-catching way to present data is to draw people’s attention and provide a more appealing and more distracting way to convey information.
However, it often makes it harder for the reader to really understand the content.
Fun fact
Big Duck, Long Island, USA. Photograph by Mike Peel. From Wikipedia
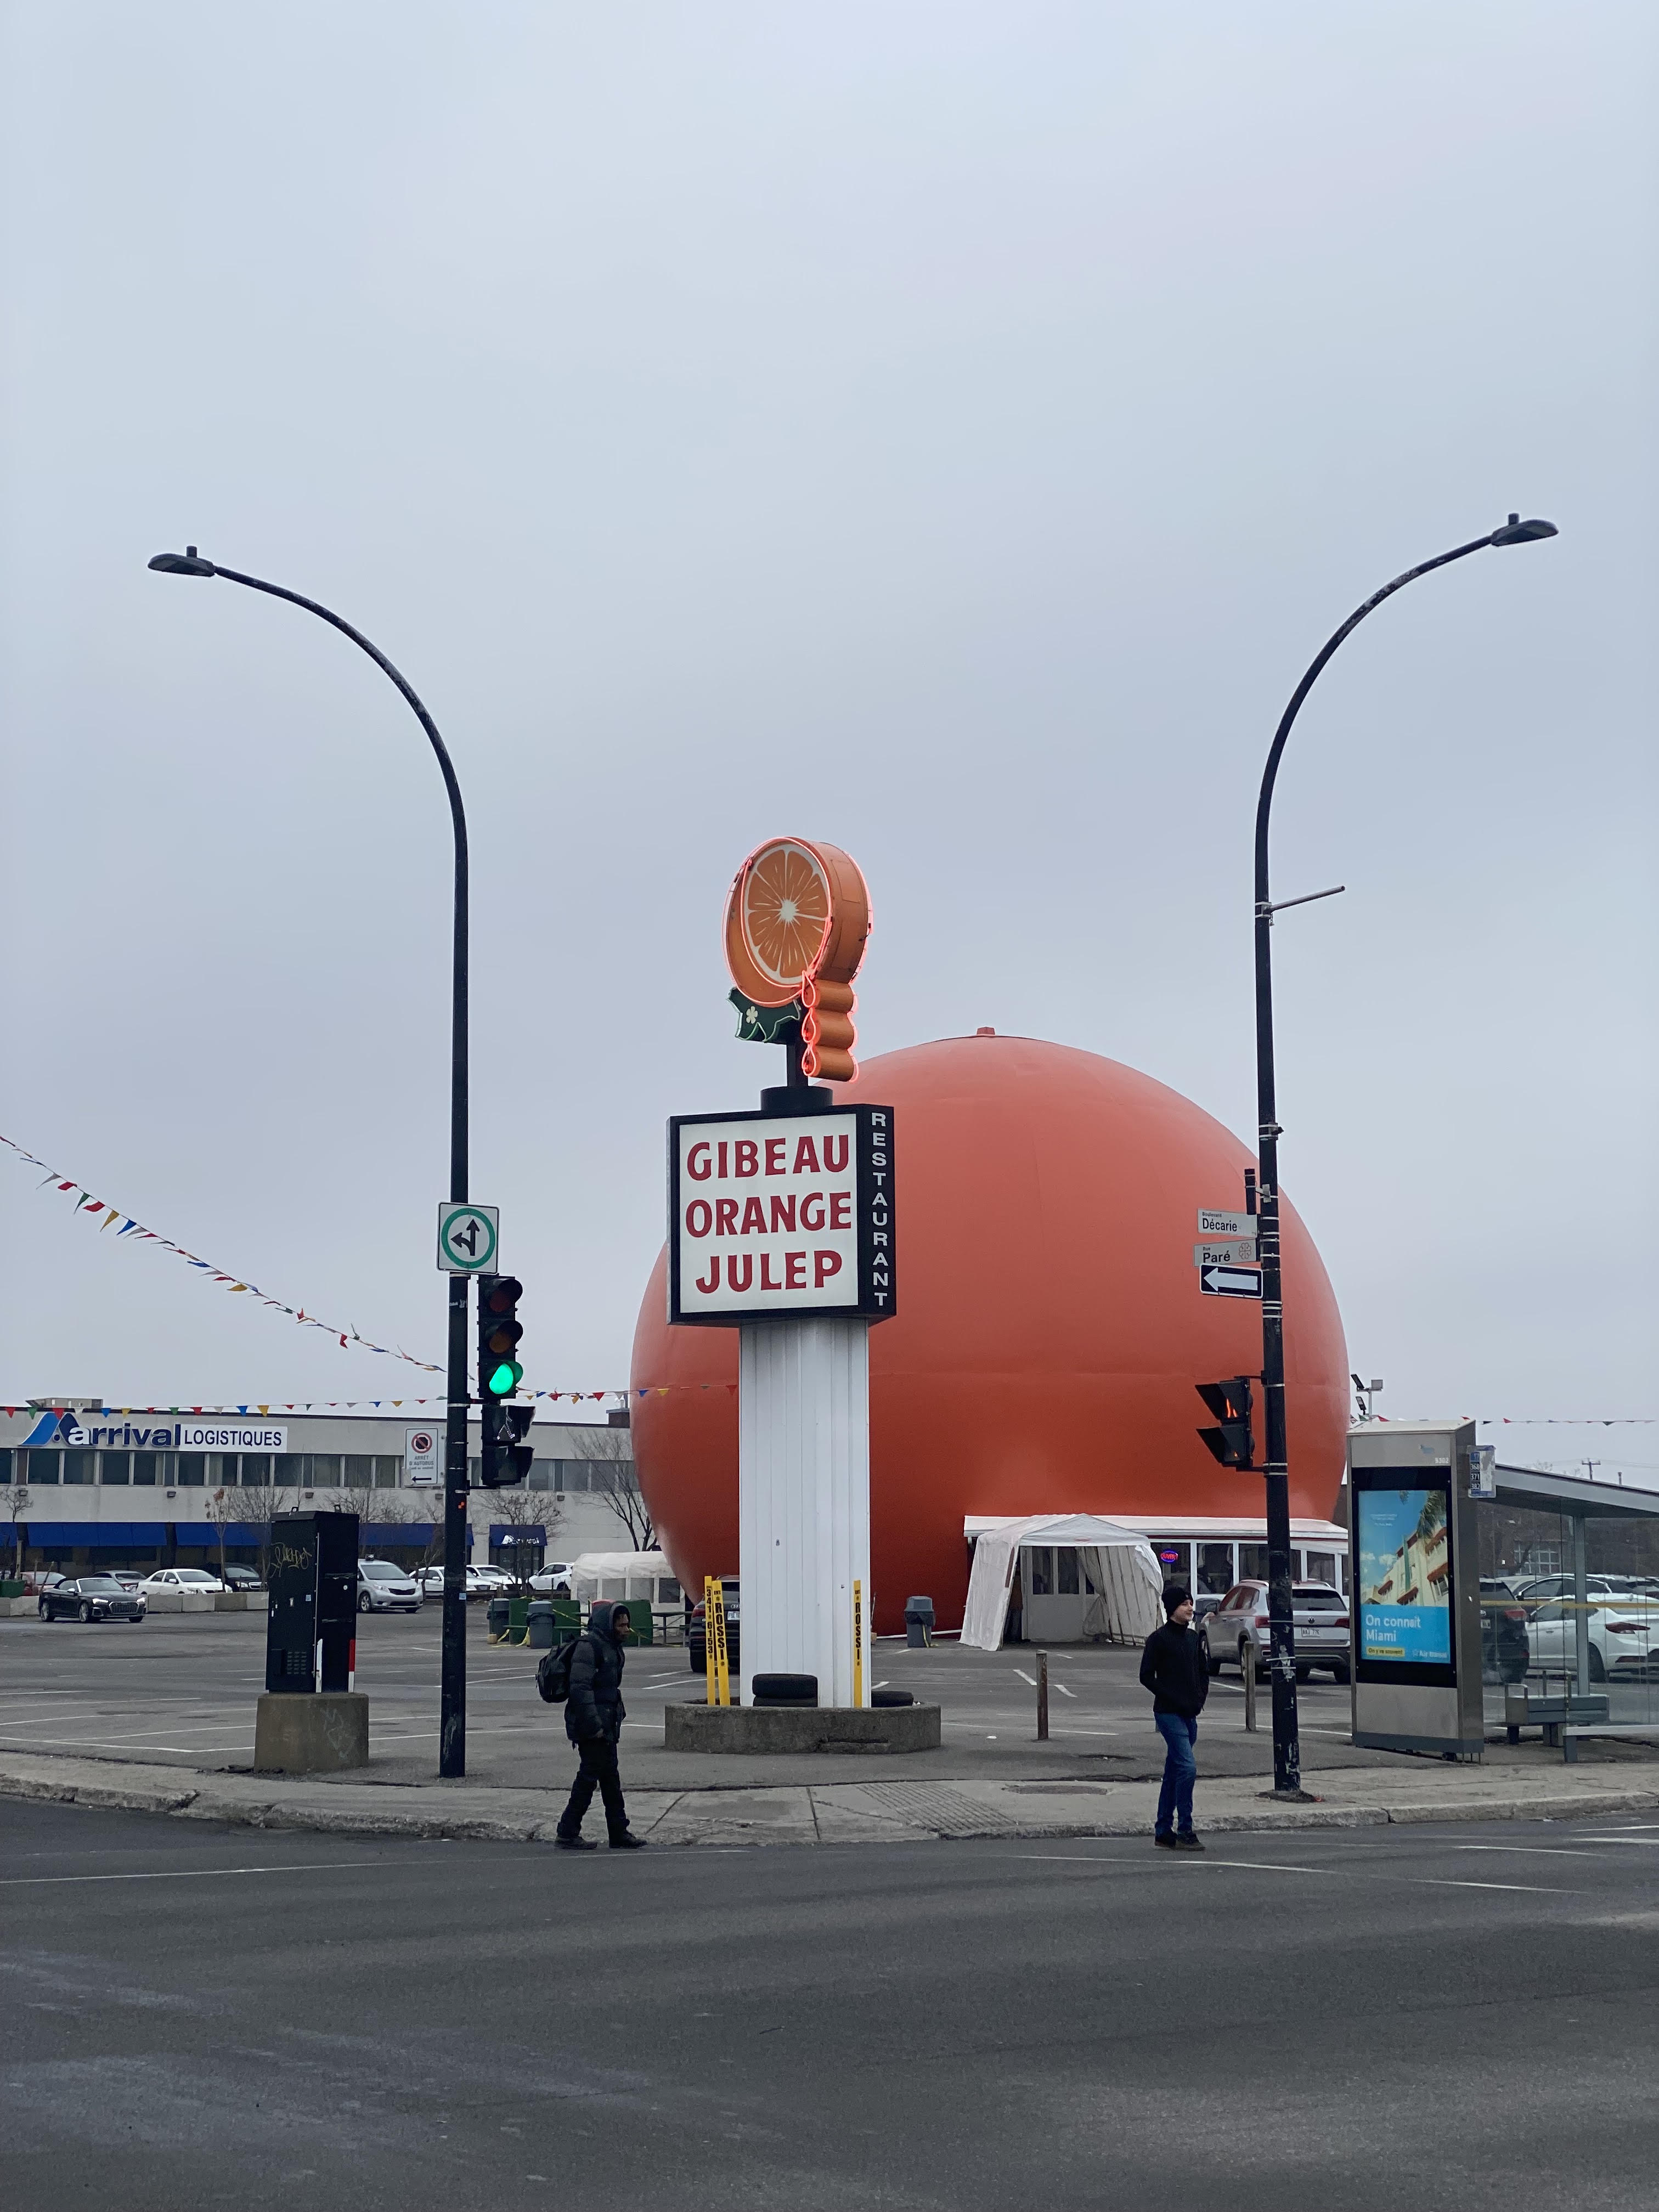
Gibeau Orange Julep, Montreal. Photograph by me.
Edward Tufte coined the term “duck” for this kind of chart, i.e., one where the decorative form overwhelms the data it is supposed to represent.
This is a term used in architecture as well, named after a Long Island building shaped like a duck, whose form serves no purpose beyond catching the eye.
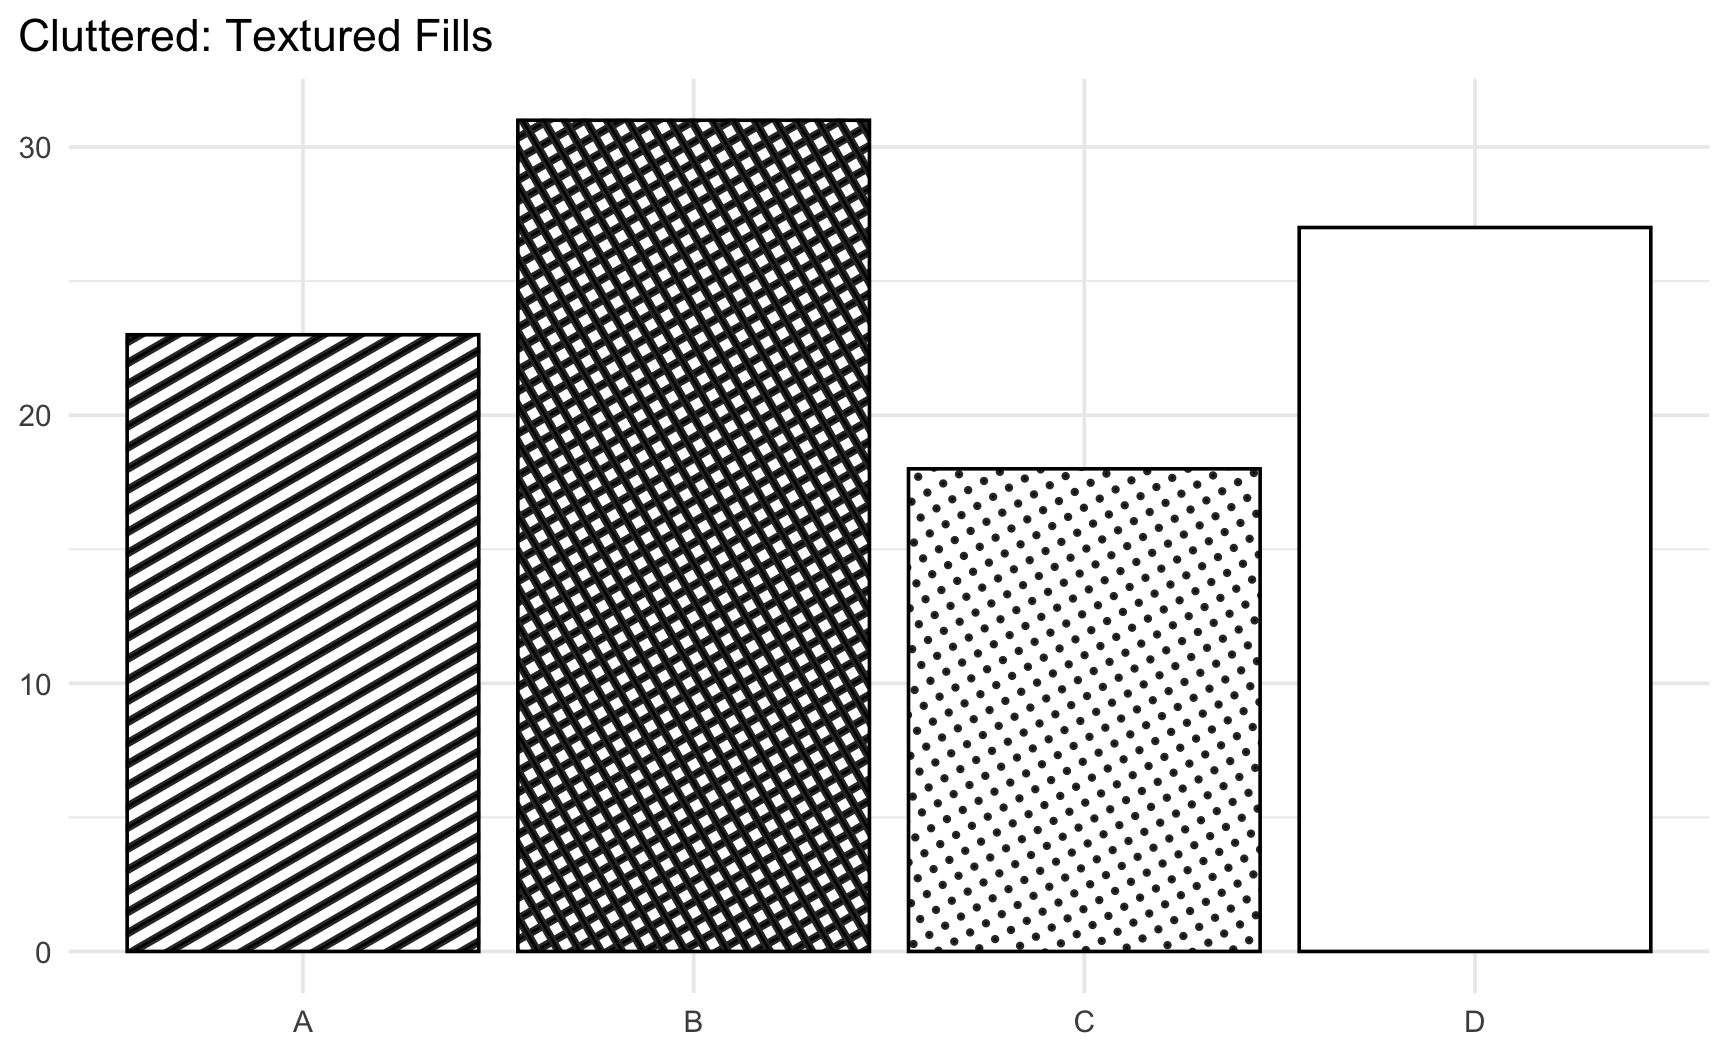
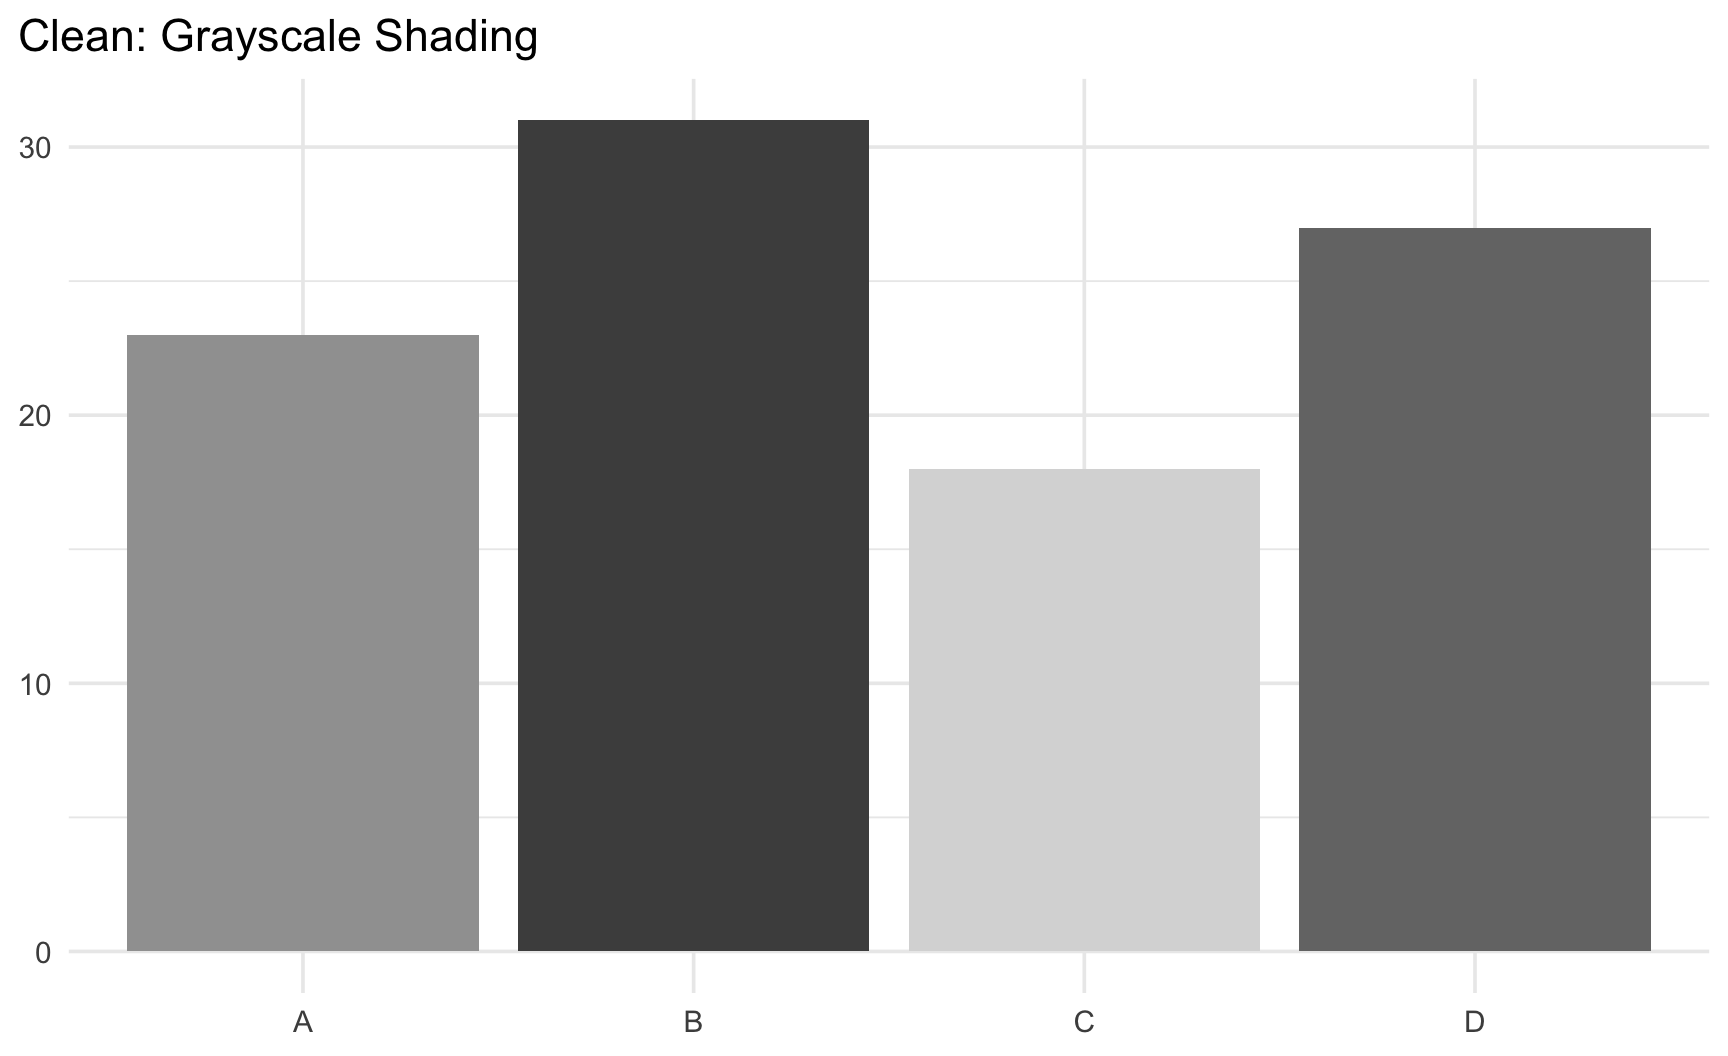
ggplot(bar_data, aes(x = category, y = value, fill = value)) +geom_col() +scale_fill_gradient(low ="grey85", high ="grey30", guide ="none") +labs(x =NULL, y =NULL, title ="Clean: Grayscale Shading") +theme_minimal(base_size =14) +theme(plot.title.position ="plot")
The textured version forces the eye to process each pattern’s fine detail before it can even register the bar’s height (the actual quantity of interest).
The grayscale version communicates the same four values with none of that extra decoding effort, and additionally uses shading to reinforce the ranking (darker = higher).
Example: Too Many Points, Too Many Markers
Code
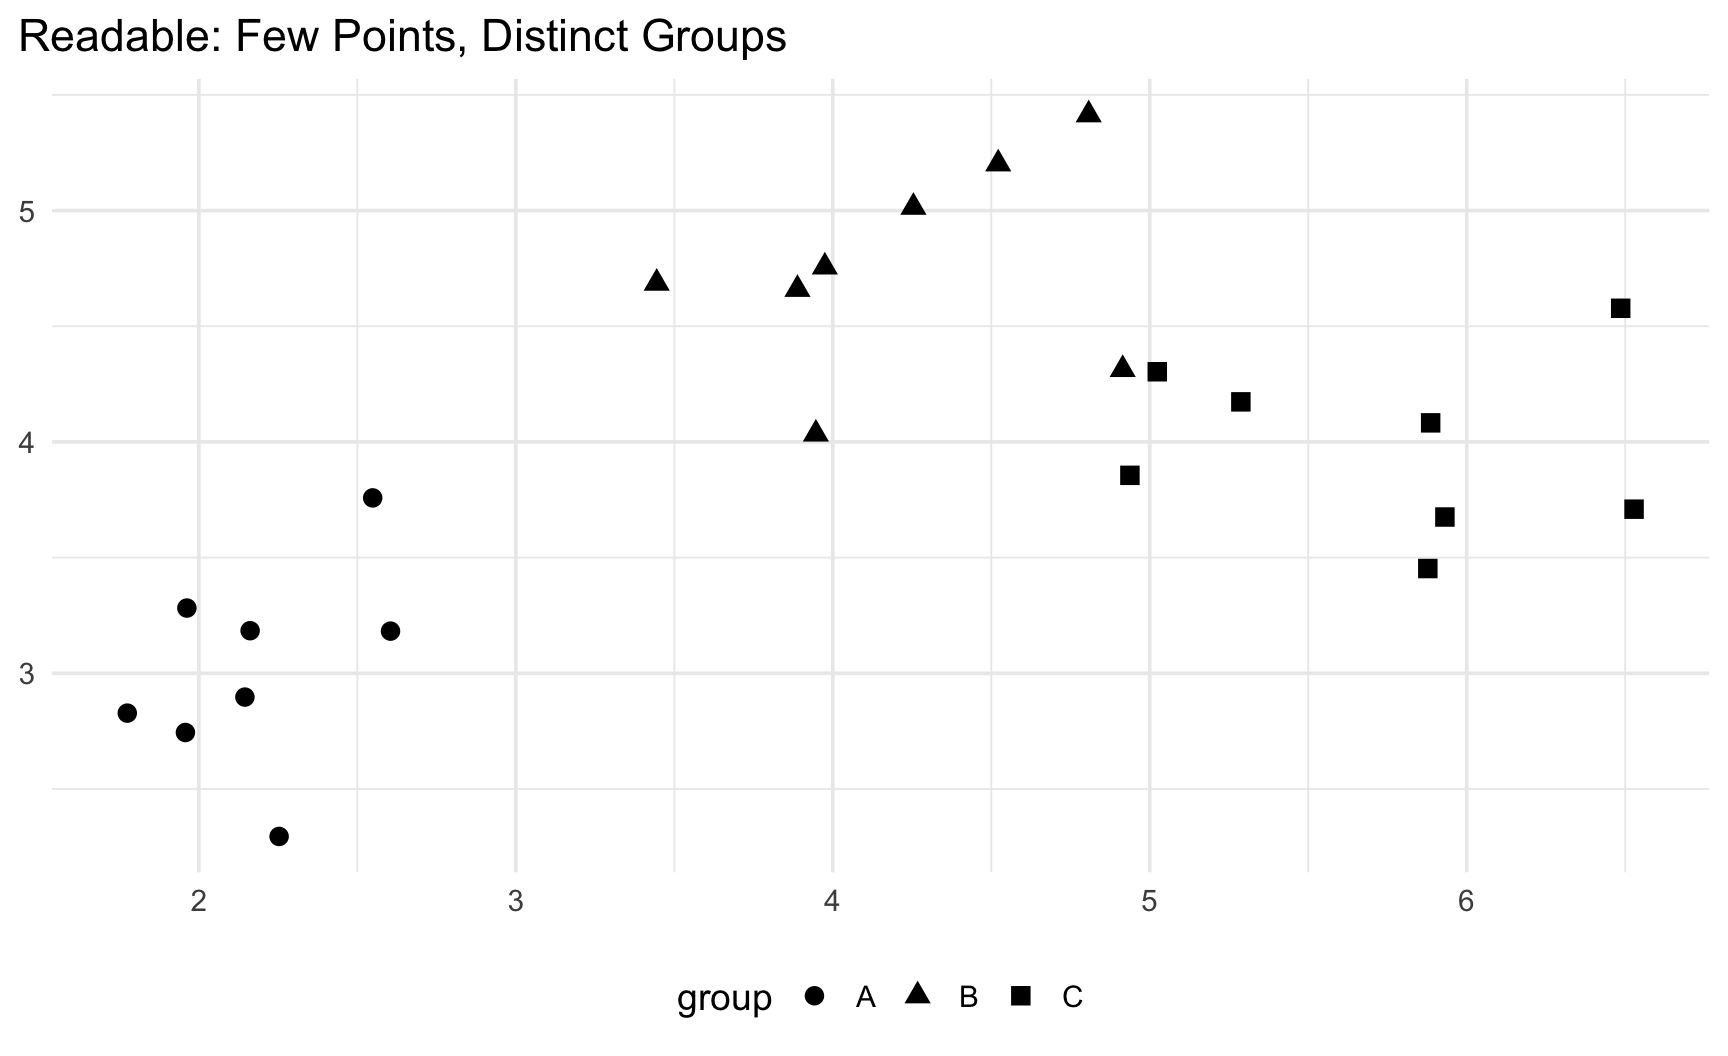
set.seed(42)few_points <-tibble(group =rep(c("A", "B", "C"), each =8),x =rnorm(24, mean =rep(c(2, 4, 6), each =8), sd =0.4),y =rnorm(24, mean =rep(c(3, 5, 4), each =8), sd =0.4))ggplot(data = few_points, mapping =aes(x = x, y = y, shape = group)) +geom_point(size =3) +labs(x =NULL, y =NULL, title ="Readable: Few Points, Distinct Groups" ) +theme_minimal(base_size =14) +theme(legend.position ="bottom", plot.title.position ="plot")
Code
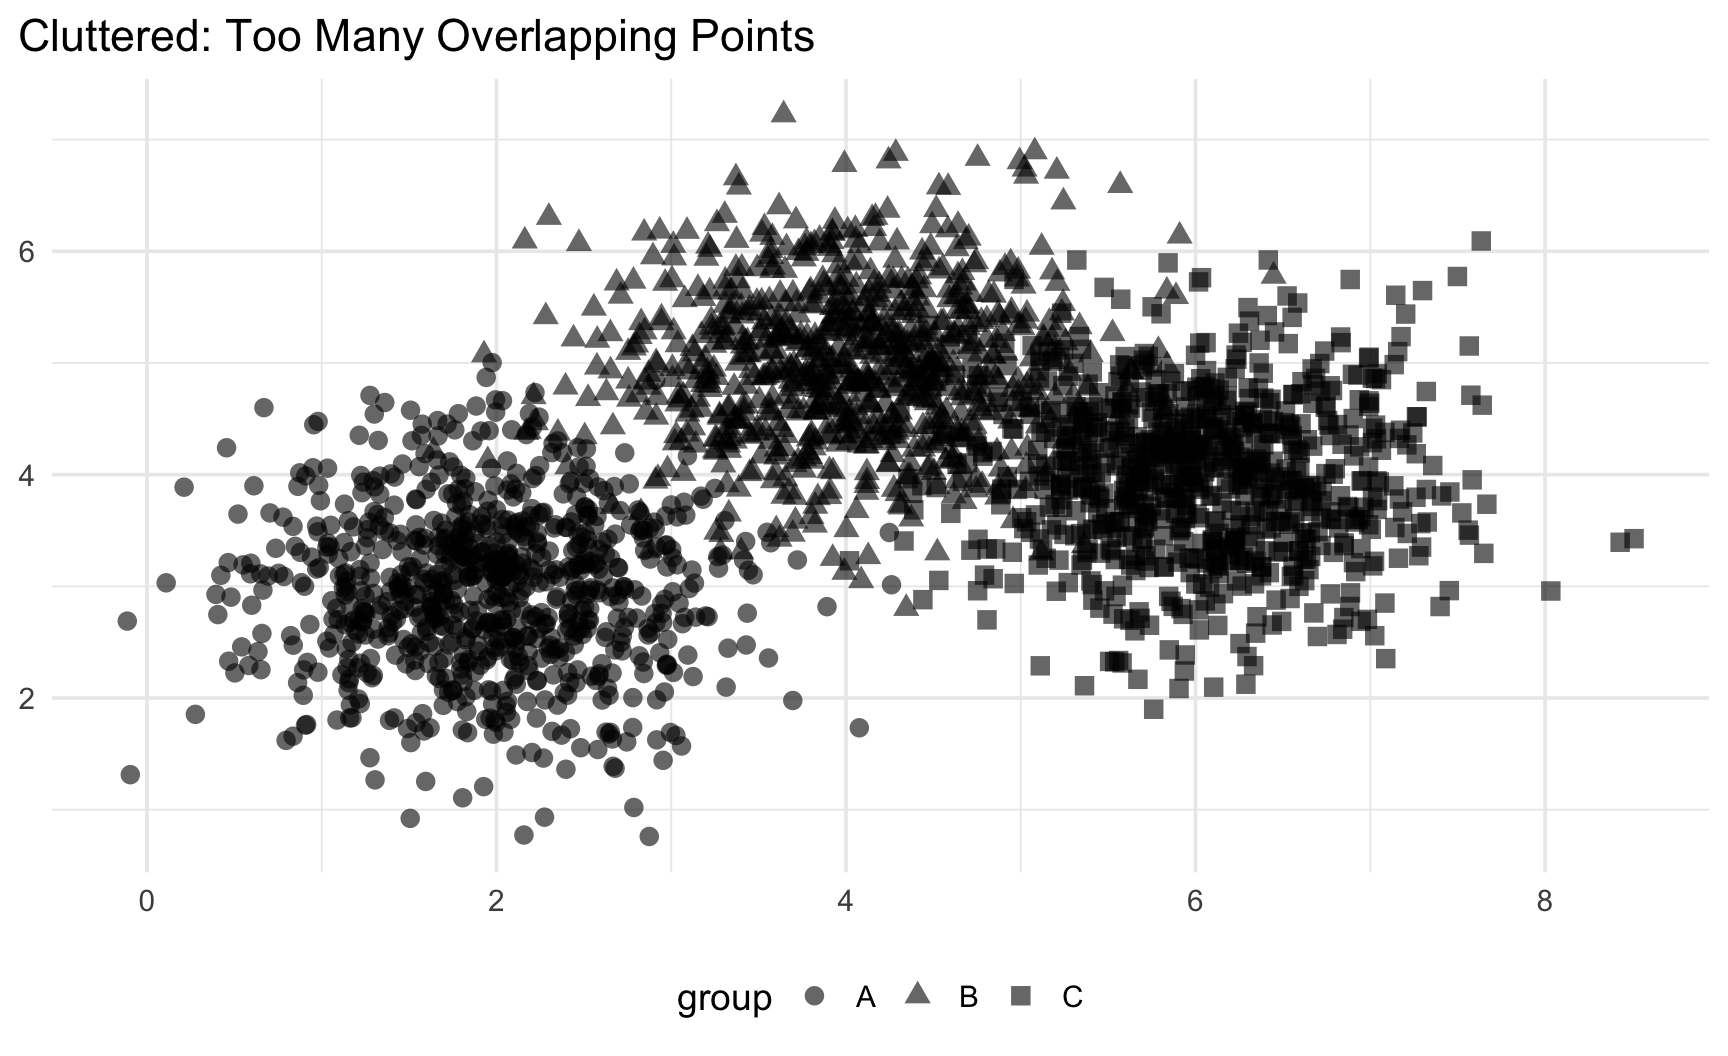
many_points <-tibble(group =rep(c("A", "B", "C"), each =800),x =rnorm(2400, mean =rep(c(2, 4, 6), each =800), sd =0.7),y =rnorm(2400, mean =rep(c(3, 5, 4), each =800), sd =0.7))ggplot(data = many_points, mapping =aes(x = x, y = y, shape = group)) +geom_point(size =3, alpha =0.6) +labs(x =NULL, y =NULL, title ="Cluttered: Too Many Overlapping Points" ) +theme_minimal(base_size =14) +theme(legend.position ="bottom", plot.title.position ="plot")
Code
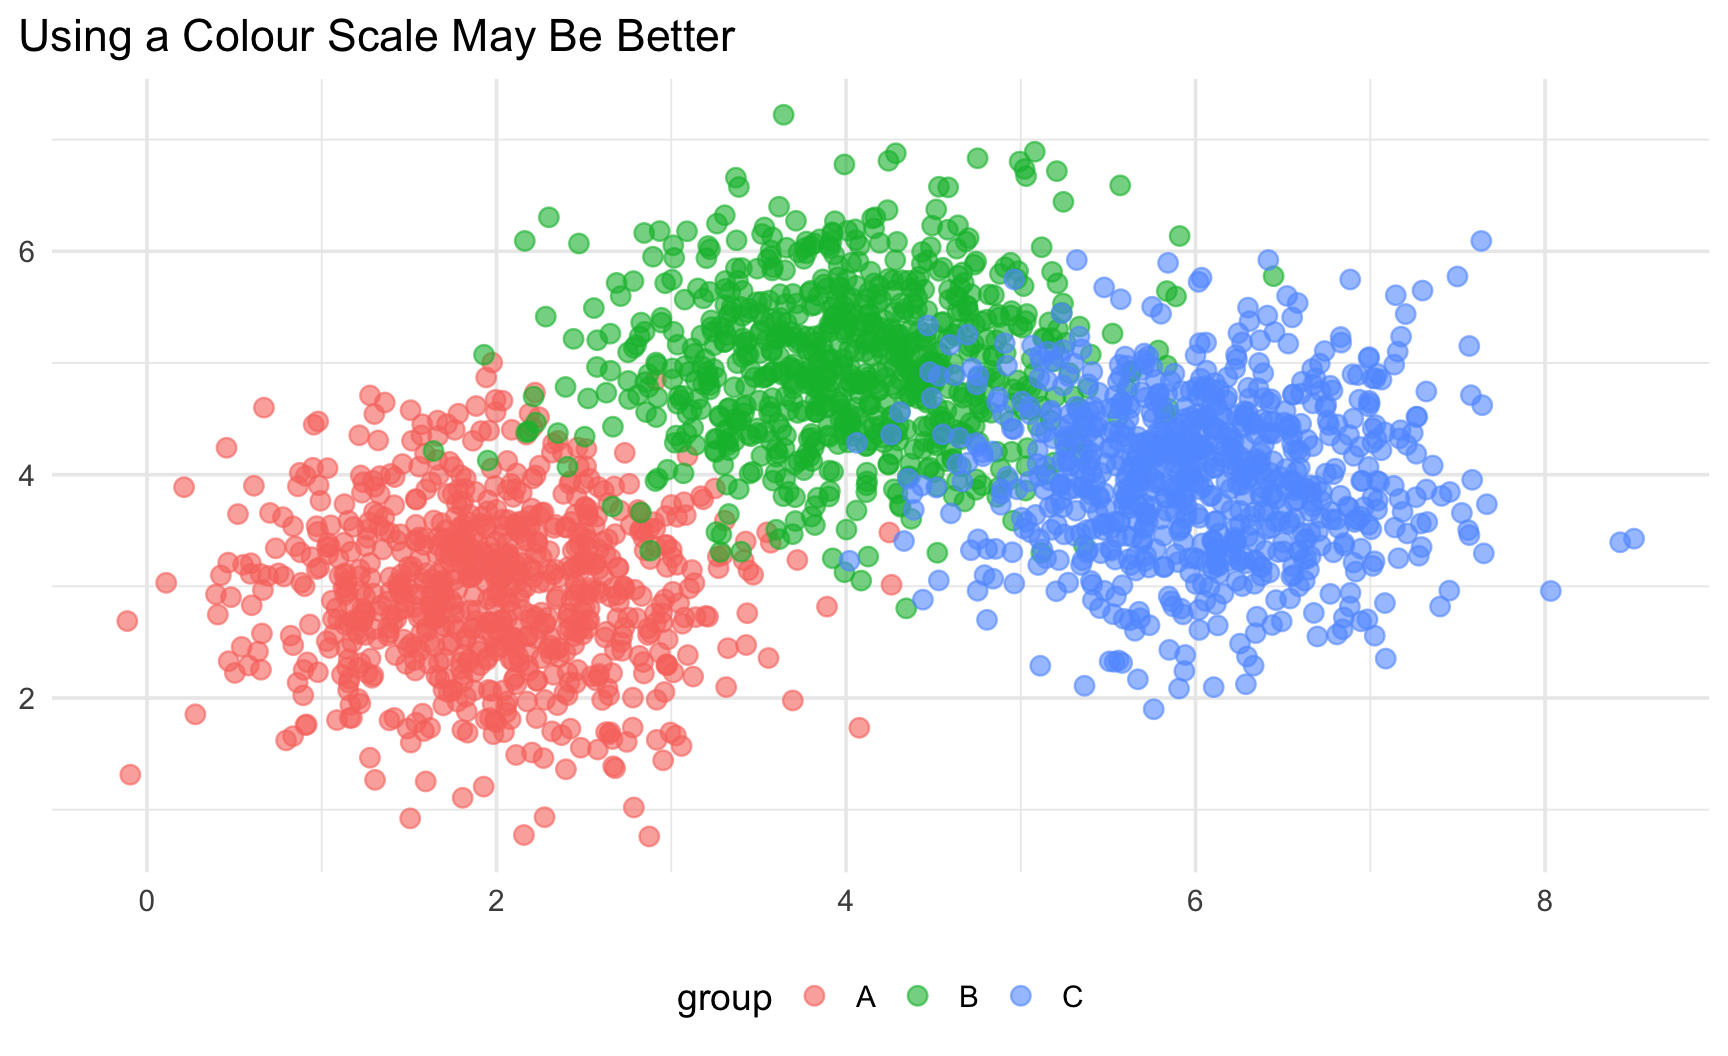
ggplot(data = many_points, mapping =aes(x = x, y = y, colour = group)) +geom_point(size =3, alpha =0.6) +labs(x =NULL, y =NULL, title ="Using a Colour Scale May Be Better" ) +theme_minimal(base_size =14) +theme(legend.position ="bottom", plot.title.position ="plot")
With only a handful of points per group, distinct shapes/markers let the eye separate the three clusters instantly.
Once the sample size grows into the hundreds, overlapping markers blur into a single indistinguishable mass. The shape encoding, which worked perfectly at n=8 per group, becomes nearly useless at n=800.
Perception
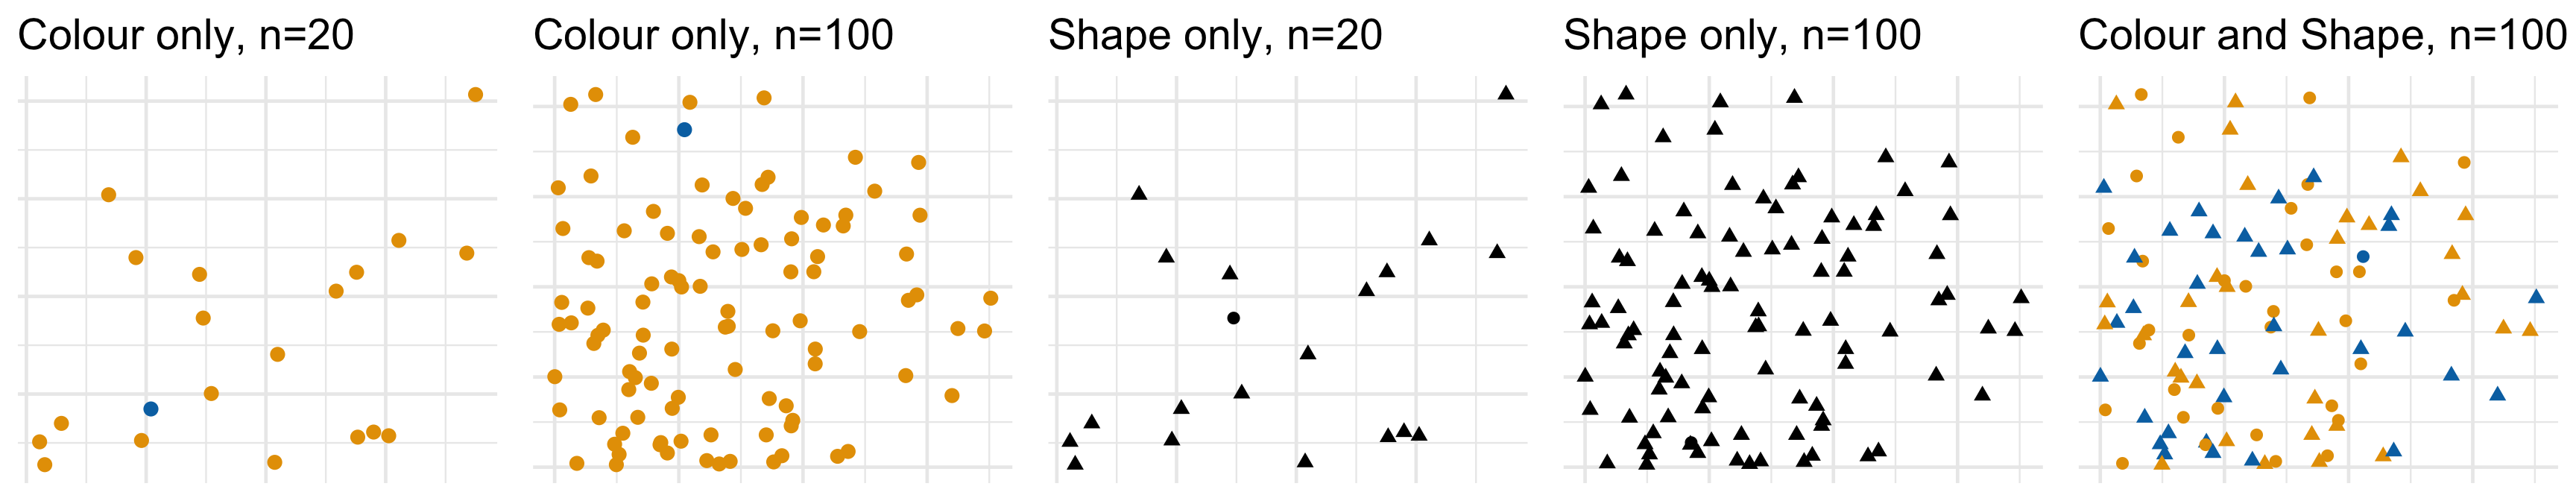
Pre-attentive Visual Processing
Schwabish (2014) argues that an effective graph should tap into the brain’s “pre-attentive visual processing”(Few 2004; Healey and Enns 2012).
This is also called “preattentive pop-out.”
Some objects in our visual field are easier to see than others: they “pop out” at us from whatever surrounds them.
This happens before, or almost before, the conscious act of looking at or for something.
Pre-attentive processing lets the reader perceive multiple basic visual elements simultaneously, rather than one at a time.
By contrast, attentive processing is a conscious part of perception, and it lets us perceive things serially, i.e., one at a time, through deliberate search.
A nuance from the vision science literature
The clean split between “effortless, parallel, pre-attentive” search and “effortful, serial, attentive” search is a simplification. Nakayama and Joseph (1998) argue that attention is required for all visual search, even the “easy” cases.
What differs is the spatial scale (time to reaction) over which attention is deployed: broadly across a whole scene for easy tasks, narrowly on one item at a time for hard tasks.
They also show that “pop-out” (the sudden, involuntary narrowing of attention to an odd item) is a separate phenomenon from what actually makes a search easy, not its cause.
Warning
For the purposes of this course, the practical takeaway is unaffected: some visual encodings (colour, size, orientation) let a reader spot a pattern far faster than others (shape, alphanumeric labels), but the terms “pre-attentive” and “pop-out” are used loosely here as a design heuristic, not as a precise claim about the underlying neuroscience.
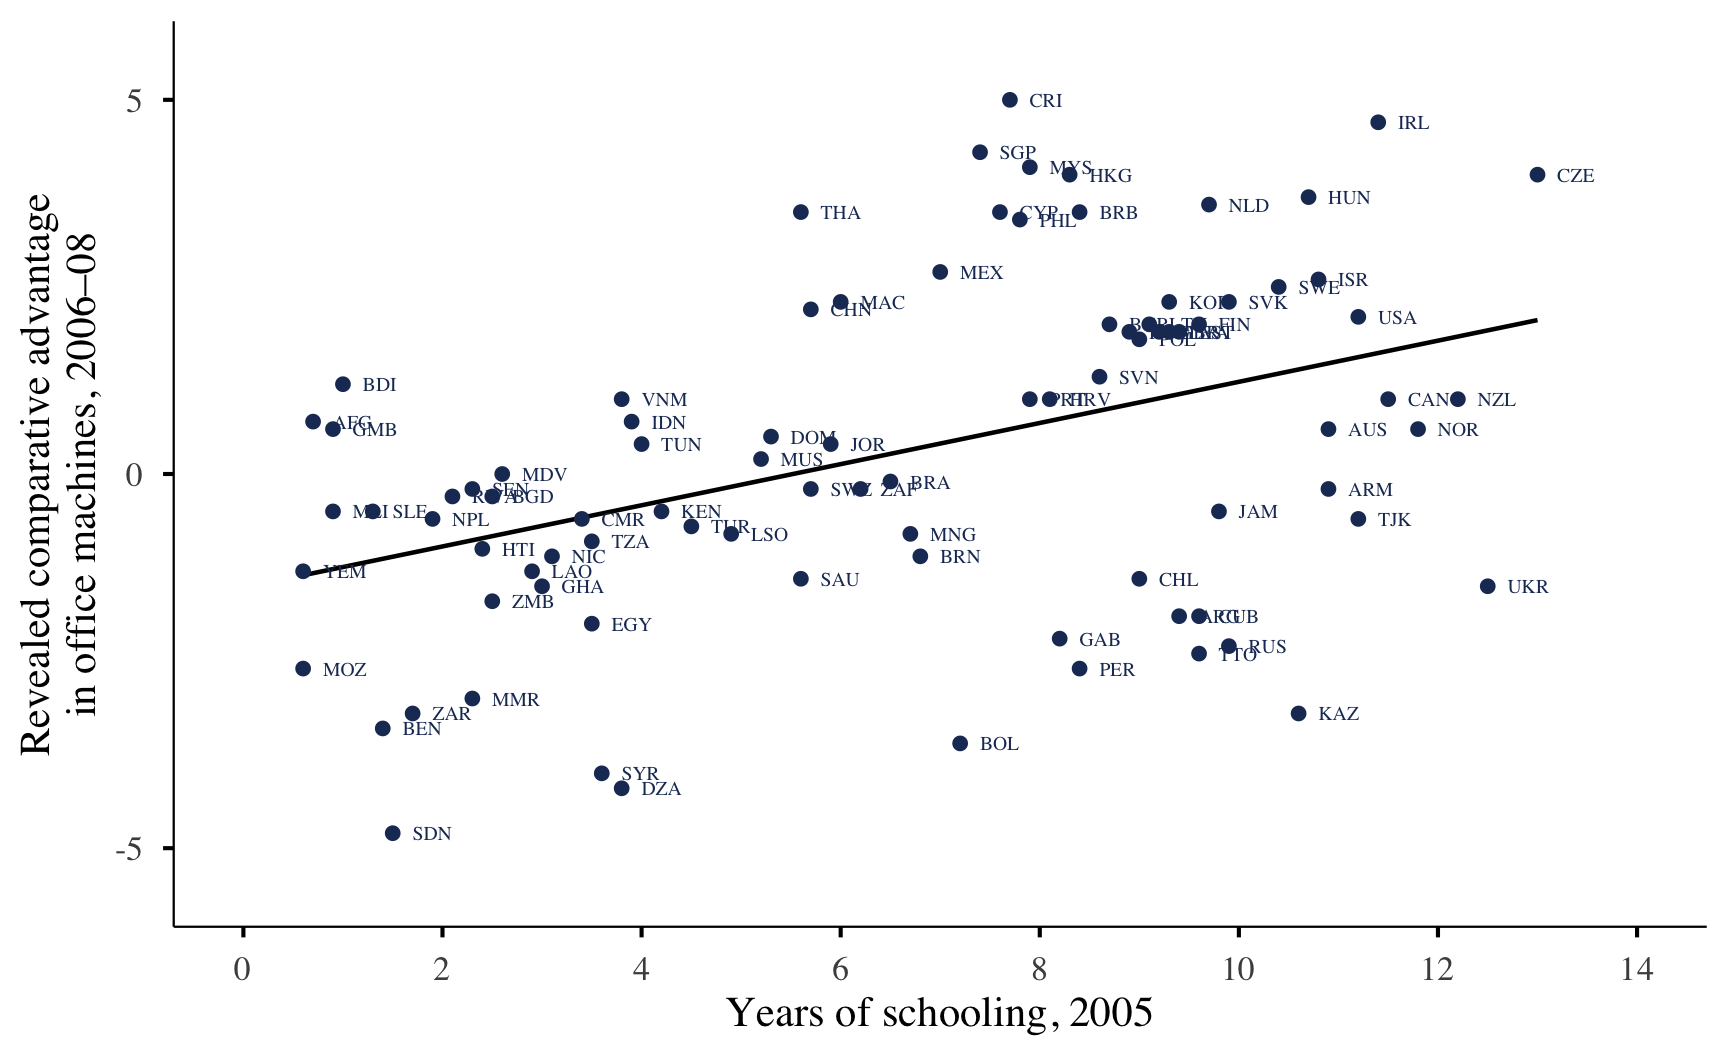
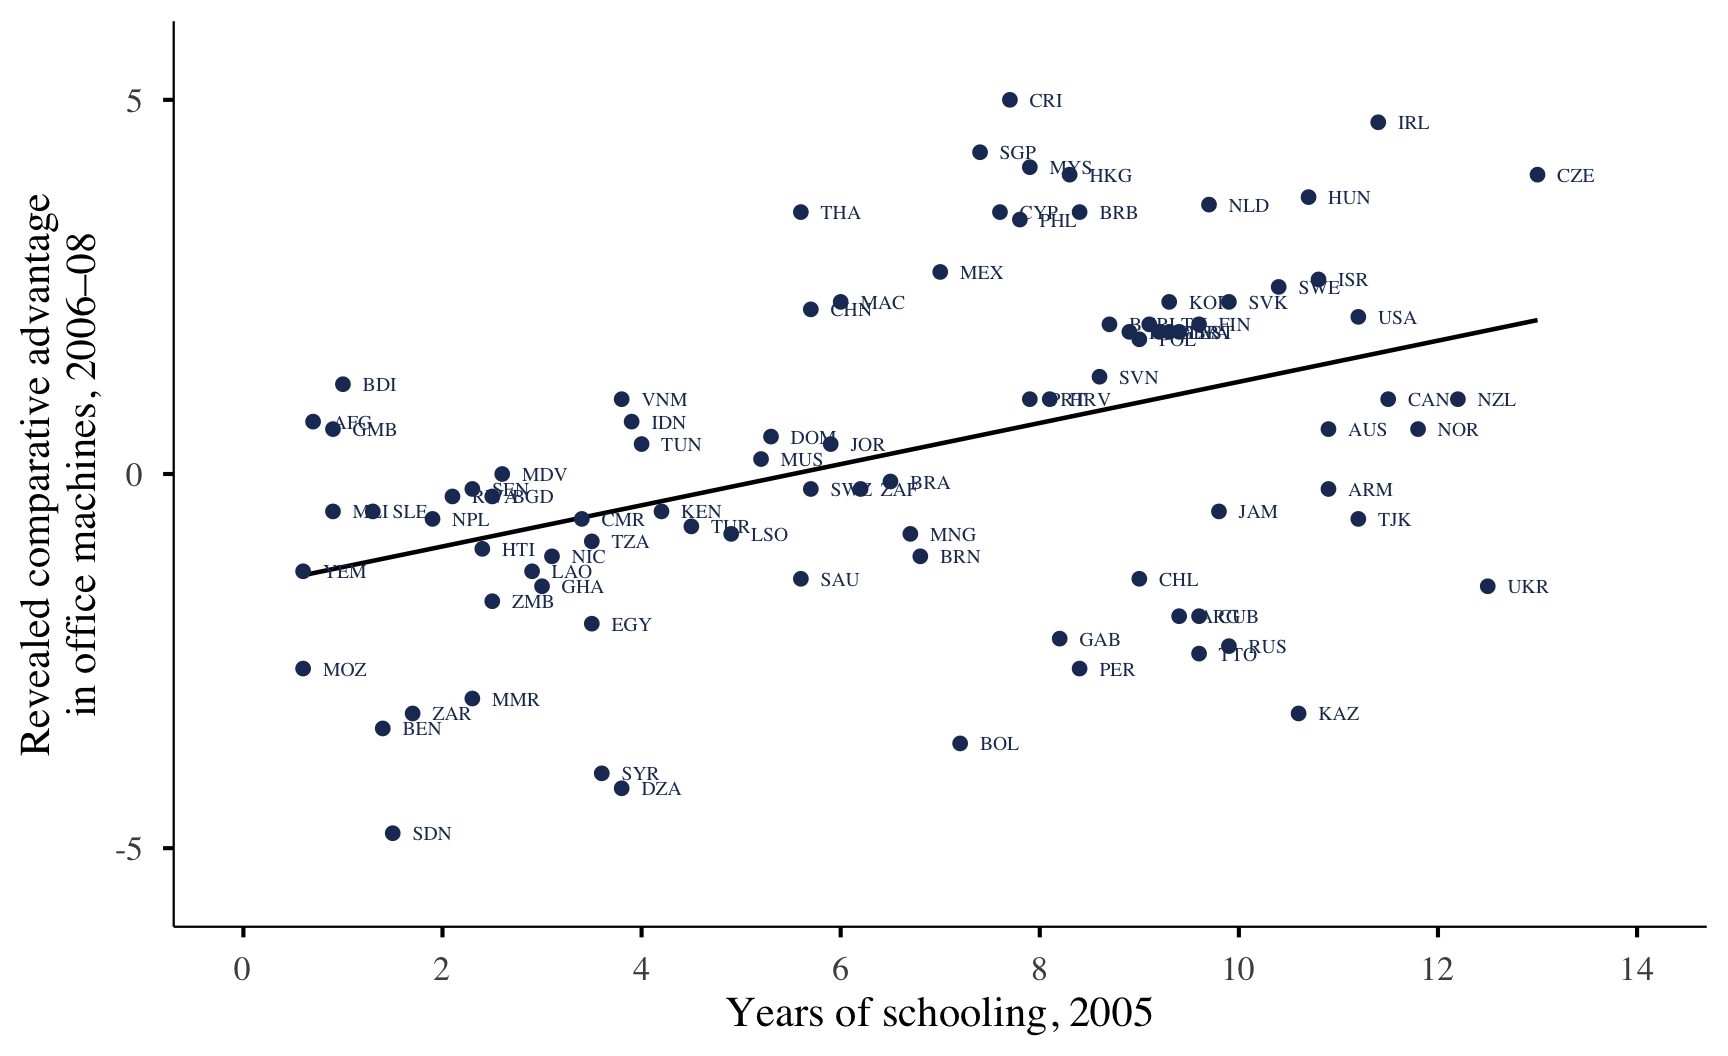
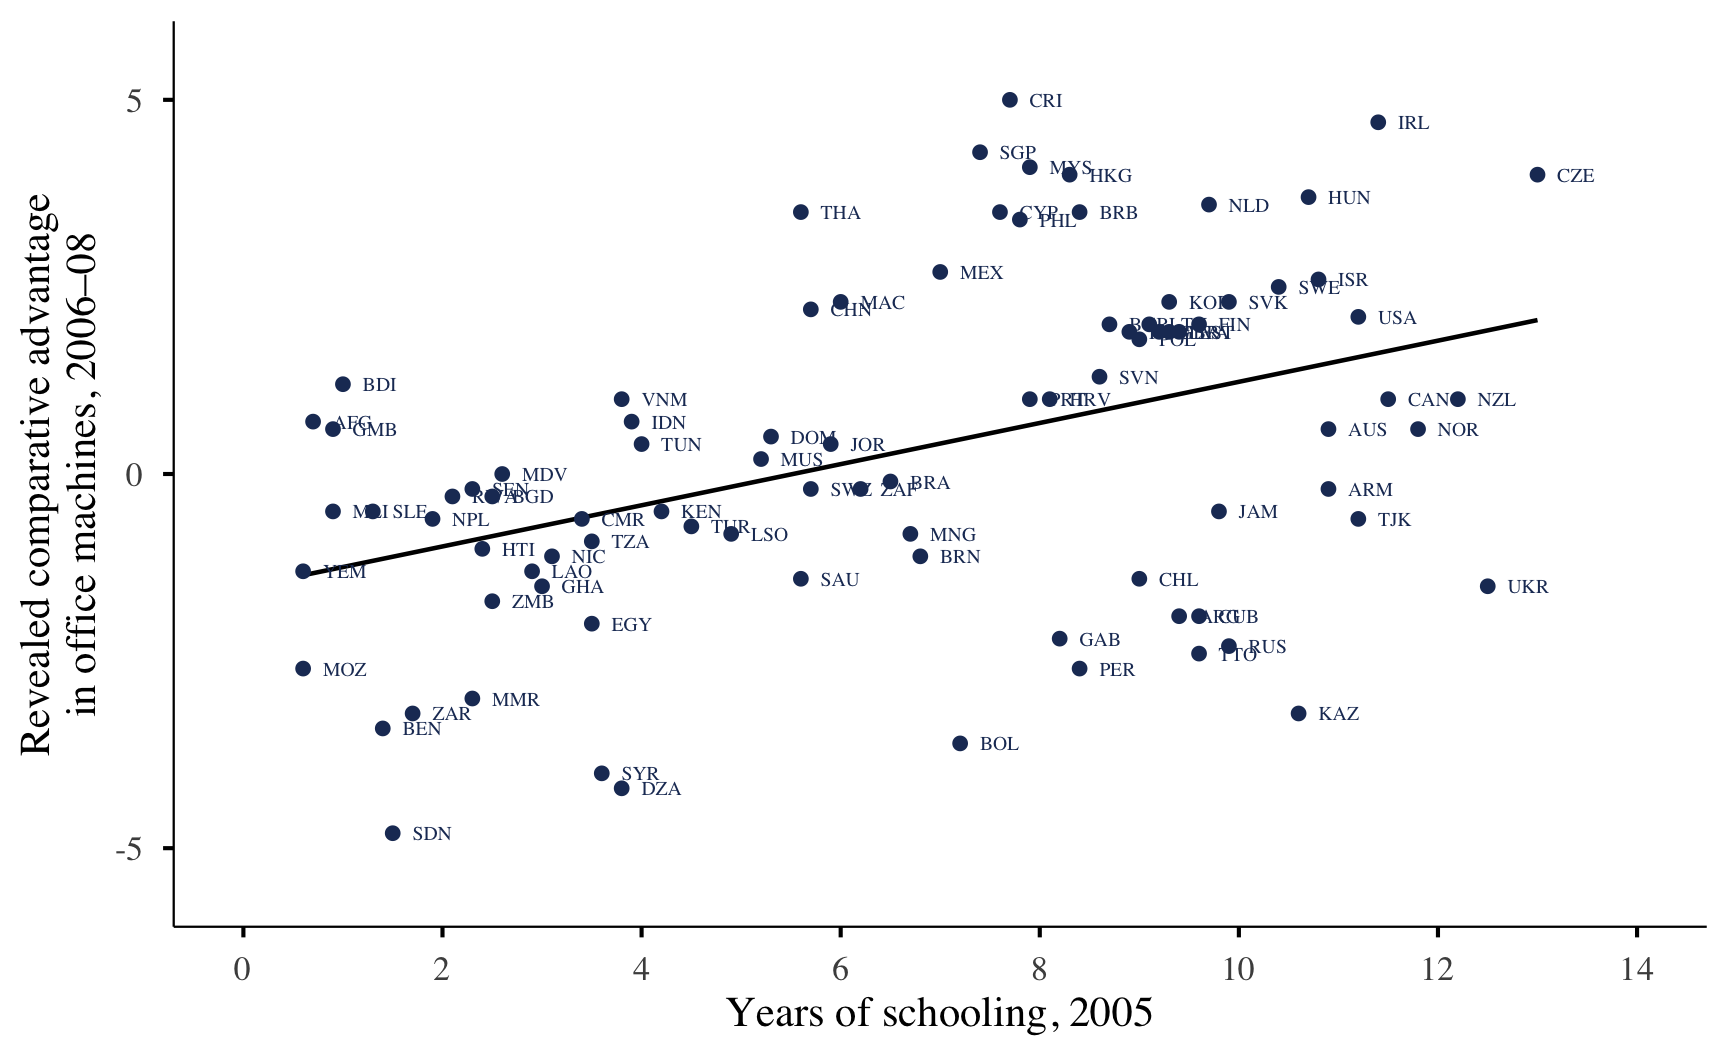
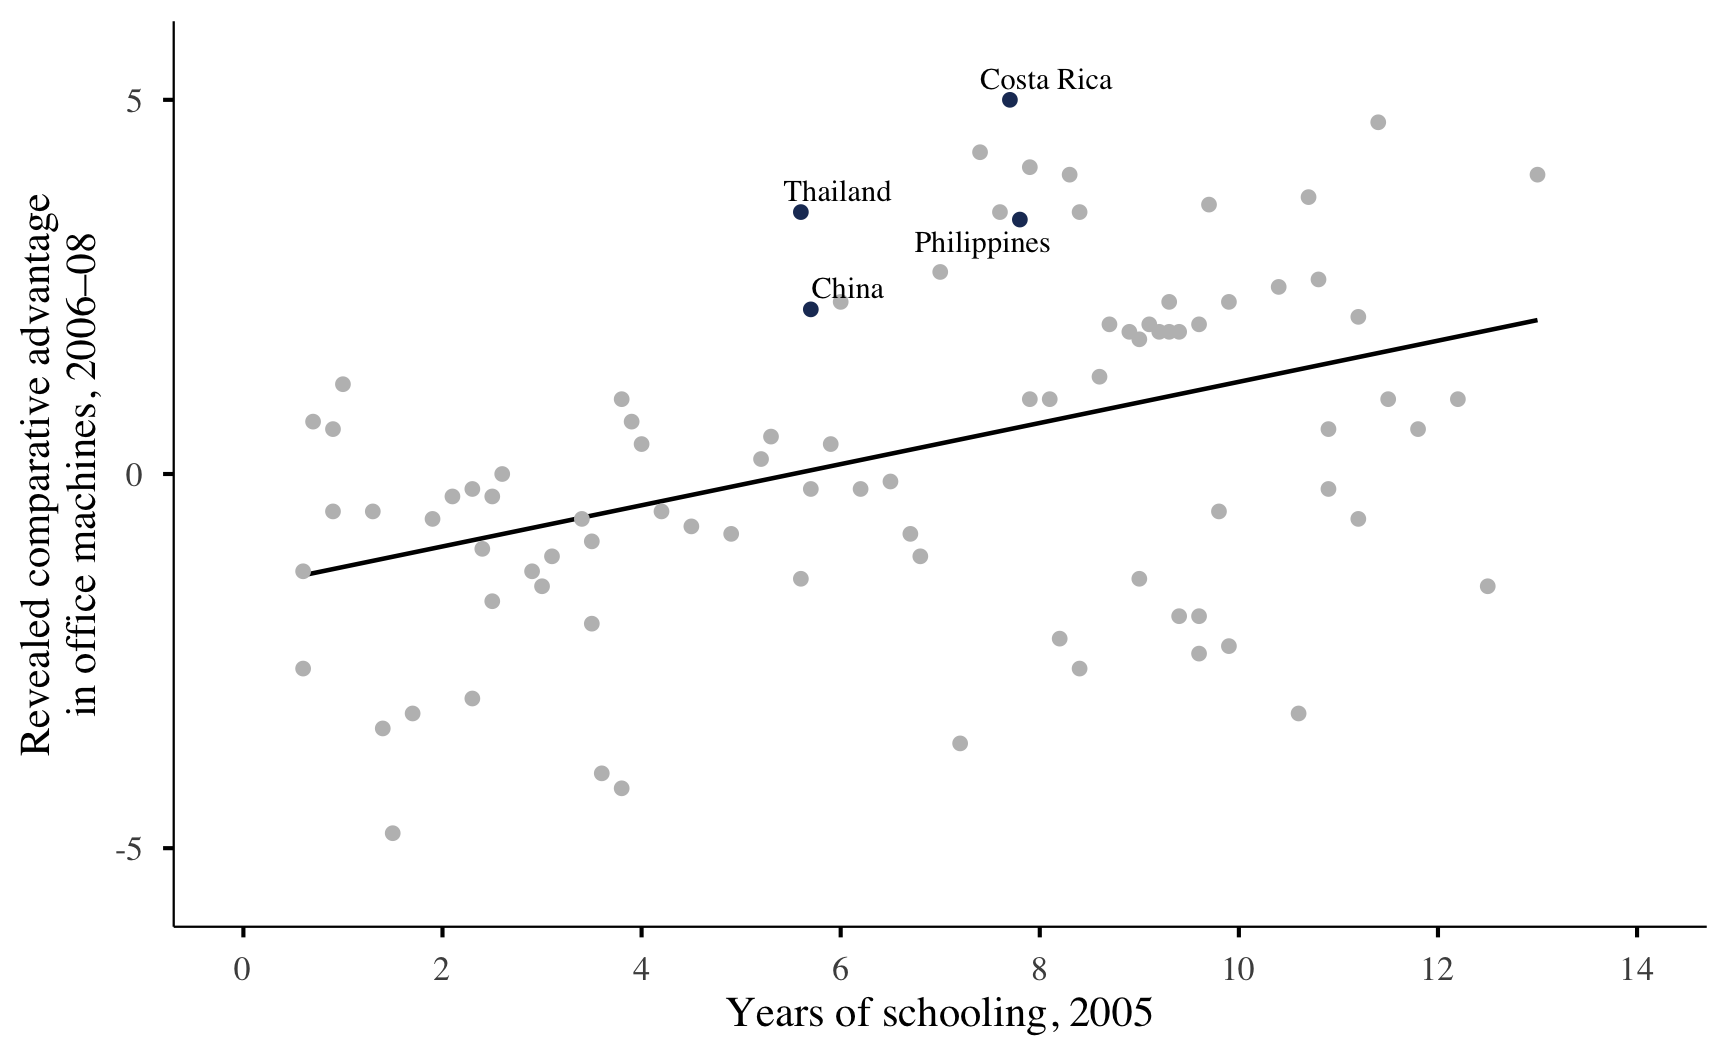
[The Figure] plots countries’ revealed comparative advantage in office machines […] against the average years of schooling of the adult population in 2005 […]. China is above the regression line, indicating that its specialization in the sector is greater than one would expect given its level of education, but it is hardly an extreme outlier. Other middle-income countries–including Costa Rica, the Philippines, Malaysia, and Thailand–have larger positive residuals.
Every country is individually labelled.
Finding the hanful the text actually discusses requires a scanning and discarding dozens of irrelevant labels.
This is a serial, attentive task, not a pre-attentive one!
Sugested Fix: Show Only What Matters!
Schwabish (2014) suggests highlighting only the observations that support the point being made.
For transparency, you can still publish the full dataset online, or include a table with all observations in an appendix.
Hiding labels from a chart is not the same as hiding the data.
Gestalt Principles
The Gestalt Idea
Gestalt [german meaning “form”] psychology, developed in the early 20th century, studies how the human visual system spontaneously groups individual elements into a unified whole, often before any conscious effort (Koffka 1935).
The idea, in a nutshell: “the whole is different from the sum of its parts.”
Applied to data visualization: the same data, encoded slightly differently, can make a reader perceive entirely different groupings
some of those groups may not actually be present in the data,
whereas others may be hiding hiding a grouping that is there.
Gestalt Principles
The Gestalt psychologists identified several distinct rules that govern how the grouping happens: cues as simple as distance, colour, or a connecting line.
Each one gives chart designers a lever:
used well, it clarifies structure;
used carelessly, it can mislead just as easily as a truncated axis or a misleading scale.
Principle of Proximity
Elements that are close together are perceived as belonging to the same group, even with no other visual cue.
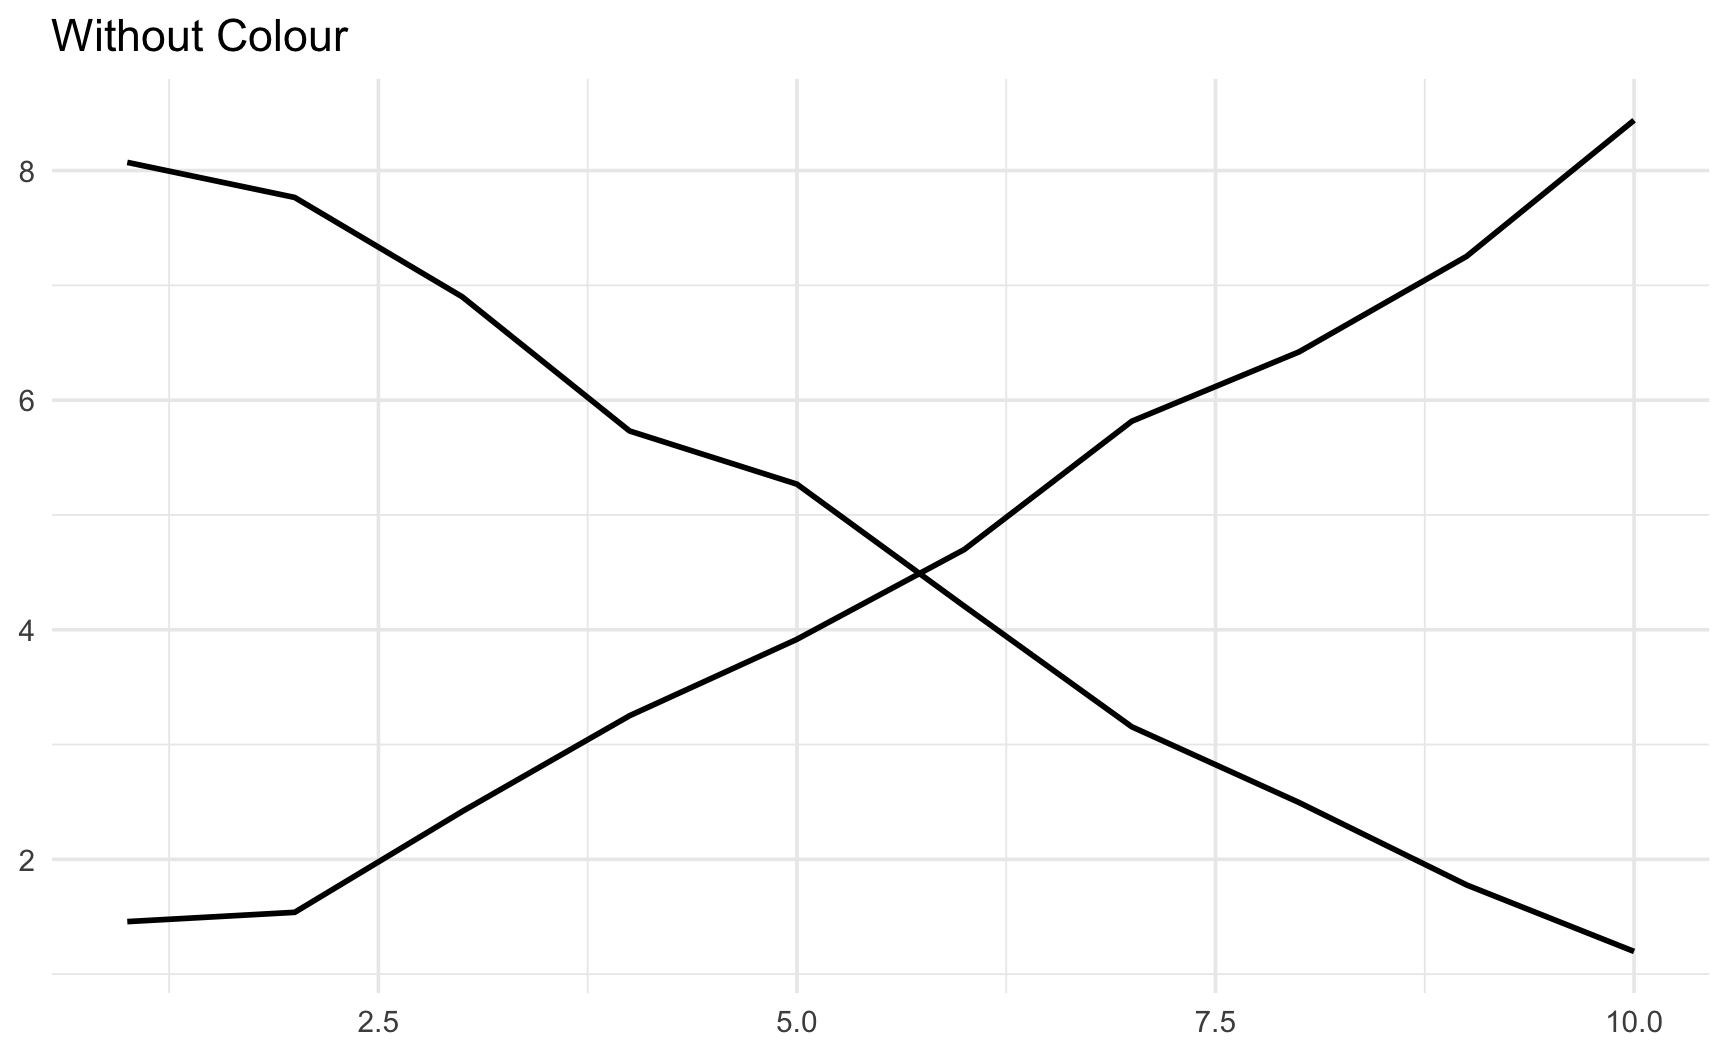
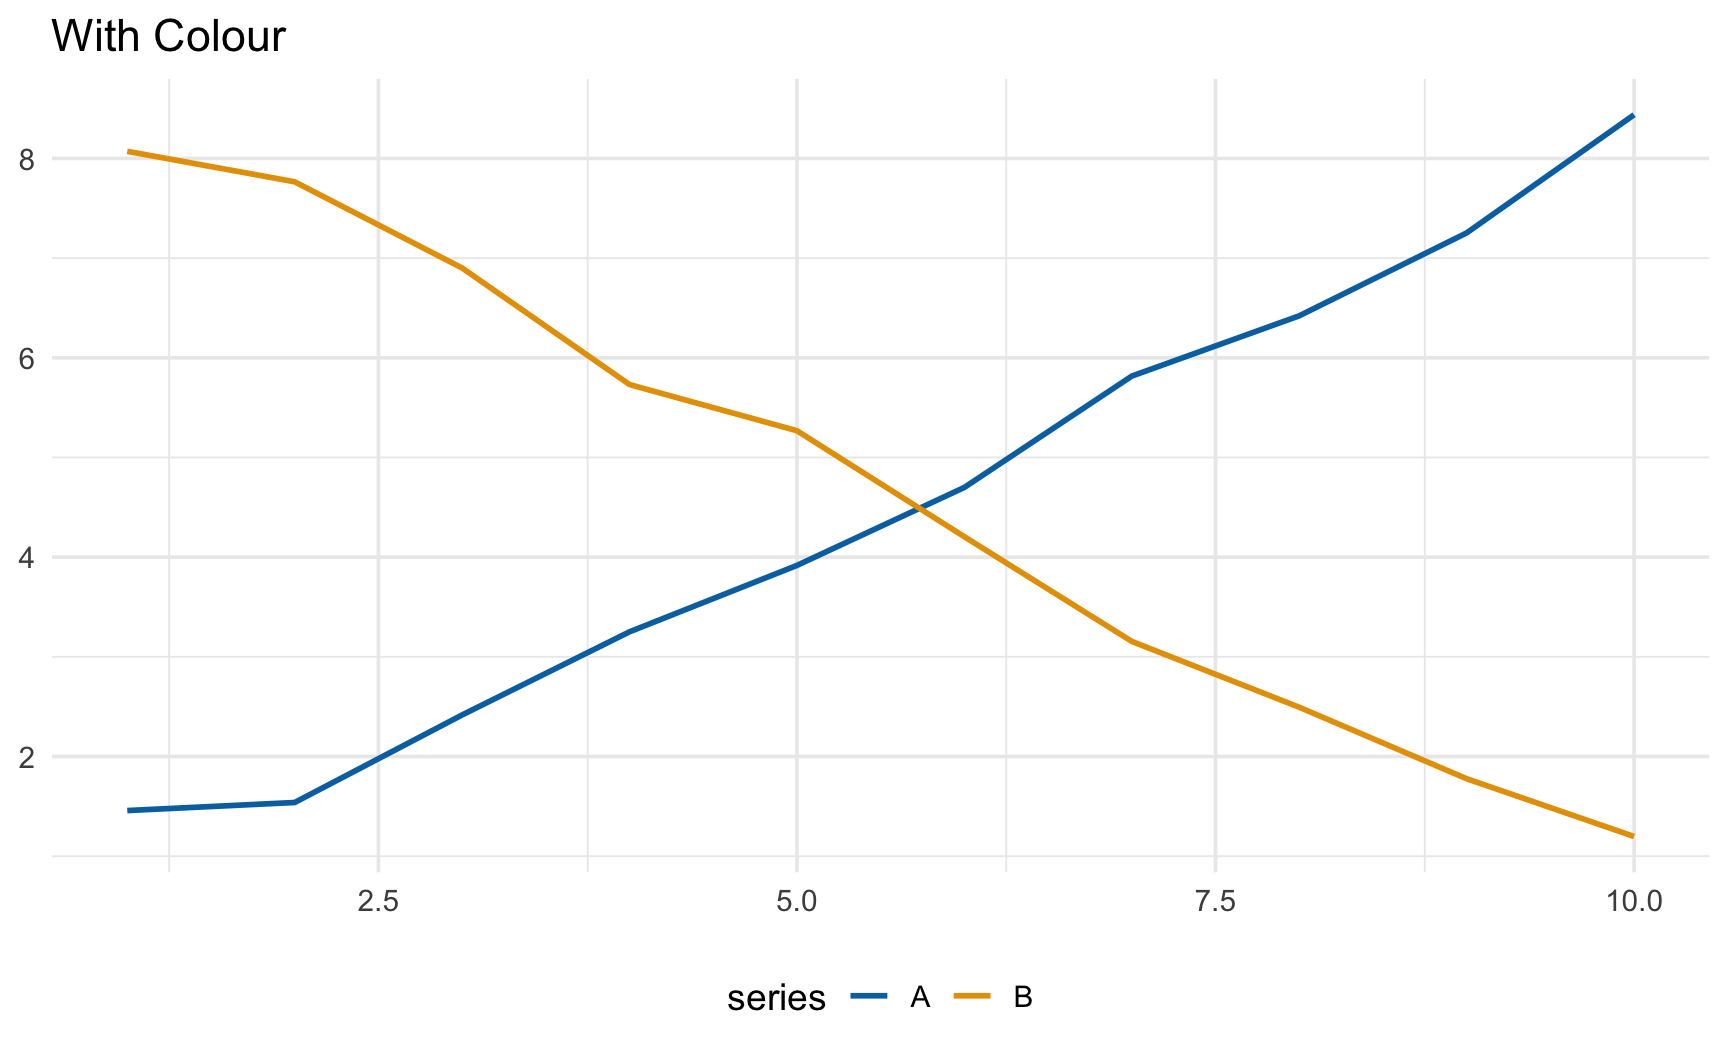
This supports the fact that lines are a good choice for time series: a connecting line does more grouping work than colour alone. Removing the lines would make the series far harder to trace individually.
The eye prefers to perceive smooth, continuous paths rather than abrupt changes in direction.
Code
set.seed(7)cross_data <-tibble(x =rep(1:10, 2),series =rep(c("A", "B"), each =10),y =c(seq(1, 8, length.out =10) +rnorm(10, 0, 0.2), # rising lineseq(8, 1, length.out =10) +rnorm(10, 0, 0.2) # falling line ))ggplot(data = cross_data, mapping =aes(x = x, y = y, group = series)) +geom_line(colour ="black", linewidth =1) +theme_minimal(base_size =14) +labs(x =NULL, y =NULL, title ="Without Colour")
Code
ggplot(data = cross_data, mapping =aes(x = x, y = y, colour = series)) +geom_line(linewidth =1) +scale_colour_manual(values =c("A"="#0072B2", "B"="#E69F00")) +theme_minimal(base_size =14) +theme(legend.position ="bottom") +labs(x =NULL, y =NULL, title ="With Colour")
Both lines are the same colour.
At the crossing point, the eye tends to follow the path that continues most smoothly.
By doing so, we may be silently switching from series A to series B without noticing.
Colour breaks this ambiguity: continuity now has to compete with a much stronger cue (similarity of colour) so the eye reliably stays on the correct series.
Principle of Continuity in Bar Charts: Ordering Matters
Code
library(tidyverse)set.seed(11)bar_data <-tibble(category = LETTERS[1:10],value =round(runif(10, 20, 100)))ggplot(data = bar_data,mapping =aes(x = category, y = value)) +geom_col(fill ="#0072B2") +theme_minimal(base_size =14) +labs(x =NULL, y =NULL, title ="Unordered")
Code
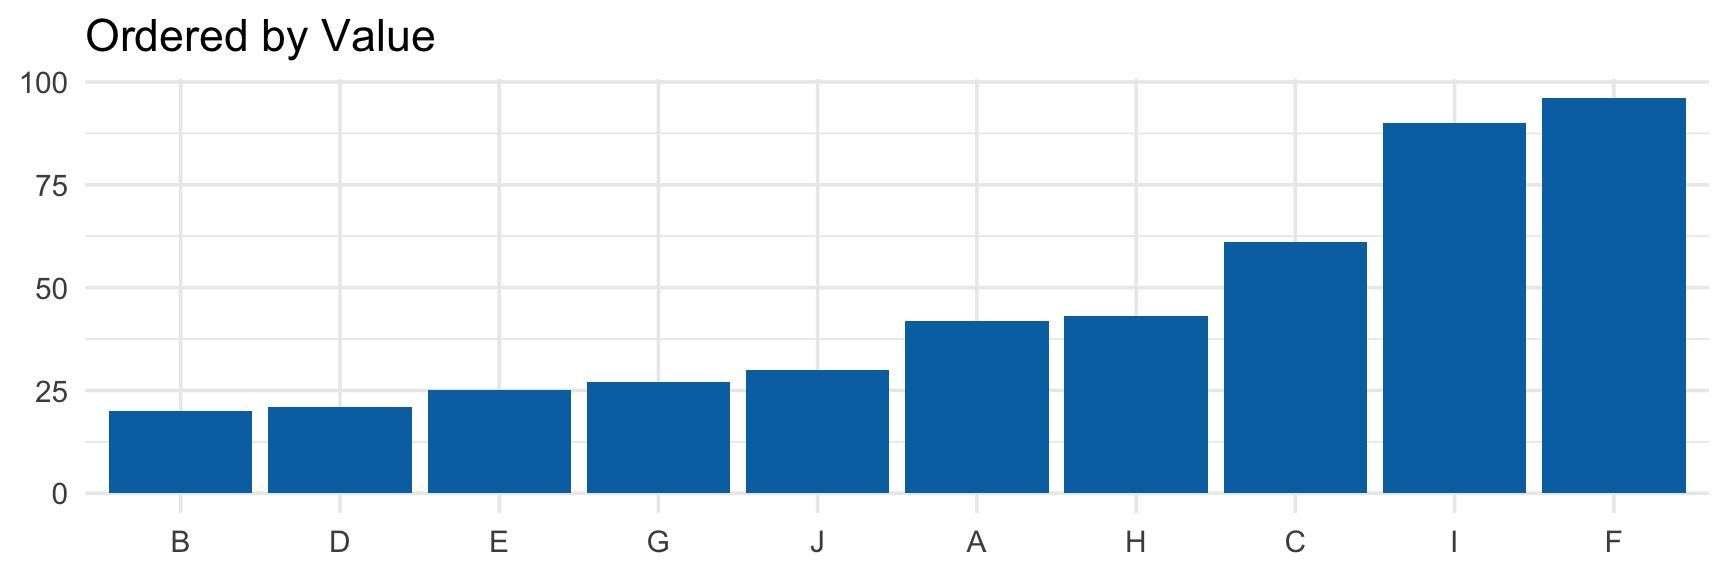
ggplot(data = bar_data,mapping =aes(x =reorder(category, value), y = value)) +geom_col(fill ="#0072B2") +theme_minimal(base_size =14) +labs(x =NULL, y =NULL, title ="Ordered by Value")
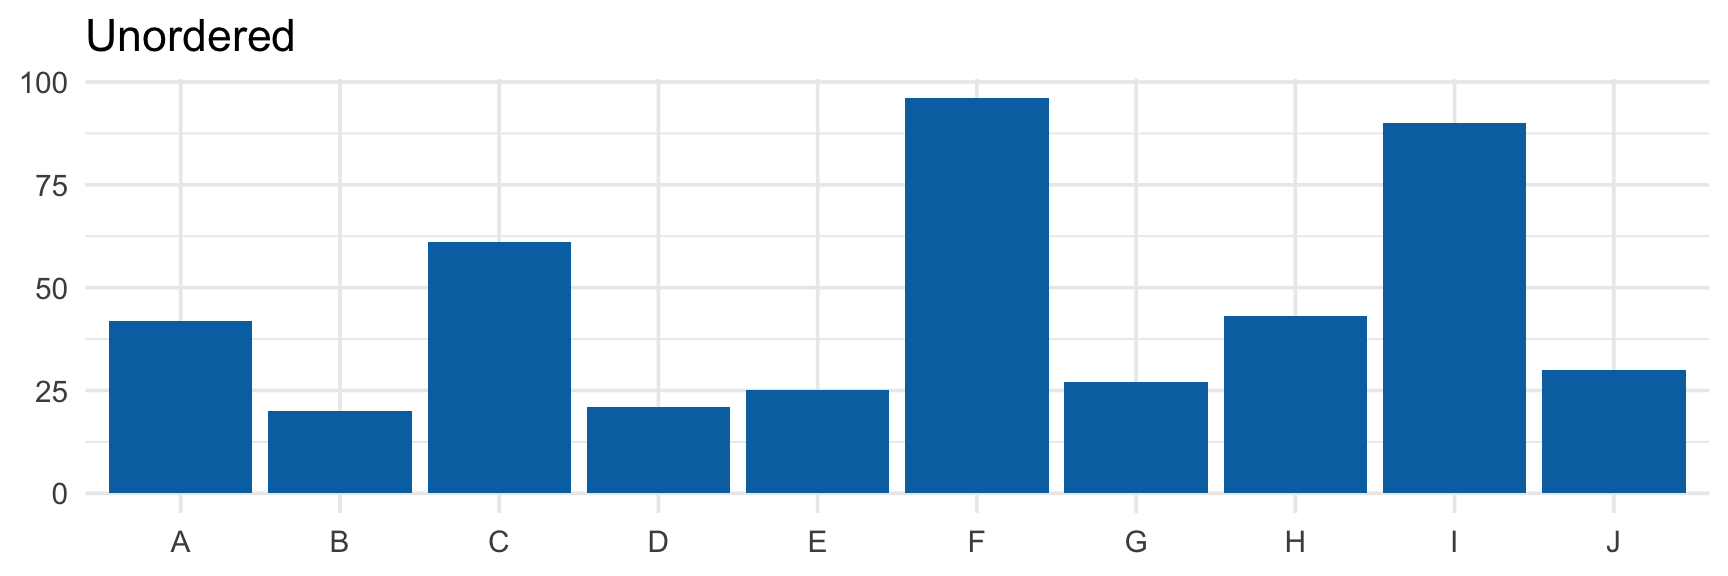
With bars left in an alphabetical, or the order they appeared in the raw data, the eye usually has no smooth path to follow. Hence, each bar-to-bar comparison requires a deliberate look.
Once sorted by value, the bar heights form a single smooth contour that can be followed by the eye. This allows the reader to pick out the highest and lowest categories, and perceive the overall shape of the distribution as one continuous trend rather than ten separate comparisons.
Principle of Closure
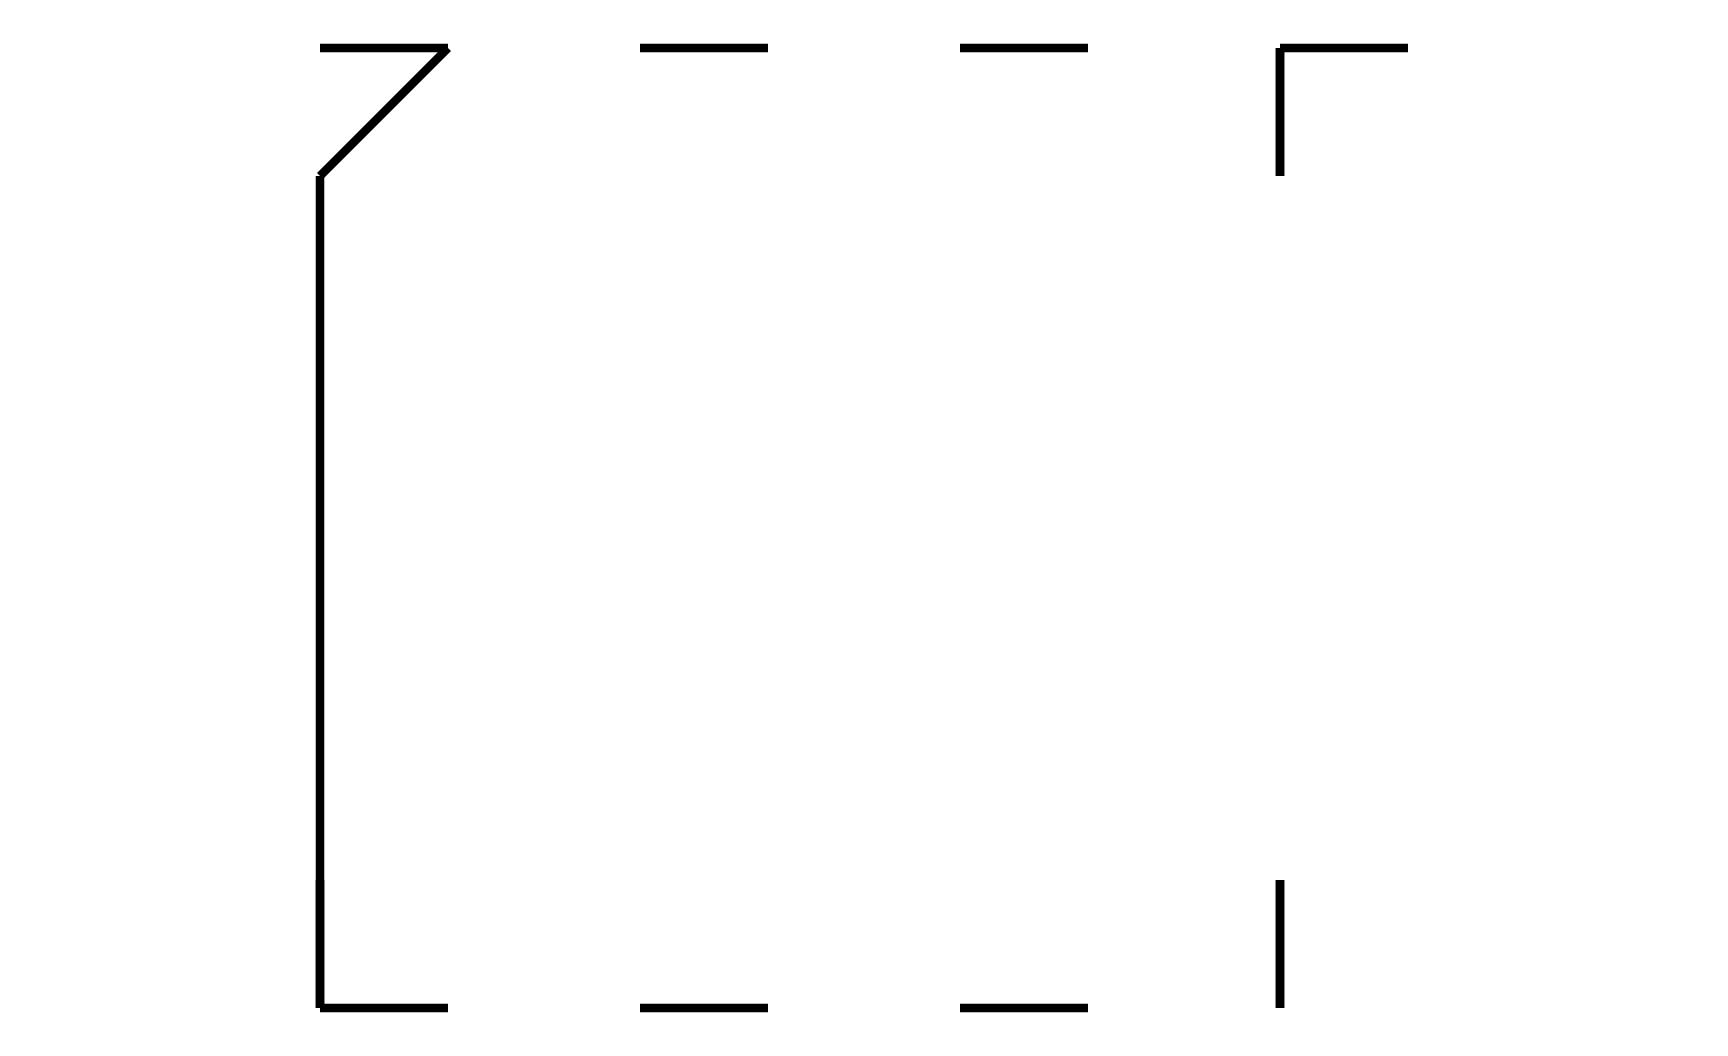
The visual system tends to complete incomplete shapes, mentally filling in gaps to perceive a whole object.
Code
library(grid)ggplot() +annotate("segment", x =c(0,1,2,3,0,3,0,1,2,3), y =c(0,0,0,0,0,3,3,3,3,3), xend =c(0.4,1.4,2.4,3,0,3,0.4,1.4,2.4,3.4), yend =c(0,0,0,0.4,2.6,2.6,3,3,3,3), linewidth =1.5 ) +annotate("segment", x =c(0,0,3,3), y =c(0,2.6,0,2.6),xend =c(0,0.4,3,3), yend =c(0.4,3,0.4,3), linewidth =1.5 ) +coord_fixed() +theme_void()
Even with the corners of the square left open, the eye perceives a complete rectangle.
In chart design, this means partial gridlines, dashed reference lines, or subtle borders can still convey a strong sense of enclosure without needing solid, heavy strokes.
This is useful for reducing clutter (recall Rule 3!) while preserving structure.
Principle of Figure-Ground
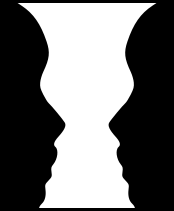
The eye separates a scene into a figure (the object of attention) and a ground (the background)
A classic illustration is Rubin’s vase: the same image can be perceived as two faces in profile, or as a vase, depending on which region the eye assigns as “figure” versus “ground.”
This helps readers distinguish the primary data (the figure) from the contextual background or axes (the ground).
Figure-Ground on a Map
Code
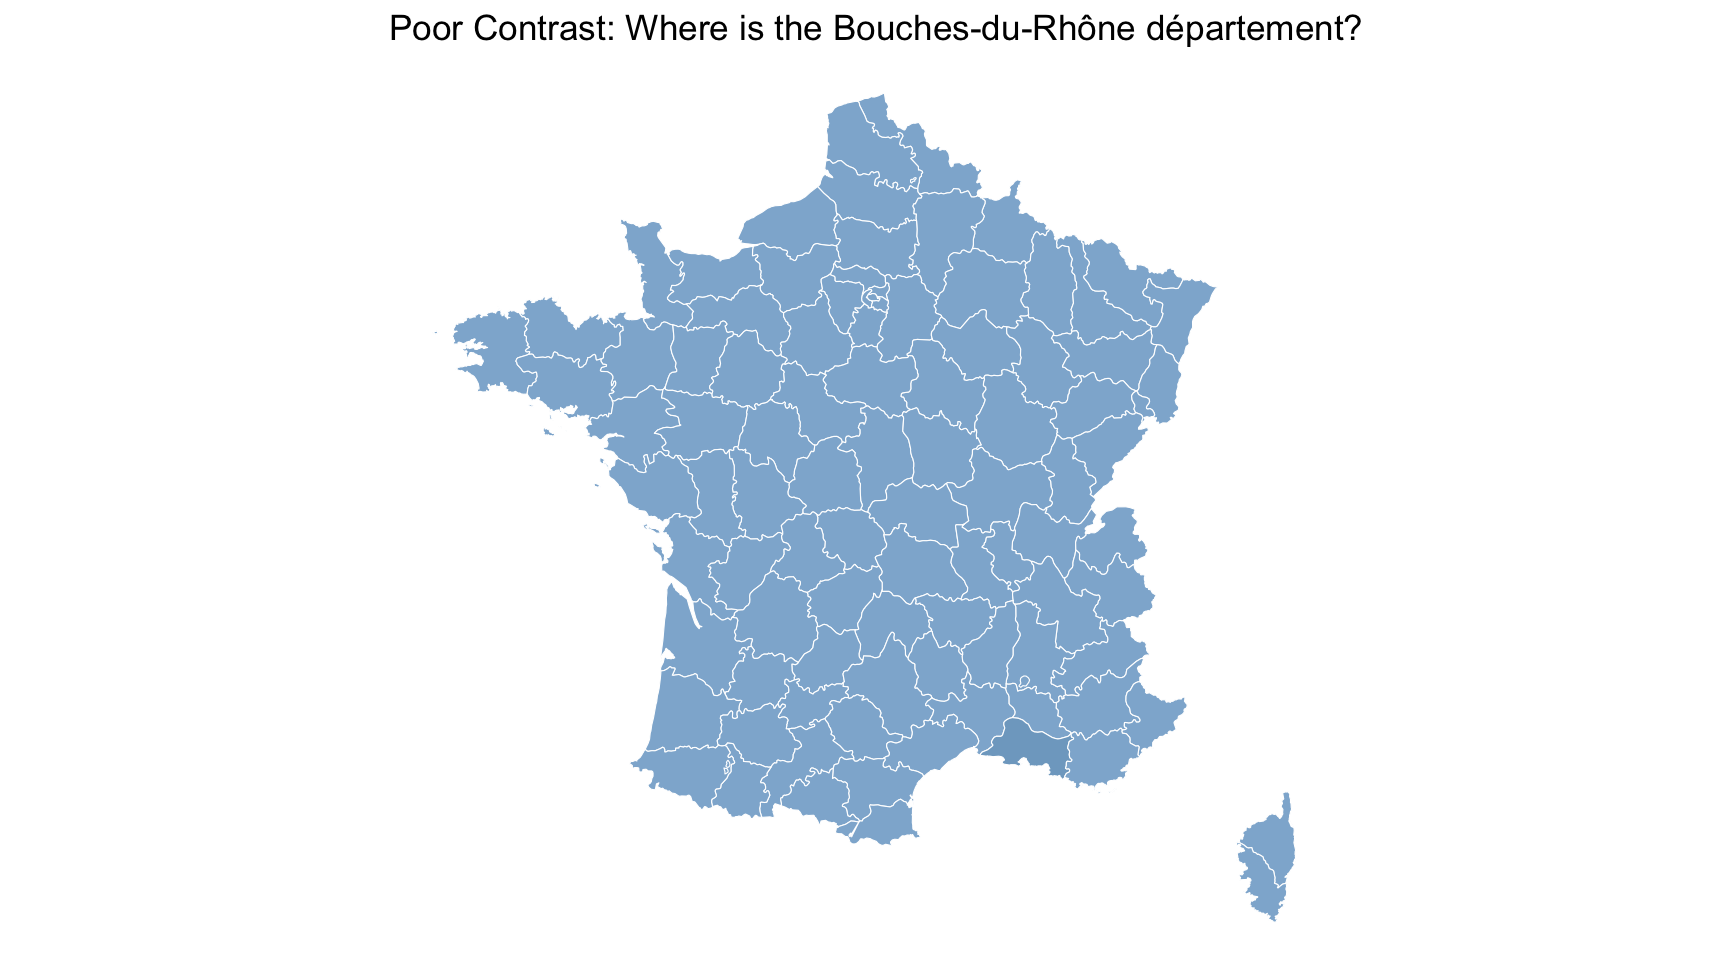
library(tidyverse)library(maps)france_data <-map_data("france")ggplot(data = france_data,mapping =aes(x = long, y = lat, group = group, fill = region =="Bouches-du-Rhone" )) +geom_polygon(colour ="white", linewidth =0.2) +scale_fill_manual(values =c("TRUE"="#7FA8C9", "FALSE"="#8FB4D4"), guide ="none") +coord_map() +theme_void() +labs(title ="Poor Contrast: Where is the Bouches-du-Rhône département?")
Code
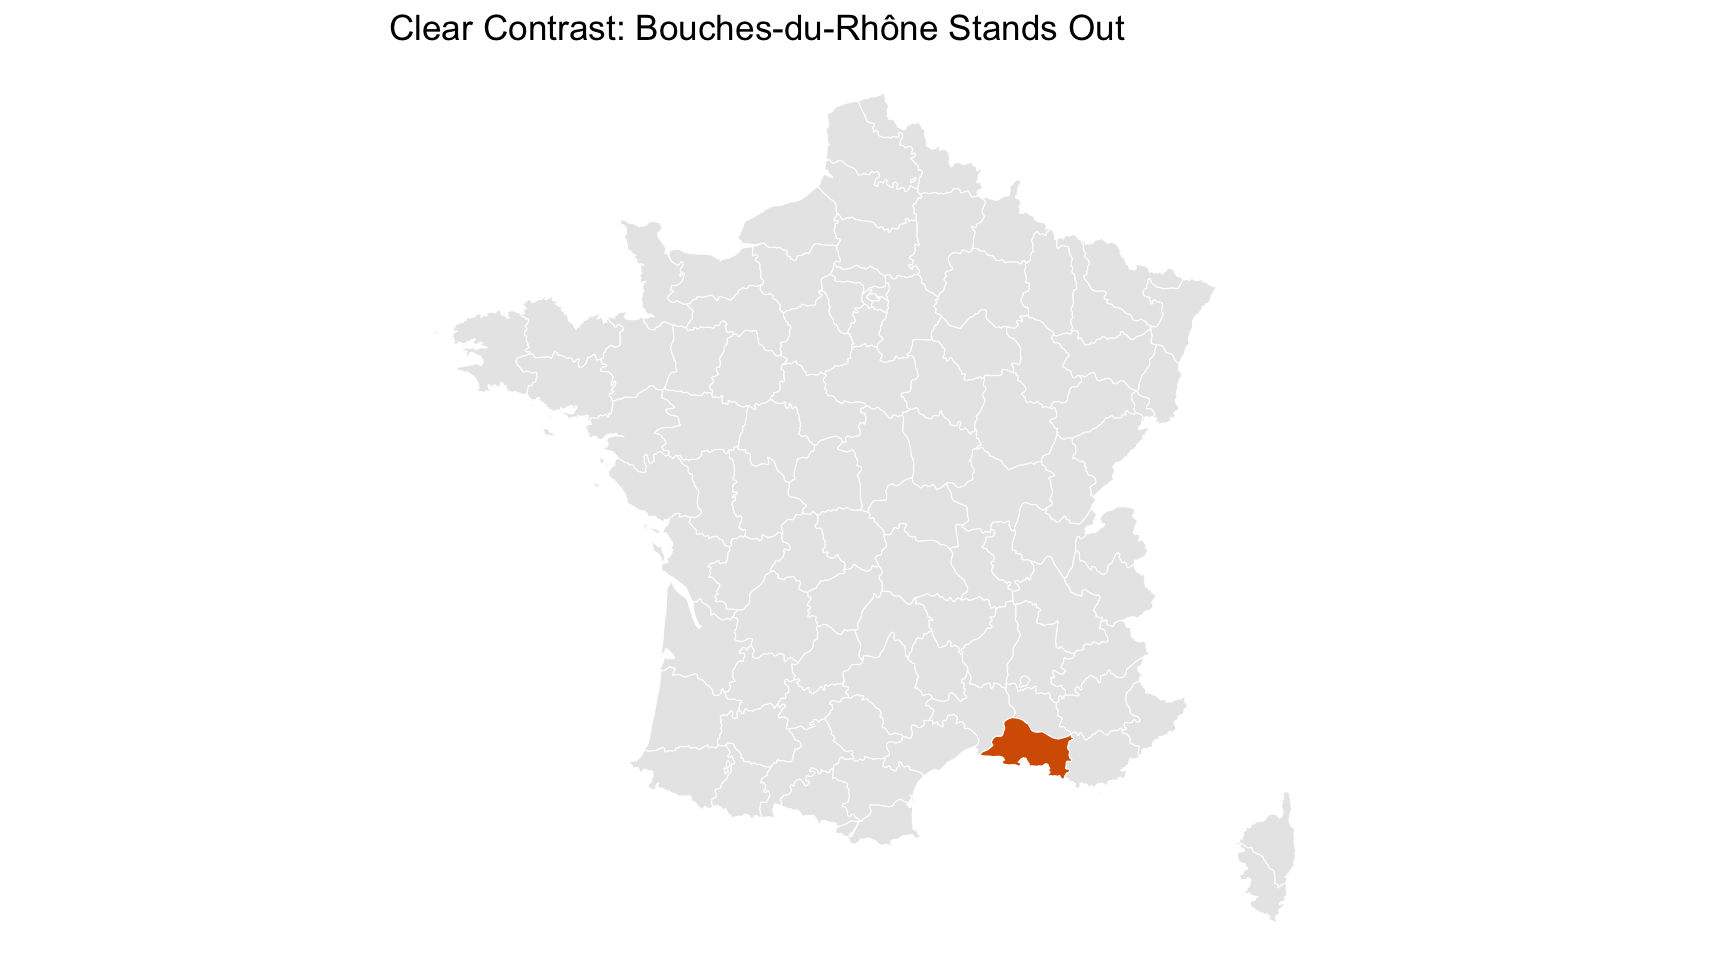
ggplot(data = france_data,mapping =aes(x = long, y = lat, group = group, fill = region =="Bouches-du-Rhone" )) +geom_polygon(colour ="white", linewidth =0.2) +scale_fill_manual(values =c("TRUE"="#D55E00", "FALSE"="#E8E8E8"), guide ="none") +coord_map() +theme_void() +labs(title ="Clear Contrast: Bouches-du-Rhône Stands Out")
On the left: the eye must actively search for the border to identify which region is the intended figure and which is the ground.
On the right: a sharp contrasts resolves the ambiguity.
Figure-Ground on a Map: A Note
This is exactly the same principle behind choosing a highlight colour for one line in a multi-series plot, or one bar in a bar chart.
Recall the example from the Clutterplot slides (from Hanson (2012), shown in Healy (forthcoming)): a highlighted category only works as a highlight if it creates real figure-ground separation from everything else.
Here is a quick checklist you should use when creating a data visualisation:
Proximity: are related elements placed close together, or does spacing accidentally suggest false groups?
Similarity: does colour/shape consistently distinguish the categories that matter?
Connection: would a line (rather than separate points) make the intended series easier to trace?
Enclosure: could facets, panels, or shaded regions group related elements more clearly than colour alone?
Continuity: do crossing or overlapping lines risk misleading the eye about which series is which?
Closure: can gridlines or borders be simplified without losing the perceived structure?
Figure-ground: does the data series stand out clearly against the background, or does it compete with it?
Note that these principles are not arbitrary design taste, they describe how human perception actually works, and every one of the “bad chart” examples earlier in this course violates at least one of them.
References
Alvaredo, Facundo, Lucas Chancel, Thomas Piketty, Emmanuel Saez, and Gabriel Zucman. 2018. “The Elephant Curve of Global Inequality and Growth.”AEA Papers and Proceedings 108 (May): 103–8. https://doi.org/10.1257/pandp.20181073.
Cleveland, William S., and Robert McGill. 1984. “Graphical Perception: Theory, Experimentation, and Application to the Development of Graphical Methods.”Journal of the American Statistical Association 79 (387): 531–54. https://doi.org/10.1080/01621459.1984.10478080.
Few, Stephen. 2004. “Tapping the Power of Visual Perception.”Perceptual Edge 4.
Glasbrenner, James K. 2018. “CDS-101: Introduction to Computational and Data Sciences.” George Mason University. 2018. https://fall18.cds101.com/materials.html.
Hanson, Gordon H. 2012. “The Rise of Middle Kingdoms: Emerging Economies in Global Trade.”Journal of Economic Perspectives 26 (2): 41–64. https://doi.org/10.1257/jep.26.2.41.
Healey, C. G., and J. T. Enns. 2012. “Attention and Visual Memory in Visualization and Computer Graphics.”IEEE Transactions on Visualization and Computer Graphics 18 (7): 1170–88. https://doi.org/10.1109/tvcg.2011.127.
Healy, Kieran. forthcoming. Data Visualization: A Practical Introduction, 2nd Edition. Princeton University Press. https://socviz.co/.
Hewitt, Christopher. 1977. “The Effect of Political Democracy and Social Democracy on Equality in Industrial Societies: A Cross-National Comparison.”American Sociological Review 42 (3): 450. https://doi.org/10.2307/2094750.
Jackman, Robert W. 1980. “The Impact of Outliers on Income Inequality.”American Sociological Review 45 (2): 344. https://doi.org/10.2307/2095134.
Koffka, Kurt. 1935. “Principles of Gestalt Psychology.”
Lin, Kylie, Sean Sheng-Tse Ru, Minsuk Chang, and Cindy Xiong Bearfield. 2026. “beautiVis: An Annotated Visualization Dataset from Reddit’s r/Dataisbeautiful.” In 2026 IEEE 19th Pacific Visualization Conference (PacificVis), 357–62. https://doi.org/10.1109/PacificVis68791.2026.00044.
Nakayama, Ken, and Julian S. Joseph. 1998. “Attention, Pattern Recognition, and Pop-Out in Visual Search.” In The Attentive Brain, edited by Raja Parasuraman, 1st ed. The MIT Press.
Schwabish, Jonathan A. 2014. “An Economist’s Guide to Visualizing Data.”Journal of Economic Perspectives 28 (1): 209–34. https://doi.org/10.1257/jep.28.1.209.
Tufte, Edward R, and Peter R Graves-Morris. 1983. The Visual Display of Quantitative Information. Vol. 2. 9. Graphics press Cheshire, CT.
Wong, Nathan et al. 2021. “Why Two y-Axes (Y2Y): A Case Study for Visual Correlation with Dual Axes.” In 2021 IEEE Visualization Conference (VIS). https://doi.org/10.1109/VIS49827.2021.9373177.
Yang, Brenda W., Camila Vargas Restrepo, Matthew L. Stanley, and Elizabeth J. Marsh. 2021. “Truncating Bar Graphs Persistently Misleads Viewers.”Journal of Applied Research in Memory and Cognition 10 (2): 298–311. https://doi.org/10.1016/j.jarmac.2020.10.002.